Related Experiment Video
Updated: Jul 16, 2025

A Two-interval Forced-choice Task for Multisensory Comparisons
Published on: November 9, 2018
A comparison of brief versus explicit descriptors for verbal rating scales: interrupted time series design
Andrew J Vickers1, Melissa Assel2, Michael Hannon2
1Departments of Epidemiology and Biostatistics (AV, MA, SC), Anesthesiology (PD, TM, BS) and Surgery (MH, JC, SC), Memorial Sloan Kettering Cancer Center, 485 Lexington Ave, 2Nd Floor, New York, NY, 10017, USA. vickersa@mskcc.org.

Background:
Verbal rating scales (VRS) are widely used in patient-reported outcome (PRO) measures. At our institution, patients complete an online instrument using VRSs with a five-point brief response scale to assess symptoms as part of routine follow-up after ambulatory cancer surgery. We received feedback from patients that the brief VRS descriptors such as "mild" or "somewhat" were vague. We added explicit descriptors to our VRSs, for instance, "Mild: I can generally ignore my pain" for pain severity or "Somewhat: I can do some things okay, but most of my daily activities are harder because of fatigue" for fatigue interference. We then compared responses before and after this change was made.
Methods:
The symptoms investigated were pain, fatigue and nausea. Our hypothesis was that the explicit descriptors would reduce overall variance. We therefore compared the coefficient of variation of scores and tested the association between symptoms scores and known predictors thereof. We also compared time to completion between questionnaires with and without the additional descriptors.
Results:
A total of 17,500 patients undergoing 21,497 operations were assigned questionnaires in the period before the descriptors were added; allowing for a short transition period, 1,417 patients having 1436 operations were assigned questionnaires with the additional descriptors. Symptom scores were about 10% lower with the additional descriptors but the coefficient of variation was slightly higher. Moreover, the only statistically significant difference between groups for association with a known predictor favored the item without the additional language for nausea severity (p = 0.004). Total completion time was longer when the instrument included the additional descriptors, particularly the first and second time that the questionnaire was completed.
Conclusions:
Adding descriptors to a VRS of post-operative symptoms did not improve scale properties in patients undergoing ambulatory cancer surgery. We have removed the additional descriptors from our tool. We recommend further comparative psychometric research using data from PROs collected as part of routine clinical care.
Related Concept Videos
 02:01
Group Design
 00:55
Ordinal Level of Measurement
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
 00:55
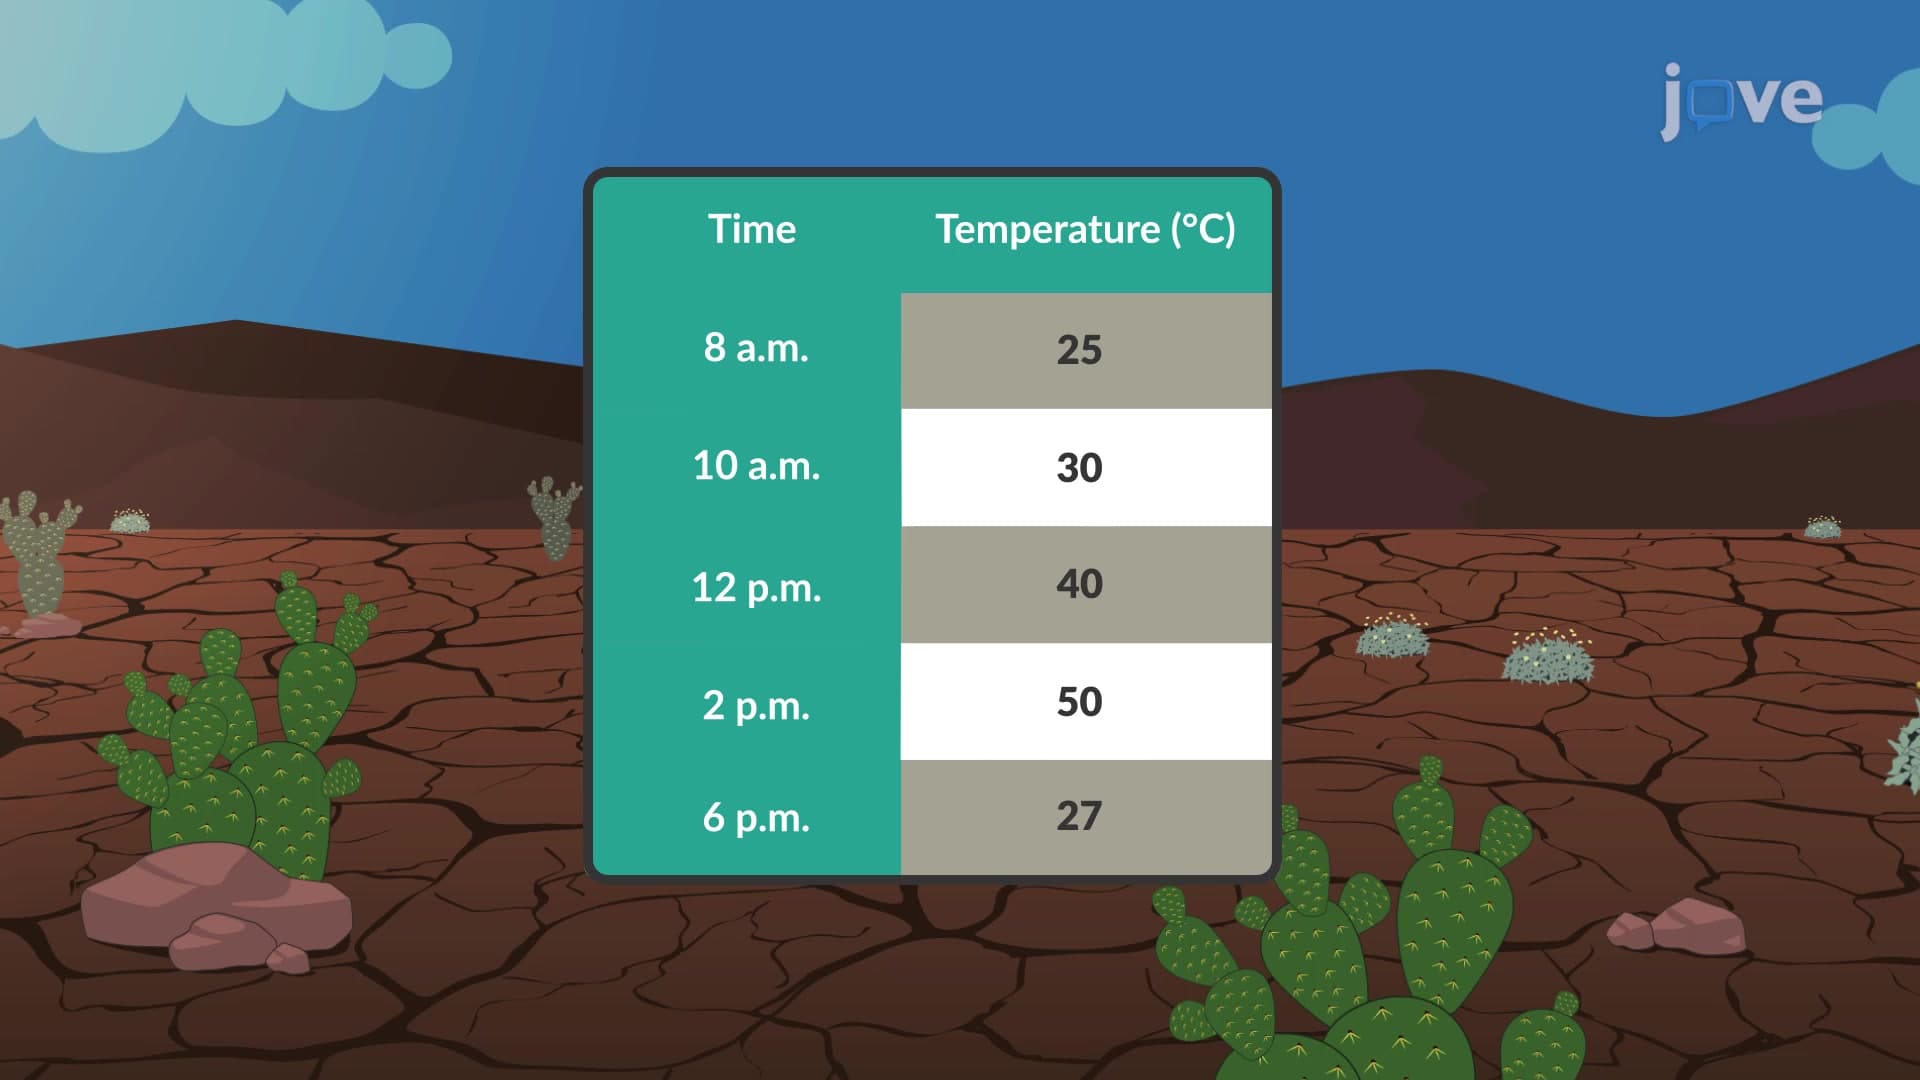
Interval Level of Measurement
Data measured using the interval scale are similar to ordinal level data because they have a definite arrangement. However, in the interval level of measurement, the differences between data values are meaningful even though the data does not have a starting point.
Temperature is measured using the interval scale. It is measurable data, and the difference between...
 01:21
Friedman Two-way Analysis of Variance by Ranks