Learning Hierarchical Modular Networks for Video Captioning
Related Experiment Video
Updated: Jul 12, 2025
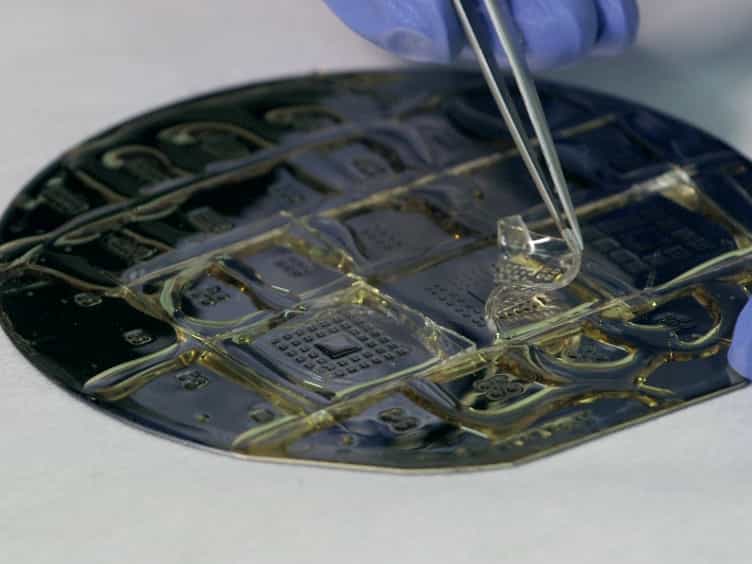
Design, Surface Treatment, Cellular Plating, and Culturing of Modular Neuronal Networks Composed of Functionally Inter-connected Circuits
Published on: April 15, 2015

Abstract:
Video captioning aims to generate natural language descriptions for a given video clip. Existing methods mainly focus on end-to-end representation learning via word-by-word comparison between predicted captions and ground-truth texts. Although significant progress has been made, such supervised approaches neglect semantic alignment between visual and linguistic entities, which may negatively affect the generated captions. In this work, we propose a hierarchical modular network to bridge video representations and linguistic semantics at four granularities before generating captions: entity, verb, predicate, and sentence. Each level is implemented by one module to embed corresponding semantics into video representations. Additionally, we present a reinforcement learning module based on the scene graph of captions to better measure sentence similarity. Extensive experimental results show that the proposed method performs favorably against the state-of-the-art models on three widely-used benchmark datasets, including microsoft research video description corpus (MSVD), MSR-video to text (MSR-VTT), and video-and-TEXt (VATEX).

Related Concept Videos
 01:24
Sequence Networks of Rotating Machines
Zero-sequence current induces a voltage drop across the generator's neutral impedance and other...
 01:18
Hierarchy of Motor Control
 01:22
Multi-input and Multi-variable systems
In the absence...
 01:31
Classification of Systems-II
 01:20
Structural Classification of Joints
A fibrous joint is where the adjacent bones are united by fibrous connective...
 01:26
Classification of Systems-I
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as: