Related Experiment Video
Updated: Jul 11, 2025

Heterogeneity Mapping of Protein Expression in Tumors using Quantitative Immunofluorescence
Published on: October 25, 2011
Avoiding common mistakes in meta-analysis: Understanding the distinct roles of Q, I-squared, tau-squared, and the
1Biostat, Inc., Englewood, New Jersey, USA.

Abstract:
In any meta-analysis, it is critically important to report the dispersion in effects as well as the mean effect. If an intervention has a moderate clinical impact on average we also need to know if the impact is moderate for all relevant populations, or if it varies from trivial in some to major in others. Or indeed, if the intervention is beneficial in some cases but harmful in others. Researchers typically report a series of statistics such as the Q-value, the p-value, and I2 , which are intended to address this issue. Often, they use these statistics to classify the heterogeneity as being low, moderate, or high and then use these classifications when considering the potential utility of the intervention. While this practice is ubiquitous, it is nevertheless incorrect. The statistics mentioned above do not actually tell us how much the effect size varies. Classifications of heterogeneity based on these statistics are uninformative at best, and often misleading. My goal in this paper is to explain what these statistics do tell us, and that none of them tells us how much the effect size varies. Then I will introduce the prediction interval, the statistic that does tell us how much the effect size varies, and that addresses the question we have in mind when we ask about heterogeneity. This paper is adapted from a chapter in "Common Mistakes in Meta-Analysis and How to Avoid Them." A free PDF of the book is available at https://www.Meta-Analysis.com/rsm.
More Related Videos
 08:36
Author Spotlight: Evaluating the Adjuvant Efficacy and Safety of Angong Niuhuang Pill in Viral Encephalitis Treatment
Published on: April 19, 2024
 06:26
Meta-analysis of Voxel-Based Neuroimaging Studies using Seed-based d Mapping with Permutation of Subject Images SDM-PSI
Published on: November 27, 2019
Related Concept Videos
 01:23
Test for Homogeneity
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:00
Detection of Gross Error: The Q Test
 01:19
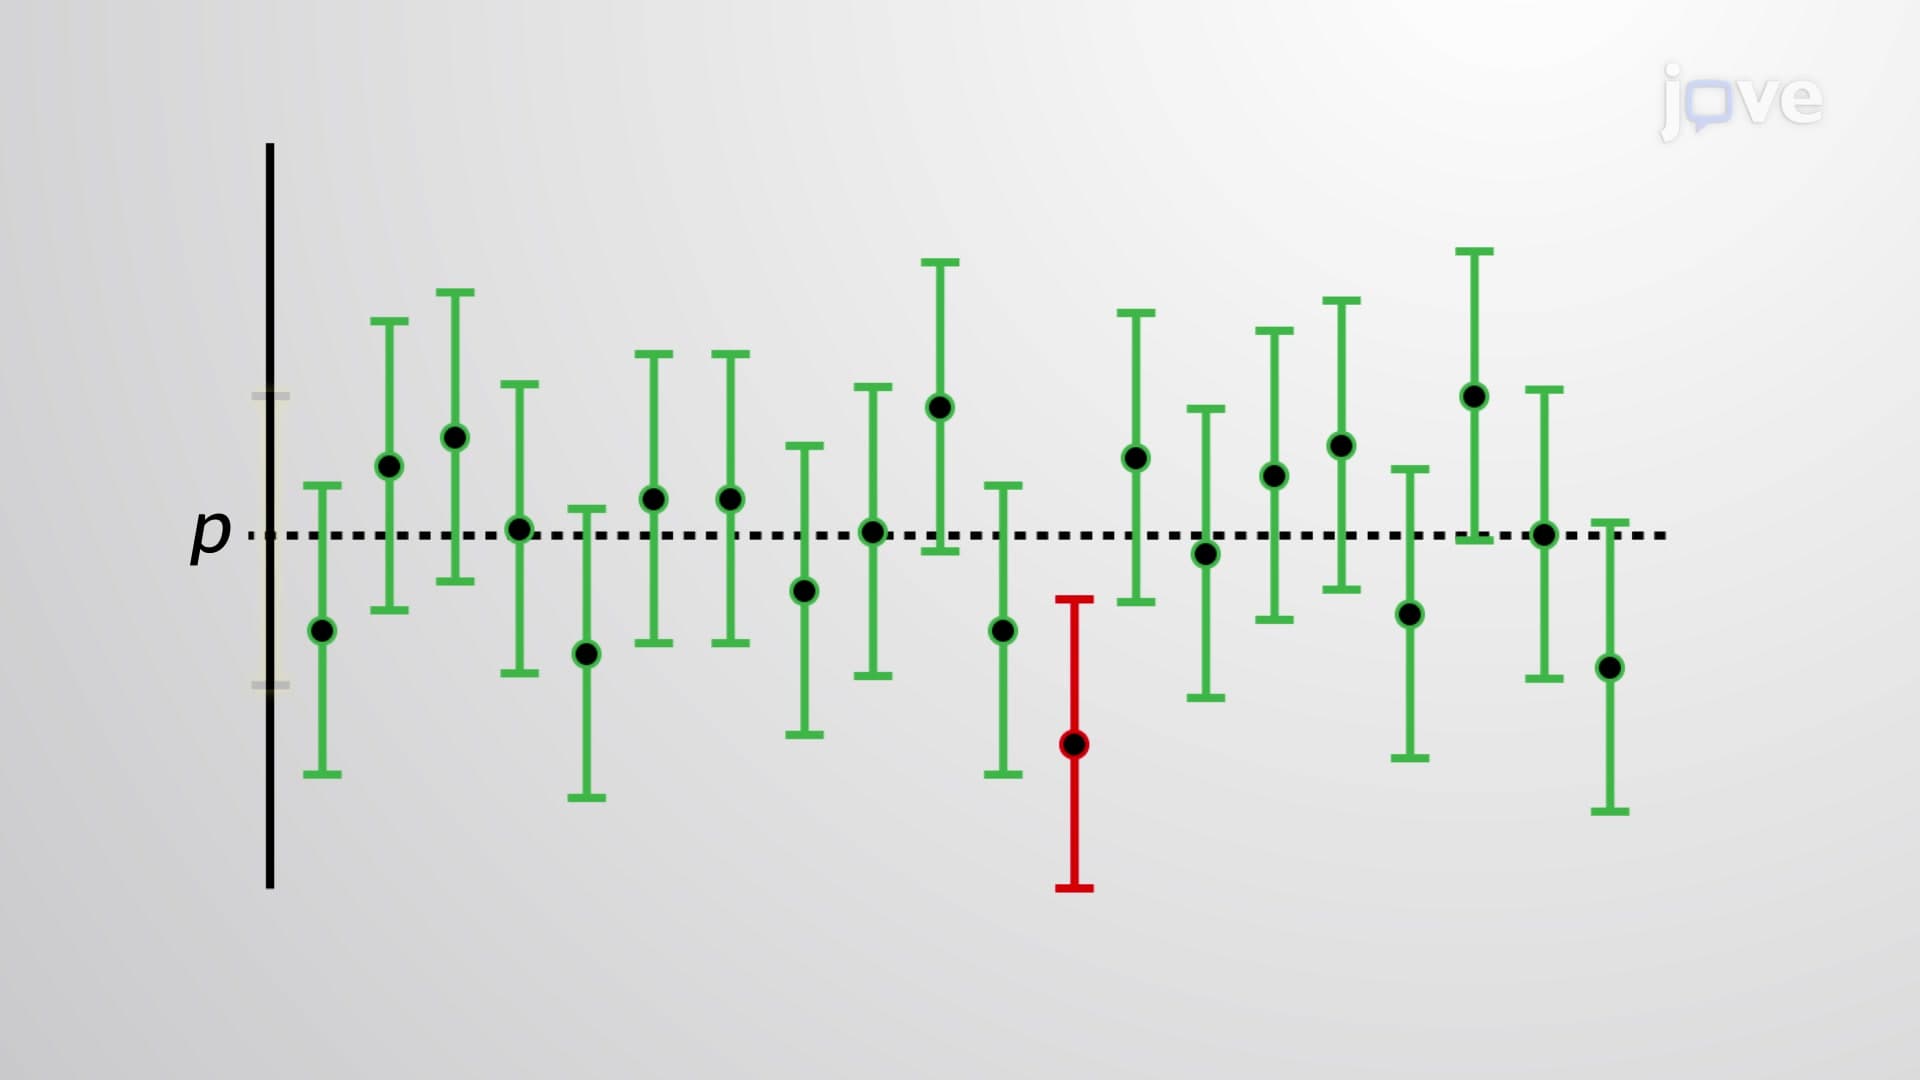
Interpretation of Confidence Intervals
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
 01:04
Significance Testing: Overview