Related Experiment Video
Updated: Jul 11, 2025


Author Spotlight: Advancing Alzheimer's Research – Exploring Early Detection and Multi-Omics Approaches
Published on: December 15, 2023
Node embedding-based graph autoencoder outlier detection for adverse pregnancy outcomes
Wasif Khan1, Nazar Zaki2,3, Amir Ahmad4
1Department of Computer Science and Software Engineering, College of Information Technology, United Arab Emirates University, P.O. Box 15551, Al Ain, United Arab Emirates.

Adverse pregnancy outcomes, such as low birth weight (LBW) and preterm birth (PTB), can have serious consequences for both the mother and infant. Early prediction of such outcomes is important for their prevention. Previous studies using traditional machine learning (ML) models for predicting PTB and LBW have encountered two important limitations: extreme class imbalance in medical datasets and the inability to account for complex relational structures between entities. To address these limitations, we propose a node embedding-based graph outlier detection algorithm to predict adverse pregnancy outcomes. We developed a knowledge graph using a well-curated representative dataset of the Emirati population and two node embedding algorithms. The graph autoencoder (GAE) was trained by applying a combination of original risk factors and node embedding features. Samples that were difficult to reconstruct at the output of GAE were identified as outliers considered representing PTB and LBW samples. Our experiments using LBW, PTB, and very PTB datasets demonstrated that incorporating node embedding considerably improved performance, achieving a 12% higher AUC-ROC compared to traditional GAE. Our study demonstrates the effectiveness of node embedding and graph outlier detection in improving the prediction performance of adverse pregnancy outcomes in well-curated population datasets.
Adverse pregnancy outcomes, such as low birth weight (LBW) and preterm birth (PTB), can have serious consequences for both the mother and infant. Early prediction of such outcomes is important for their prevention. Previous studies using traditional machine learning (ML) models for predicting PTB and LBW have encountered two important limitations: extreme class imbalance in medical datasets and the inability to account for complex relational structures between entities. To address these limitations, we propose a node embedding-based graph outlier detection algorithm to predict adverse pregnancy outcomes. We developed a knowledge graph using a well-curated representative dataset of the Emirati population and two node embedding algorithms. The graph autoencoder (GAE) was trained by applying a combination of original risk factors and node embedding features. Samples that were difficult to reconstruct at the output of GAE were identified as outliers considered representing PTB and LBW samples. Our experiments using LBW, PTB, and very PTB datasets demonstrated that incorporating node embedding considerably improved performance, achieving a 12% higher AUC-ROC compared to traditional GAE. Our study demonstrates the effectiveness of node embedding and graph outlier detection in improving the prediction performance of adverse pregnancy outcomes in well-curated population datasets.
Related Concept Videos
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:12
What Are Outliers?
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
 01:08
Outliers and Influential Points
 01:07
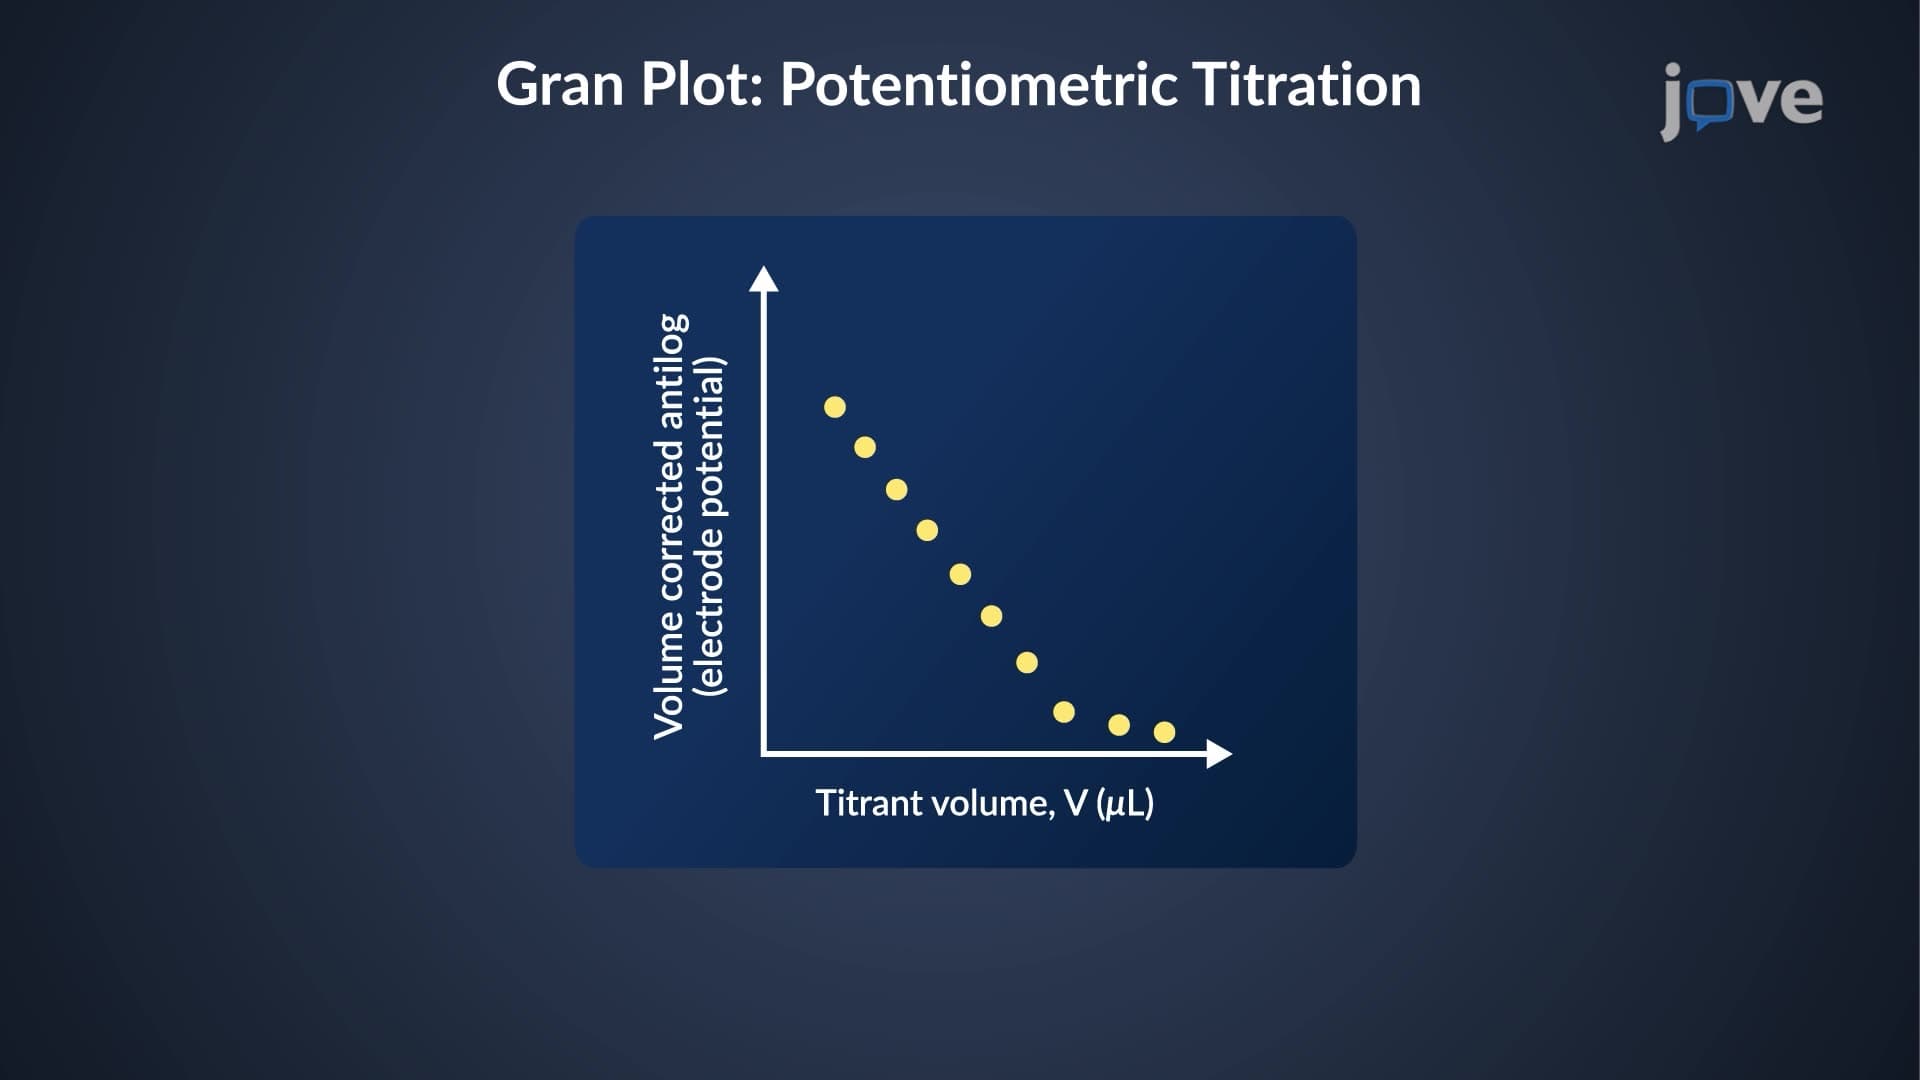
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:00
Detection of Gross Error: The Q Test
 01:25
Statistical Methods for Analyzing Epidemiological Data