Related Experiment Video
Updated: Jul 11, 2025

Swin-PSAxialNet: An Efficient Multi-Organ Segmentation Technique
Published on: July 5, 2024
Nunchaku: optimally partitioning data into piece-wise contiguous segments
Yu Huo1,2, Hongpei Li2, Xiao Wang2
1Centre for Engineering Biology, University of Edinburgh, Edinburgh EH9 3BF, United Kingdom.

Motivation:
When analyzing 1D time series, scientists are often interested in identifying regions where one variable depends linearly on the other. Typically, they use an ad hoc and therefore often subjective method to do so.
Results:
Here, we develop a statistically rigorous, Bayesian approach to infer the optimal partitioning of a dataset not only into contiguous piece-wise linear segments, but also into contiguous segments described by linear combinations of arbitrary basis functions. We therefore present a general solution to the problem of identifying discontinuous change points. Focusing on microbial growth, we use the algorithm to find the range of optical density where this density is linearly proportional to the number of cells and to automatically find the regions of exponential growth for both Escherichia coli and Saccharomyces cerevisiae. For budding yeast, we consequently are able to infer the Monod constant for growth on fructose. Our algorithm lends itself to automation and high throughput studies, increases reproducibility, and should facilitate data analyses for a broad range of scientists.
Availability And Implementation:
The corresponding Python package, entitled Nunchaku, is available at PyPI: https://pypi.org/project/nunchaku.
Related Concept Videos
 01:14
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:10
Interpreting ¹H NMR Signal Splitting: The (n + 1) Rule
 01:16
Stratified Sampling Method
To choose a stratified sample, divide the population into groups called strata and then take a...
 01:12
Maximum Size of Aggregate
 01:15
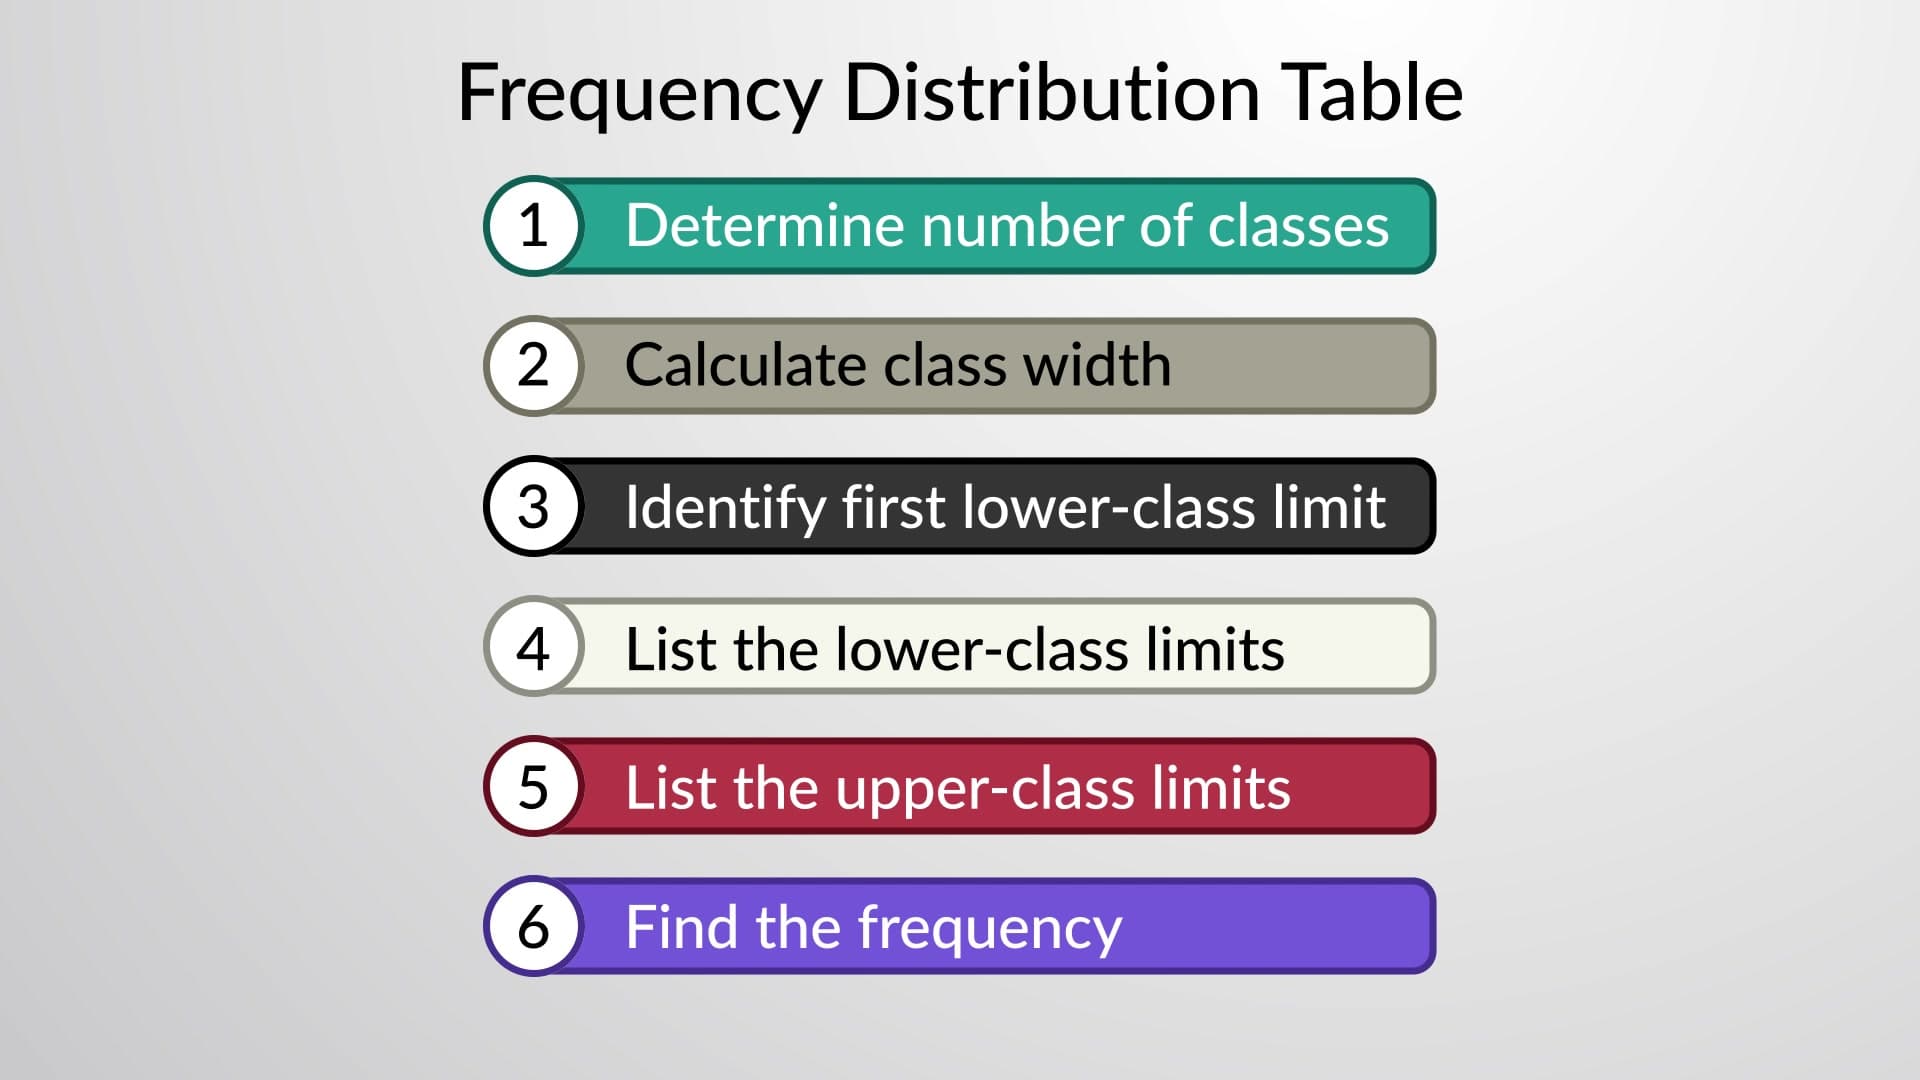
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is...
 01:26
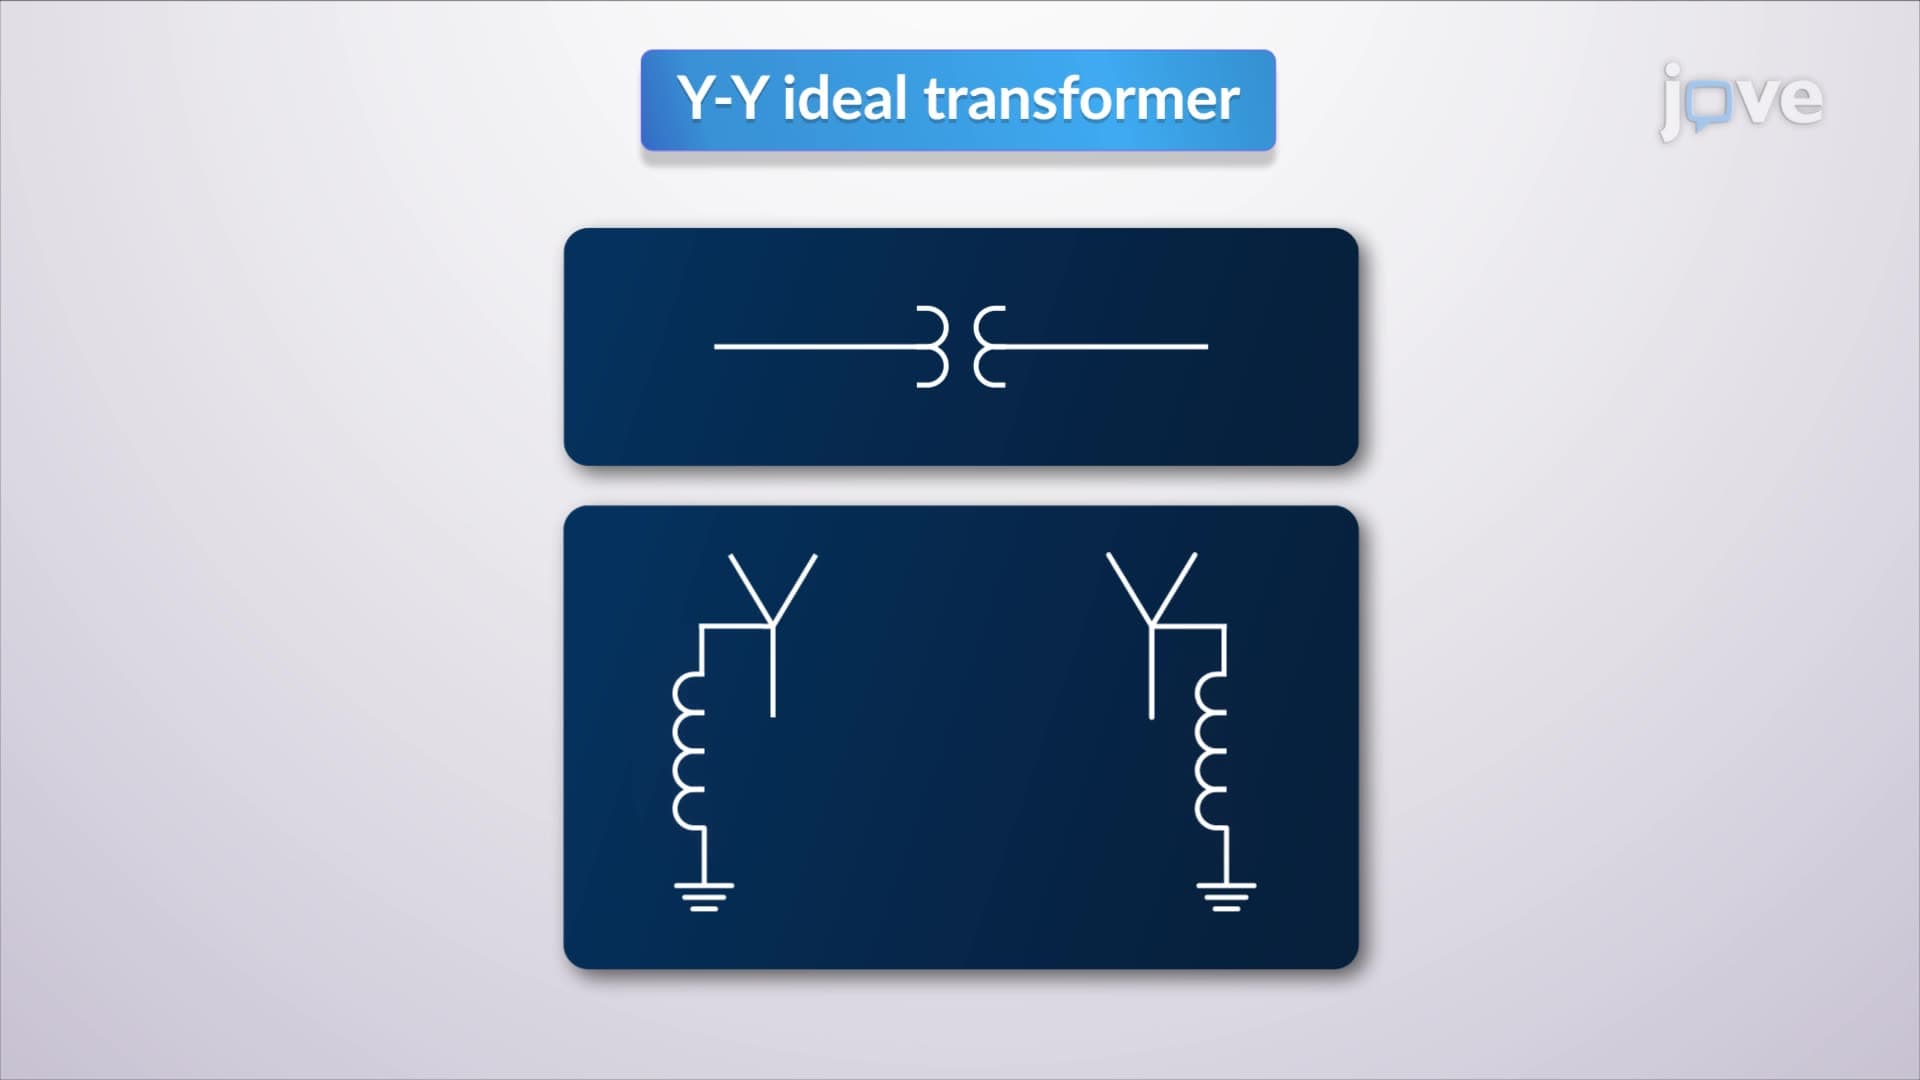
Per-Unit Sequence Models
Zero-sequence currents, which are identical in magnitude and phase, generate a neutral current, resulting in voltage drops across the neutral impedance and the low-voltage winding. If the...