Related Experiment Video
Updated: Jul 7, 2025
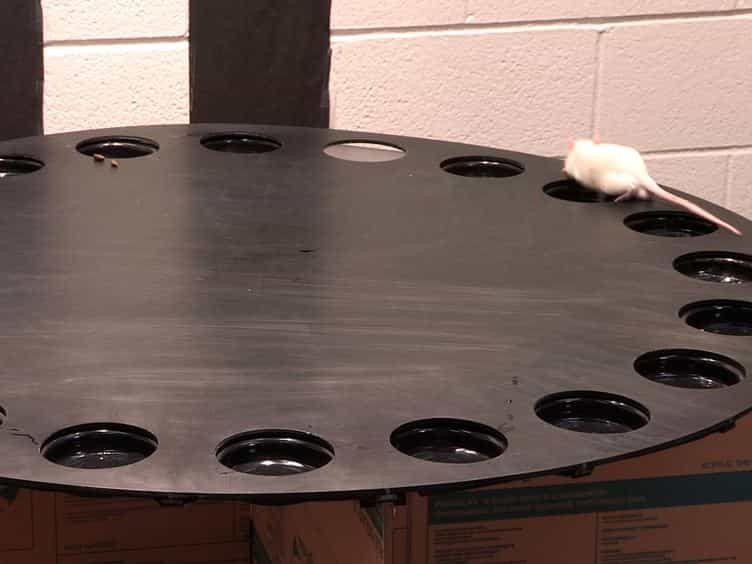

Barnes Maze Testing Strategies with Small and Large Rodent Models
Published on: February 26, 2014
MERIT: Controlling Monte-Carlo error rate in large-scale Monte-Carlo hypothesis testing
Yunxiao Li1, Yi-Juan Hu1, Glen A Satten2
1Department of Biostatistics and Bioinformatics, Emory University, Atlanta, Georgia, USA.

Abstract:
The use of Monte-Carlo (MC) -values when testing the significance of a large number of hypotheses is now commonplace. In large-scale hypothesis testing, we will typically encounter at least some -values near the threshold of significance, which require a larger number of MC replicates than -values that are far from the threshold. As a result, some incorrect conclusions can be reached due to MC error alone; for hypotheses near the threshold, even a very large number (eg, ) of MC replicates may not be enough to guarantee conclusions reached using MC -values. Gandy and Hahn (GH)6-8 have developed the only method that directly addresses this problem. They defined a Monte-Carlo error rate (MCER) to be the probability that any decisions on accepting or rejecting a hypothesis based on MC -values are different from decisions based on ideal -values; their method then makes decisions by controlling the MCER. Unfortunately, the GH method is frequently very conservative, often making no rejections at all and leaving a large number of hypotheses "undecided". In this article, we propose MERIT, a method for large-scale MC hypothesis testing that also controls the MCER but is more statistically efficient than the GH method. Through extensive simulation studies, we demonstrate that MERIT controls the MCER while making more decisions that agree with the ideal -values than GH does. We also illustrate our method by an analysis of gene expression data from a prostate cancer study.
More Related Videos

Related Concept Videos
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...
 01:14
Errors In Hypothesis Tests
 01:11
Types of Hypothesis Testing
When the null and alternative hypotheses are stated, it is observed that the null hypothesis is a neutral statement against which the alternative hypothesis is tested. The alternative hypothesis is a claim that instead has a certain direction. If the null hypothesis claims that p = 0.5, the alternative hypothesis would be an opposing statement to this and can be put either p > 0.5, p < 0.5, or p...
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...