Statistical inference for dependence networks in topological data analysis
Related Experiment Video
Updated: Jul 6, 2025
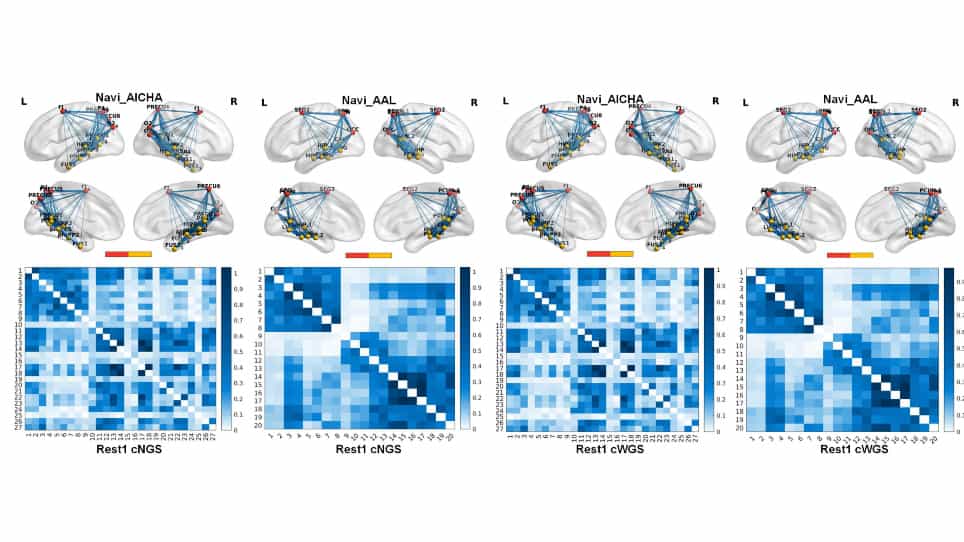
Modeling the Functional Network for Spatial Navigation in the Human Brain
Published on: October 13, 2023
Anass B El-Yaagoubi1, Moo K Chung2, Hernando Ombao1
1Statistics Program, King Abdullah University of Science and Technology, Thuwal, Saudi Arabia.

Abstract:
Topological data analysis (TDA) provide tools that are becoming increasingly popular for analyzing multivariate time series data. One key aspect in analyzing multivariate time series is dependence between components. One application is on brain signal analysis. In particular, various dependence patterns in brain networks may be linked to specific tasks and cognitive processes. These dependence patterns may be altered by various neurological and cognitive impairments such as Alzheimer's and Parkinson's diseases, as well as attention deficit hyperactivity disorder (ADHD). Because there is no ground-truth with known dependence patterns in real brain signals, testing new TDA methods on multivariate time series is still a challenge. Our goal here is to develop novel statistical inference procedures via simulations. Simulations are useful for generating some null distributions of a test statistic (for hypothesis testing), forming confidence regions, and for evaluating the performance of proposed TDA methods. To the best of our knowledge, there are no methods that simulate multivariate time series data with potentially complex user-specified connectivity patterns. In this paper we present a novel approach to simulate multivariate time series with specific number of cycles/holes in its dependence network. Furthermore, we also provide a procedure for generating higher dimensional topological features.
Related Concept Videos
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:21
Introduction to Test of Independence
The test statistic for a test of independence is similar to that of a goodness-of-fit test:
 01:16
Hypothesis Test for Test of Independence
H0: The two variables (factors)...
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:21
Friedman Two-way Analysis of Variance by Ranks