Pruning Self-Attentions Into Convolutional Layers in Single Path
Related Experiment Video
Updated: Jul 5, 2025

Author Spotlight: Enhancement of Salient Object Detection for Smart Grid Applications
Published on: December 15, 2023

Abstract:
Vision Transformers (ViTs) have achieved impressive performance over various computer vision tasks. However, modeling global correlations with multi-head self-attention (MSA) layers leads to two widely recognized issues: the massive computational resource consumption and the lack of intrinsic inductive bias for modeling local visual patterns. To solve both issues, we devise a simple yet effective method named Single-Path Vision Transformer pruning (SPViT), to efficiently and automatically compress the pre-trained ViTs into compact models with proper locality added. Specifically, we first propose a novel weight-sharing scheme between MSA and convolutional operations, delivering a single-path space to encode all candidate operations. In this way, we cast the operation search problem as finding which subset of parameters to use in each MSA layer, which significantly reduces the computational cost and optimization difficulty, and the convolution kernels can be well initialized using pre-trained MSA parameters. Relying on the single-path space, we introduce learnable binary gates to encode the operation choices in MSA layers. Similarly, we further employ learnable gates to encode the fine-grained MLP expansion ratios of FFN layers. In this way, our SPViT optimizes the learnable gates to automatically explore from a vast and unified search space and flexibly adjust the MSA-FFN pruning proportions for each individual dense model. We conduct extensive experiments on two representative ViTs showing that our SPViT achieves a new SOTA for pruning on ImageNet-1 k. For example, our SPViT can trim 52.0% FLOPs for DeiT-B and get an impressive 0.6% top-1 accuracy gain simultaneously.

Related Concept Videos
 01:23
Propagation of Action Potentials
Neurons (nerve cells) have a resting membrane potential, with a slightly negative charge inside compared to outside. This is maintained by ion channels, such as sodium (Na+) and potassium (K+) channels, which control the flow of ions. When a stimulus, like a touch or a signal from another neuron, triggers the neuron, sodium channels open, allowing sodium ions to...
 01:25
Neural Circuits
Neuronal pools are collections of nerve cells with similar functions and interact through chemical and electrical signals. These pools include both interneurons (the central neural circuit nodes that...
 01:17
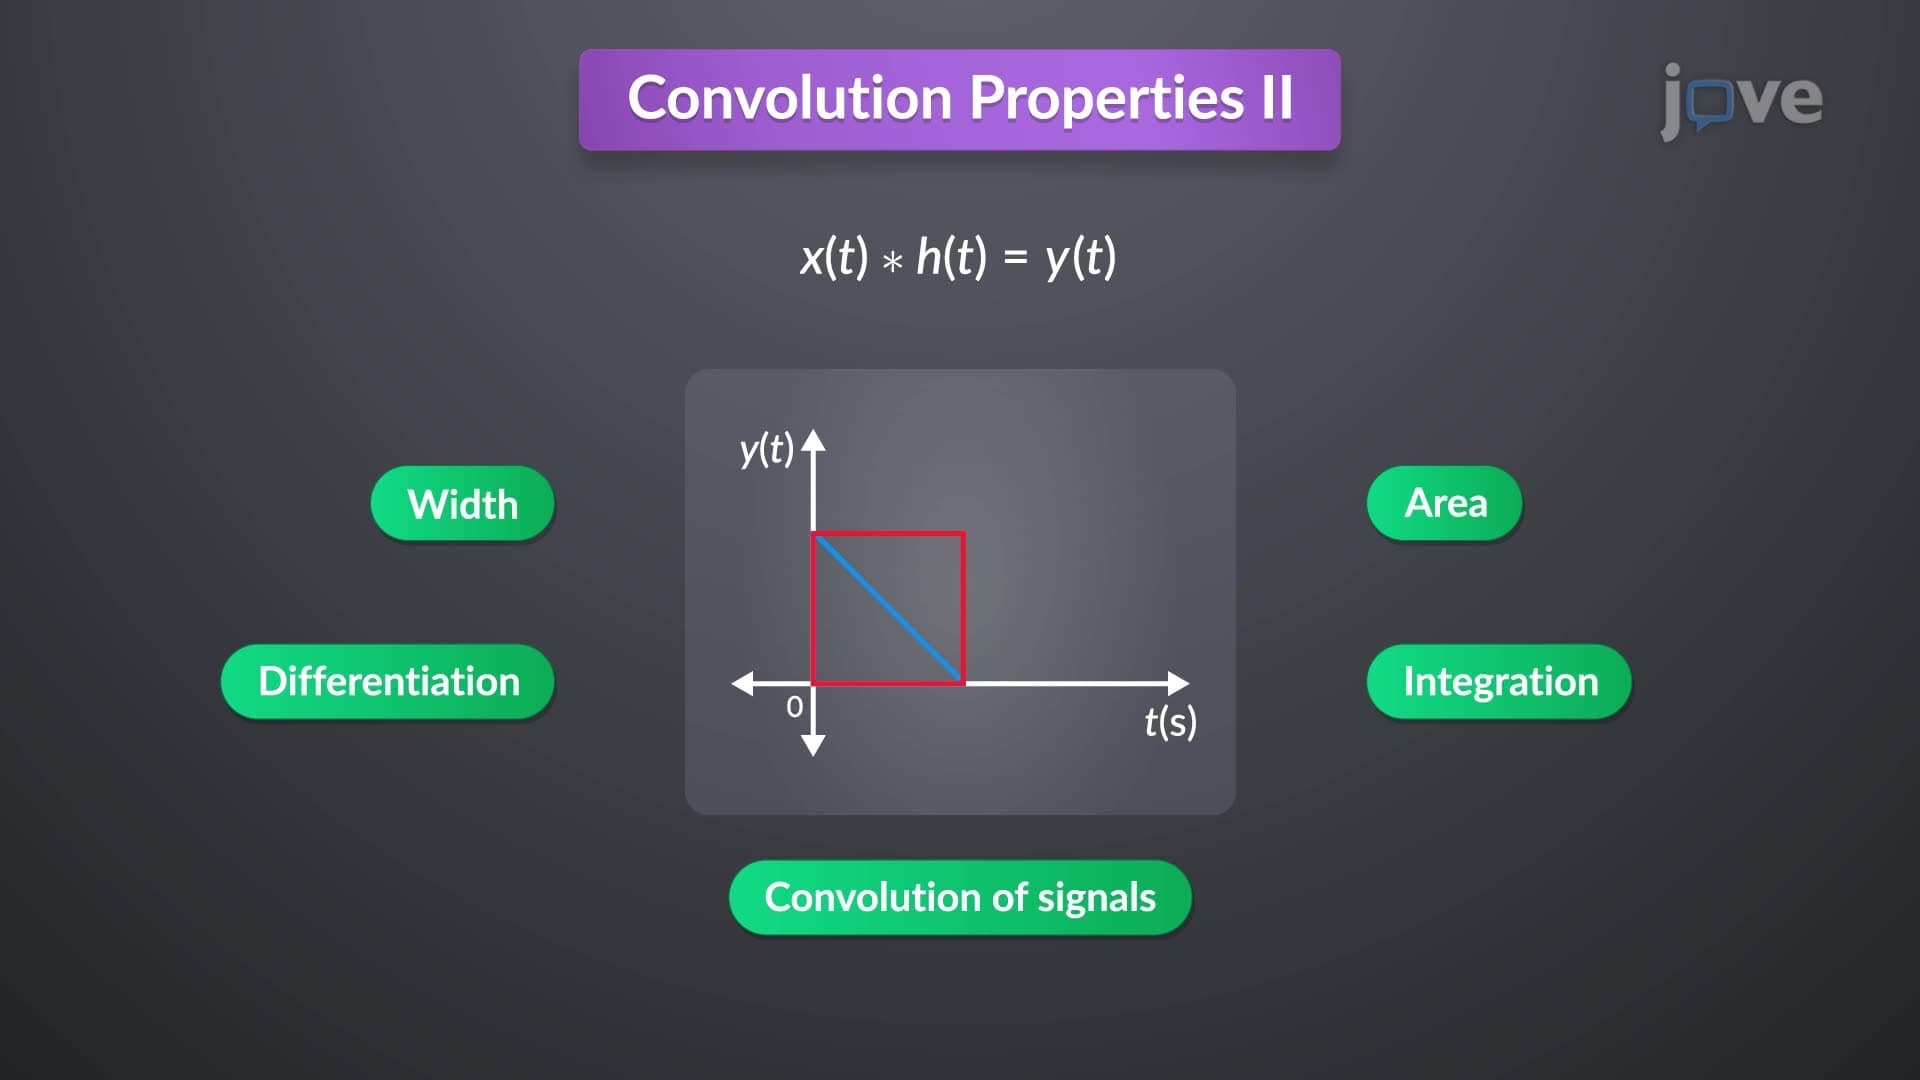
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:20
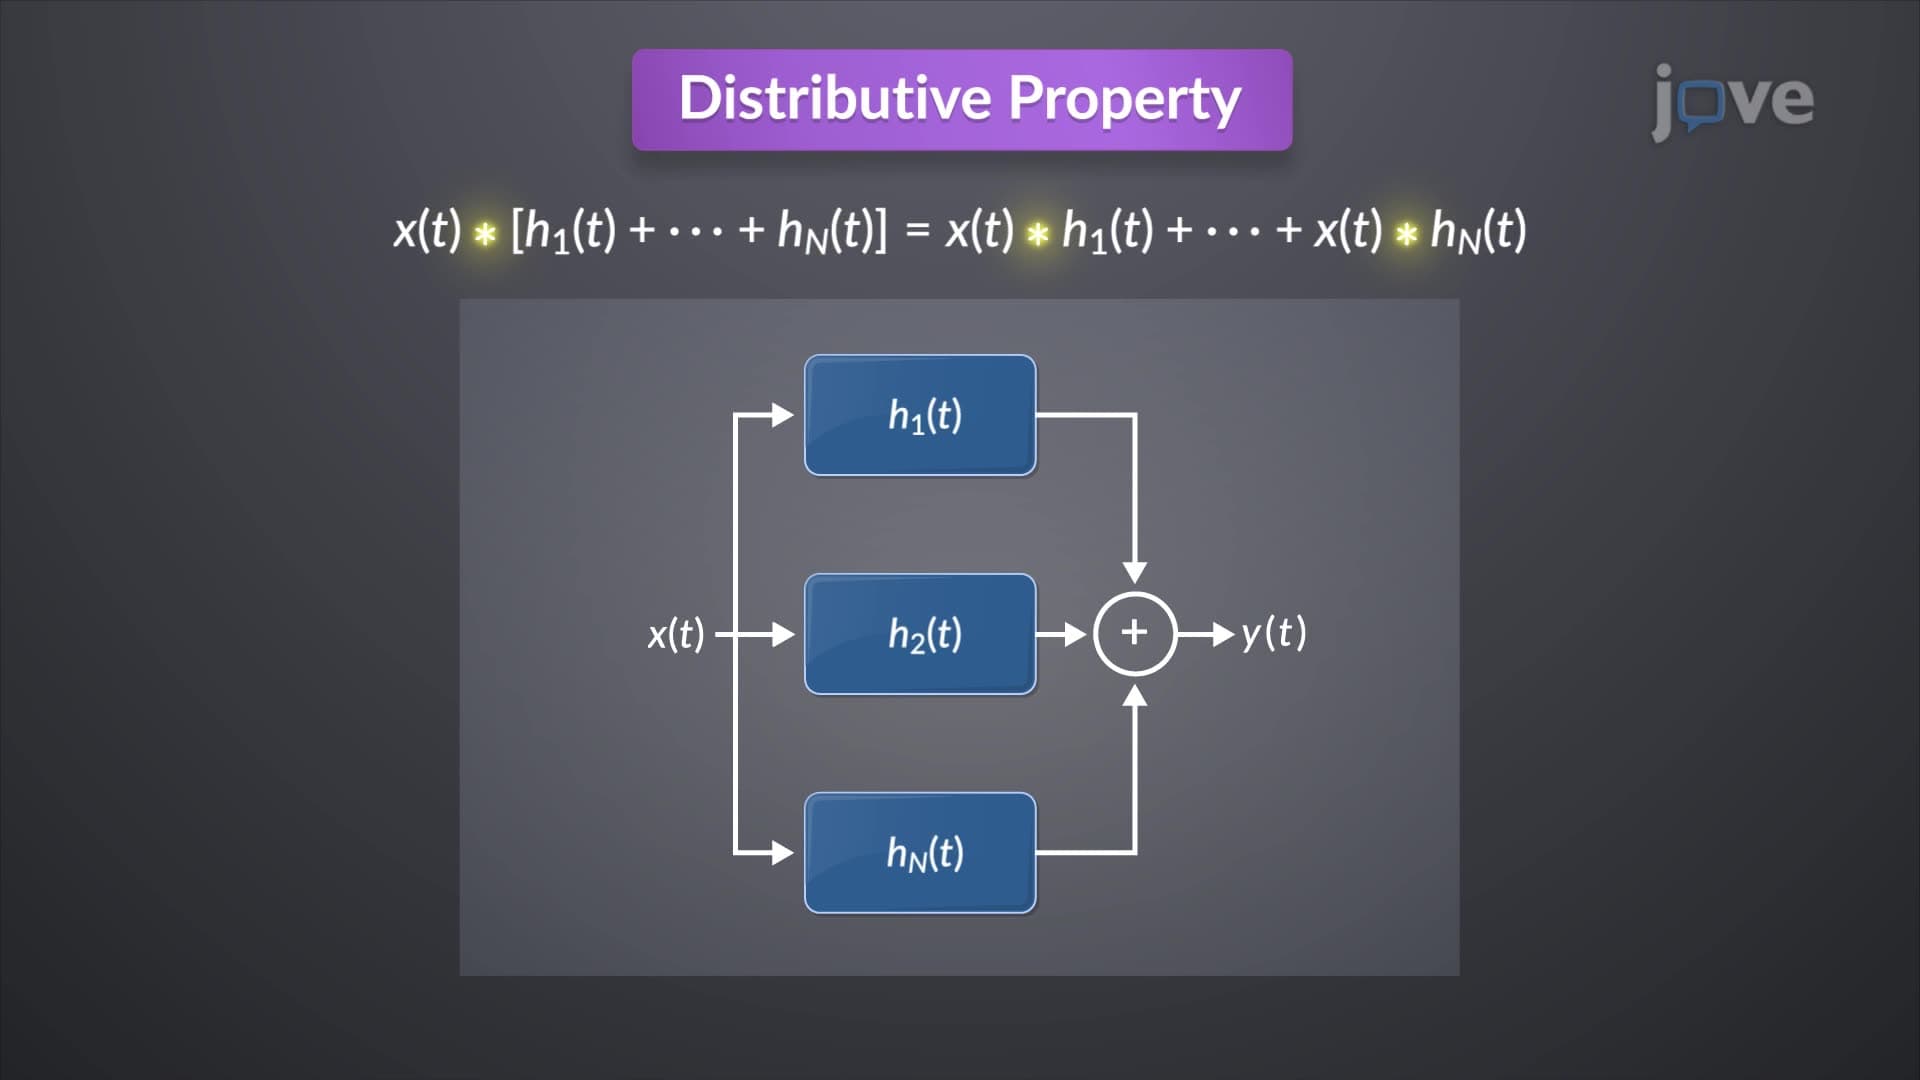
Convolution Properties I
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
 01:20
Parallel Processing
 01:15
Auditory Pathway
When viewed cross-sectionally, the cochlea reveals the scala vestibuli and scala tympani flanking...