MDEformer: Mixed Difference Equation Inspired Transformer for Compressed Video Quality Enhancement
Related Experiment Video
Updated: Jul 4, 2025
Compact Lens-less Digital Holographic Microscope for MEMS Inspection and Characterization
Published on: July 5, 2016

Abstract:
Deep learning methods have achieved impressive performance in compressed video quality enhancement tasks. However, these methods rely excessively on practical experience by manually designing the network structure and do not fully exploit the potential of the feature information contained in the video sequences, i.e., not taking full advantage of the multiscale similarity of the compressed artifact information and not seriously considering the impact of the partition boundaries in the compressed video on the overall video quality. In this article, we propose a novel Mixed Difference Equation inspired Transformer (MDEformer) for compressed video quality enhancement, which provides a relatively reliable principle to guide the network design and yields a new insight into the interpretable transformer. Specifically, drawing on the graphical concept of the mixed difference equation (MDE), we utilize multiple cross-layer cross-attention aggregation (CCA) modules to establish long-range dependencies between encoders and decoders of the transformer, where partition boundary smoothing (PBS) modules are inserted as feedforward networks. The CCA module can make full use of the multiscale similarity of compression artifacts to effectively remove compression artifacts, and recover the texture and detail information of the frame. The PBS module leverages the sensitivity of smoothing convolution to partition boundaries to eliminate the impact of partition boundaries on the quality of compressed video and improve its overall quality, while not having too much impacts on non-boundary pixels. Extensive experiments on the MFQE 2.0 dataset demonstrate that the proposed MDEformer can eliminate compression artifacts for improving the quality of the compressed video, and surpasses the state-of-the-arts (SOTAs) in terms of both objective metrics and visual quality.
Related Concept Videos
 01:24
Difference Equation Solution using z-Transform
The z-transform facilitates handling delayed signals by shifting the signal in the z-domain, which corresponds to delaying the signal in the time domain, and advancing signals by similarly shifting in the...
 01:10
Reconstruction of Signal using Interpolation
 01:16
Types Of Transformers
If the ratio of the number of turns in the secondary winding to that of the primary winding is greater than one, then the transformer is said to be a step-up transformer. In a step-up transformer, the voltage at the secondary winding is greater than the voltage applied at the primary winding.
However, if this ratio is less than one, the transformer is said to be a step-down...
 01:26
The Ideal Transformer
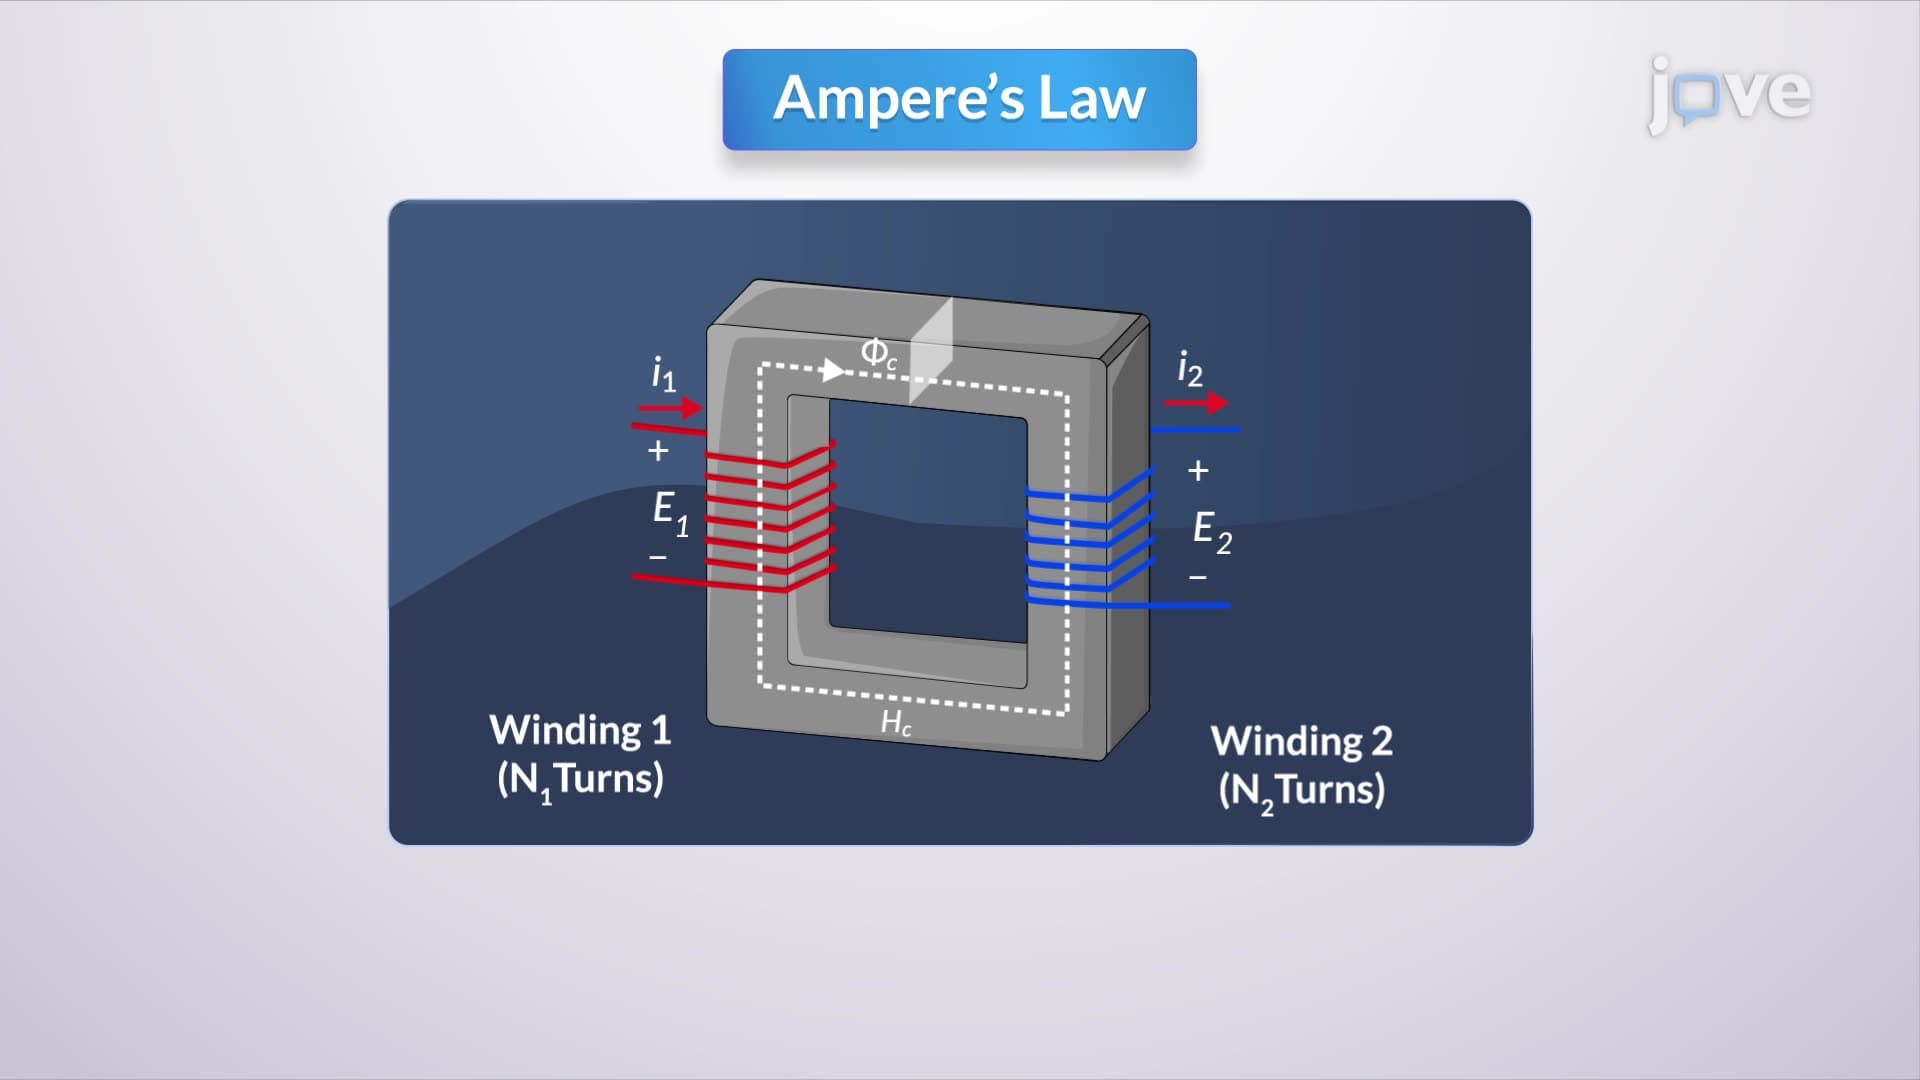
Ampere's Law forms the basis of understanding the magnetic field within the transformer. It states that the integral of the magnetic field intensity's...
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss...
 01:21
Energy Losses in Transformers
There are four main reasons for energy losses in transformers.
The first cause can be the high resistance of the...