Related Experiment Video
Updated: Jul 2, 2025

Deep Neural Networks for Image-Based Dietary Assessment
Published on: March 13, 2021
Randomness Regularization With Simple Consistency Training for Neural Networks

Abstract:
Randomness is widely introduced in neural network training to simplify model optimization or avoid the over-fitting problem. Among them, dropout and its variations in different aspects (e.g., data, model structure) are prevalent in regularizing the training of deep neural networks. Though effective and performing well, the randomness introduced by these dropout-based methods causes nonnegligible inconsistency between training and inference. In this paper, we introduce a simple consistency training strategy to regularize such randomness, namely R-Drop, which forces two output distributions sampled by each type of randomness to be consistent. Specifically, R-Drop minimizes the bidirectional KL-divergence between two output distributions produced by dropout-based randomness for each training sample. Theoretical analysis reveals that R-Drop can reduce the above inconsistency by reducing the inconsistency among the sampled sub structures and bridging the gap between the loss calculated by the full model and sub structures. Experiments on 7 widely-used deep learning tasks ( 23 datasets in total) demonstrate that R-Drop is universally effective for different types of neural networks (i.e., feed-forward, recurrent, and graph neural networks) and different learning paradigms (supervised, parameter-efficient, and semi-supervised). In particular, it achieves state-of-the-art performances with the vanilla Transformer model on WMT14 English → German translation ( 30.91 BLEU) and WMT14 English → French translation ( 43.95 BLEU), even surpassing models trained with extra large-scale data and expert-designed advanced variants of Transformer models.
More Related Videos
Related Concept Videos
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:09
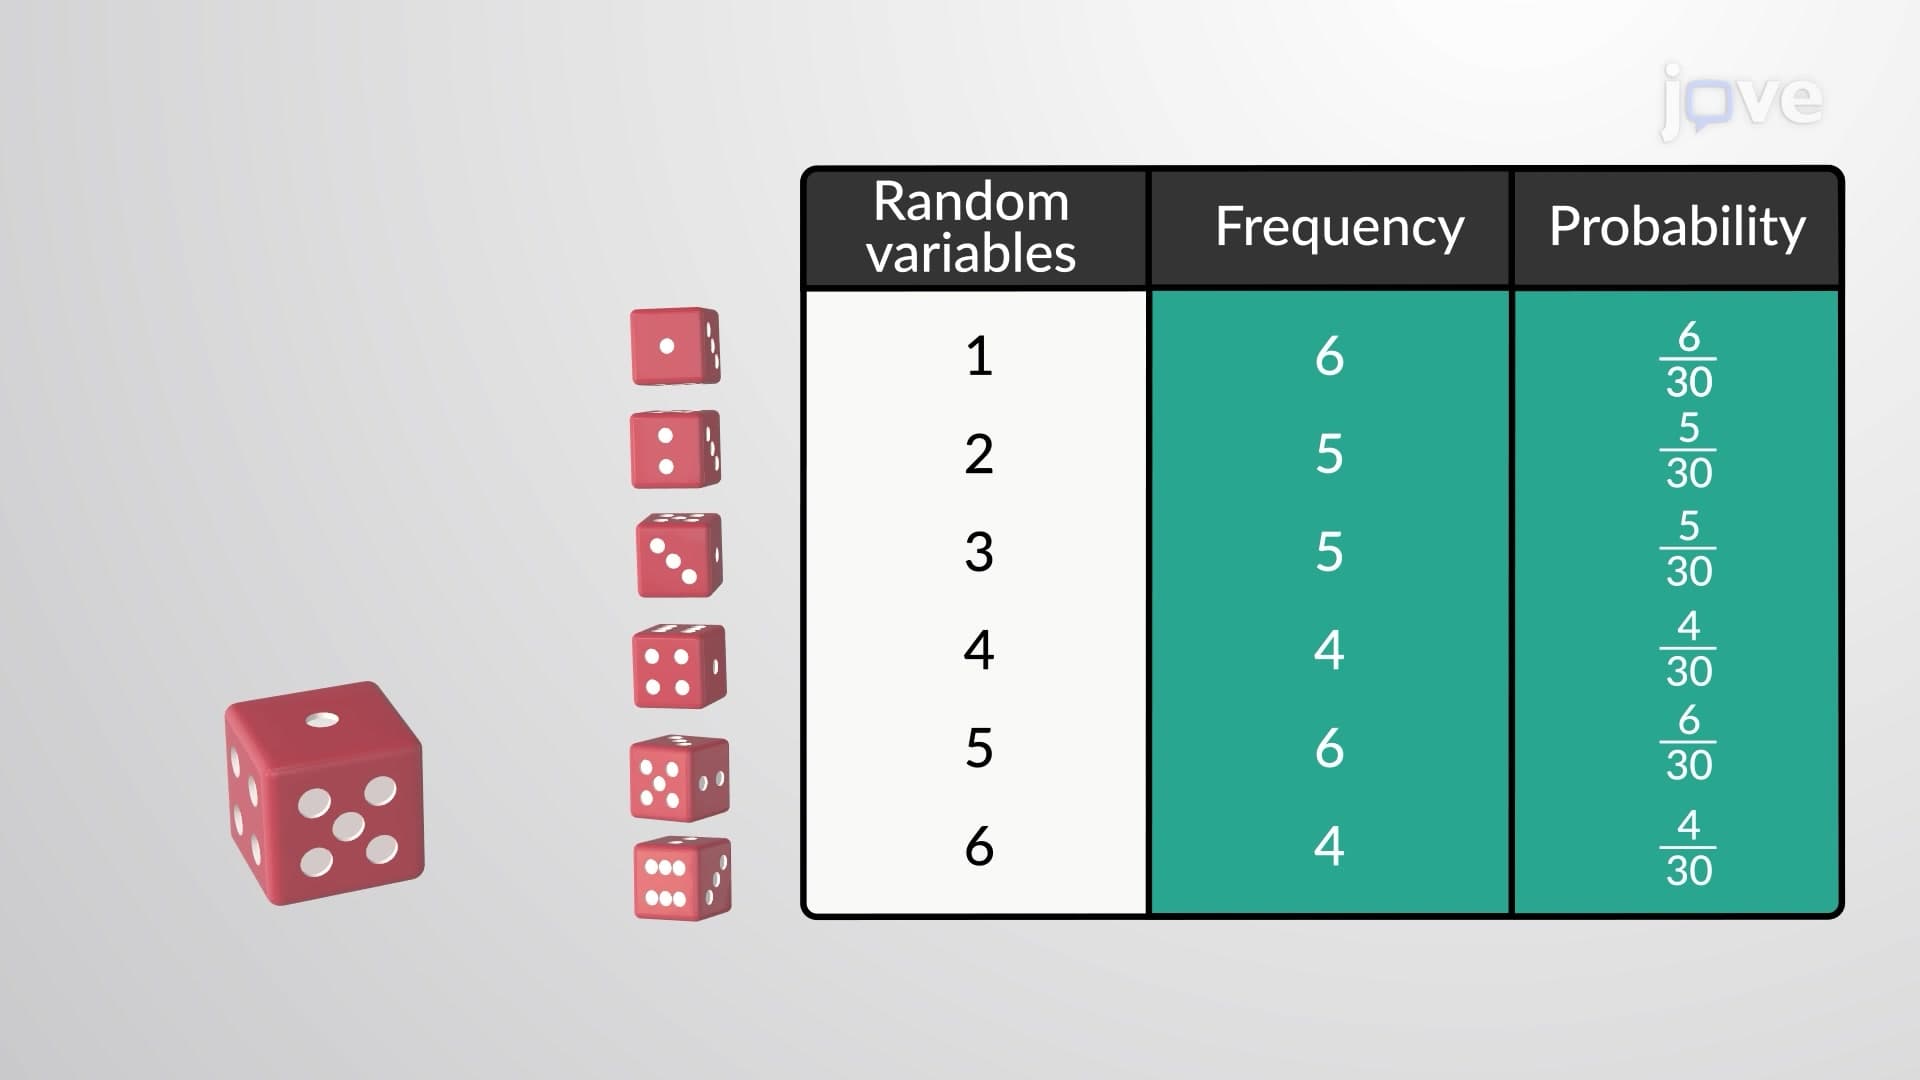
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 00:59
Propagation of Uncertainty from Random Error
 01:04
Random Error
 01:10
Propagation of Uncertainty from Systematic Error
 01:52
Regression Toward the Mean