Related Experiment Video
Updated: Jun 27, 2025

A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
A joint penalized spline smoothing model for the number of positive and negative COVID-19 tests
Dries De Witte1, Ariel Alonso Abad1,2, Thomas Neyens1,2
1L-BioStat, KU Leuven, Leuven, Belgium.

Abstract:
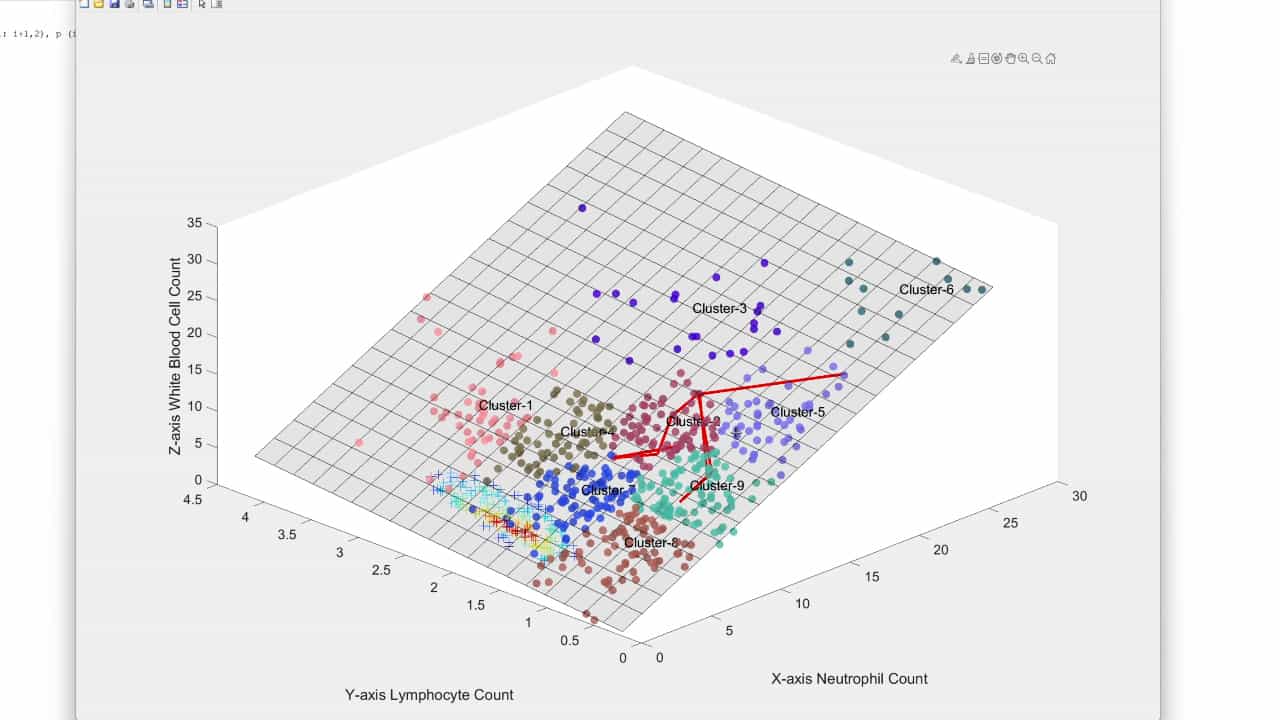
One of the key tools to understand and reduce the spread of the SARS-CoV-2 virus is testing. The total number of tests, the number of positive tests, the number of negative tests, and the positivity rate are interconnected indicators and vary with time. To better understand the relationship between these indicators, against the background of an evolving pandemic, the association between the number of positive tests and the number of negative tests is studied using a joint modeling approach. All countries in the European Union, Switzerland, the United Kingdom, and Norway are included in the analysis. We propose a joint penalized spline model in which the penalized spline is reparameterized as a linear mixed model. The model allows for flexible trajectories by smoothing the country-specific deviations from the overall penalized spline and accounts for heteroscedasticity by allowing the autocorrelation parameters and residual variances to vary among countries. The association between the number of positive tests and the number of negative tests is derived from the joint distribution for the random intercepts and slopes. The correlation between the random intercepts and the correlation between the random slopes were both positive. This suggests that, when countries increase their testing capacity, both the number of positive tests and negative tests will increase. A significant correlation was found between the random intercepts, but the correlation between the random slopes was not significant due to a wide credible interval.
Related Concept Videos
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:06
Skewness
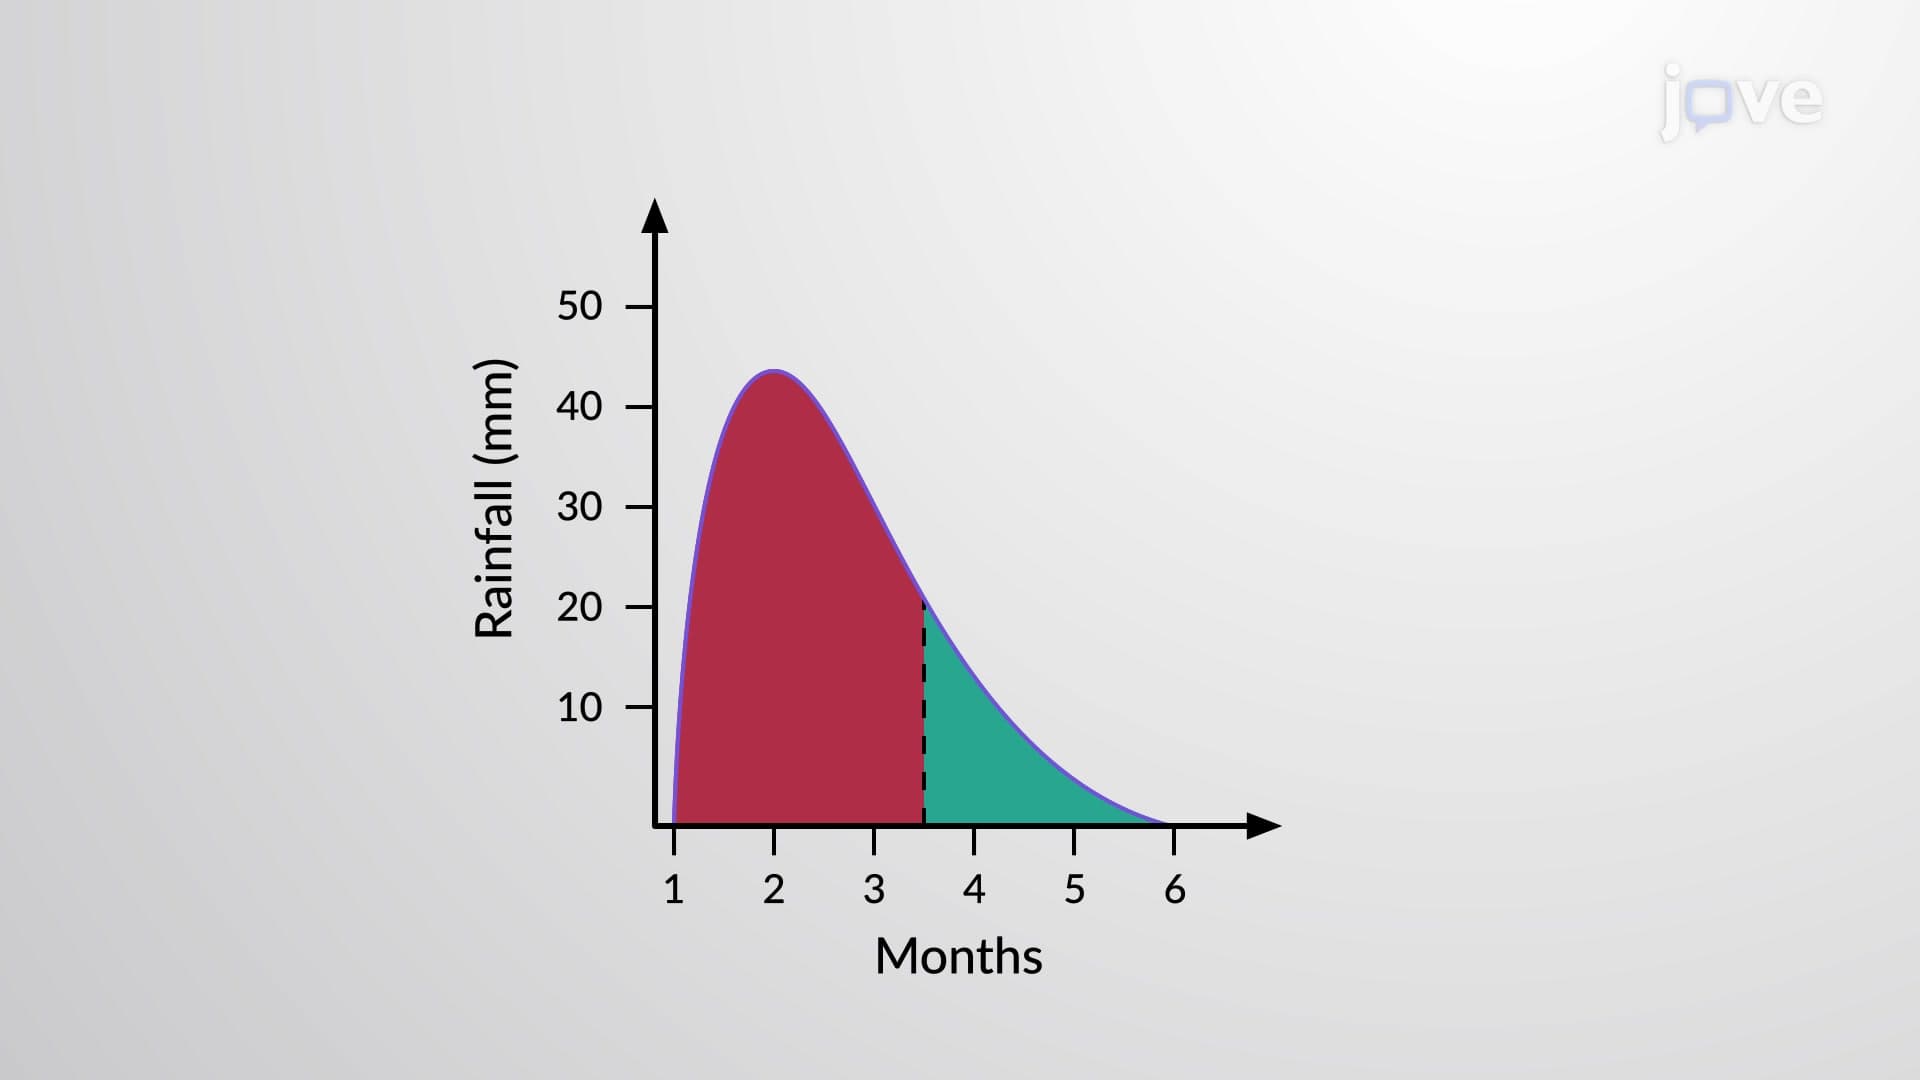
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:20
Sign Test for Median of Single Population
 01:52
Regression Toward the Mean