Related Experiment Video
Updated: Jun 26, 2025
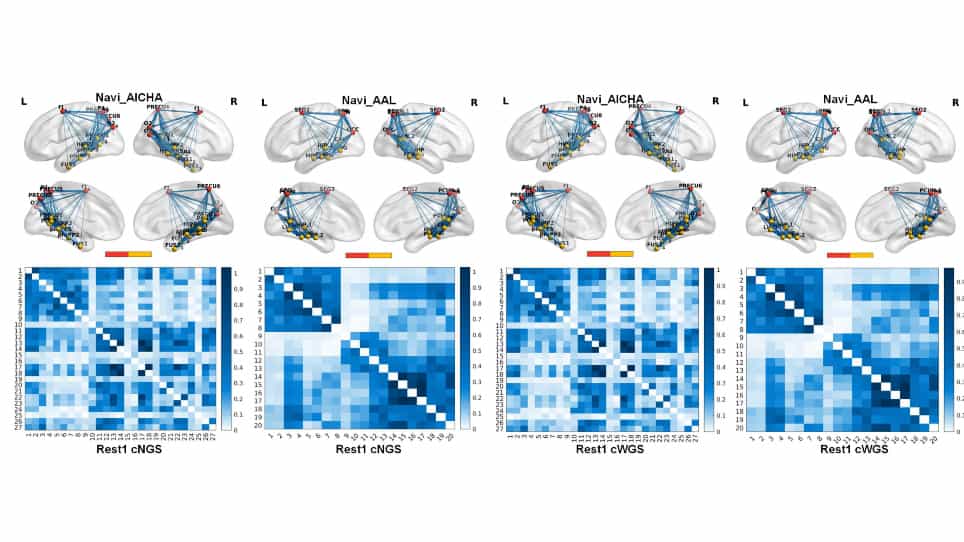

Modeling the Functional Network for Spatial Navigation in the Human Brain
Published on: October 13, 2023
Self-Supervised 3-D Semantic Representation Learning for Vision-and-Language Navigation

Abstract:
In vision-and-language navigation (VLN) tasks, most current methods primarily utilize RGB images, overlooking the rich 3-D semantic data inherent to environments. To rectify this, we introduce a novel VLN framework that integrates 3-D semantic information into the navigation process. Our approach features a self-supervised training scheme that incorporates voxel-level 3-D semantic reconstruction to create a detailed 3-D semantic representation. A key component of this framework is a pretext task focused on region queries, which determines the presence of objects in specific 3-D areas. Following this, we devise an long short-term memory (LSTM)-based navigation model that is trained using our 3-D semantic representations. To maximize the utility of these 3-D semantic representations, we implement a cross-modal distillation strategy. This strategy encourages the RGB model's outputs to emulate those from the 3-D semantic feature network, enabling the concurrent training of both branches to merge RGB and 3-D semantic data effectively. Comprehensive evaluations on both the R2R and R4R datasets reveal that our method significantly enhances performance in VLN tasks.
More Related Videos

Related Concept Videos
 01:15
Depth Perception and Spatial Vision
 01:24
Vision