The Comparison of ChatGPT 3.5, Microsoft Bing, and Google Gemini for Diagnosing Cases of Neuro-Ophthalmology
Related Experiment Video
Updated: Jun 19, 2026
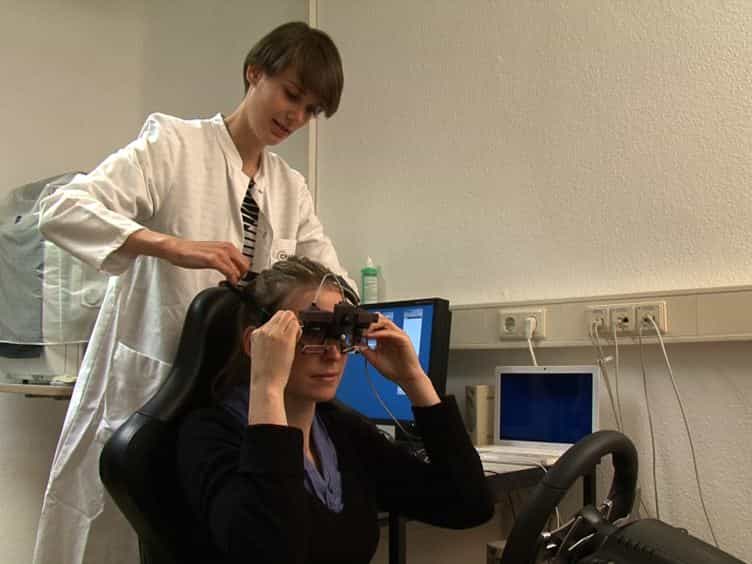
Driving Simulation in the Clinic: Testing Visual Exploratory Behavior in Daily Life Activities in Patients with Visual Field Defects
Published on: September 18, 2012
Ruchi Shukla1, Ashutosh K Mishra2, Nilakshi Banerjee1
1Department of Ophthalmology, All India Institute of Medical Sciences, Raebareli, Raebareli, IND.

Objective:
We aim to compare the capabilities of ChatGPT 3.5, Microsoft Bing, and Google Gemini in handling neuro-ophthalmological case scenarios.
Methods:
Ten randomly chosen neuro-ophthalmological cases from a publicly accessible database were used to test the accuracy and suitability of all three models, and the case details were followed by the following query: "What is the most probable diagnosis?"
Results:
On the basis of the accuracy of diagnosis, all three chat boxes (ChatGPT 3.5, Microsoft Bing, and Google Gemini) gave the correct diagnosis in four (40%) out of 10 cases, whereas in terms of suitability, ChatGPT 3.5, Microsoft Bing, and Google Gemini gave six (60%), five (50%), and five (50%) out of 10 case scenarios, respectively.
Conclusion:
ChatGPT 3.5 performs better than the other two when it comes to handling neuro-ophthalmological case difficulties. These results highlight the potential benefits of developing artificial intelligence (AI) models for improving medical education and ocular diagnostics.
More Related Videos
 07:26
Characterizing the Relationship Between Eye Movement Parameters and Cognitive Functions in Non-demented Parkinson's Disease Patients with Eye Tracking
Published on: September 26, 2019
 07:11
Assessing Early Stage Open-Angle Glaucoma in Patients by Isolated-Check Visual Evoked Potential
Published on: May 25, 2020
