Related Experiment Video
Updated: Jun 24, 2025


Author Spotlight: Investigating the Impact of Emotional Prosodies on Voice Recognition and Perception
Published on: August 9, 2024
Recurrence plot embeddings as short segment nonlinear features for multimodal speaker identification using air, bone
K Khadar Nawas1, A Shahina2, Keshav Balachandar2
1School of Computer Science and Engineering, Vellore Institute of Technology, Chennai, Tamilnadu, 600127, India.

Abstract:
Speech is produced by a nonlinear, dynamical Vocal Tract (VT) system, and is transmitted through multiple (air, bone and skin conduction) modes, as captured by the air, bone and throat microphones respectively. Speaker specific characteristics that capture this nonlinearity are rarely used as stand-alone features for speaker modeling, and at best have been used in tandem with well known linear spectral features to produce tangible results. This paper proposes Recurrent Plot (RP) embeddings as stand-alone, non-linear speaker-discriminating features. Two datasets, the continuous multimodal TIMIT speech corpus and the consonant-vowel unimodal syllable dataset, are used in this study for conducting closed-set speaker identification experiments. Experiments with unimodal speaker recognition systems show that RP embeddings capture the nonlinear dynamics of the VT system which are unique to every speaker, in all the modes of speech. The Air (A), Bone (B) and Throat (T) microphone systems, trained purely on RP embeddings perform with an accuracy of 95.81%, 98.18% and 99.74%, respectively. Experiments using the joint feature space of combined RP embeddings for bimodal (A-T, A-B, B-T) and trimodal (A-B-T) systems show that the best trimodal system (99.84% accuracy) performs on par with trimodal systems using spectrogram (99.45%) and MFCC (99.98%). The 98.84% performance of the B-T bimodal system shows the efficacy of a speaker recognition system based entirely on alternate (bone and throat) speech, in the absence of the standard (air) speech. The results underscore the significance of the RP embedding, as a nonlinear feature representation of the dynamical VT system that can act independently for speaker recognition. It is envisaged that speech recognition too will benefit from this nonlinear feature.
Related Concept Videos
 01:15
Receiver Operating Characteristic Plot
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by...
 01:07
Residual Plots
When the residual values are plotted against the variable x, it is called a residual...
 01:08
Determination of Expected Frequency
 01:14
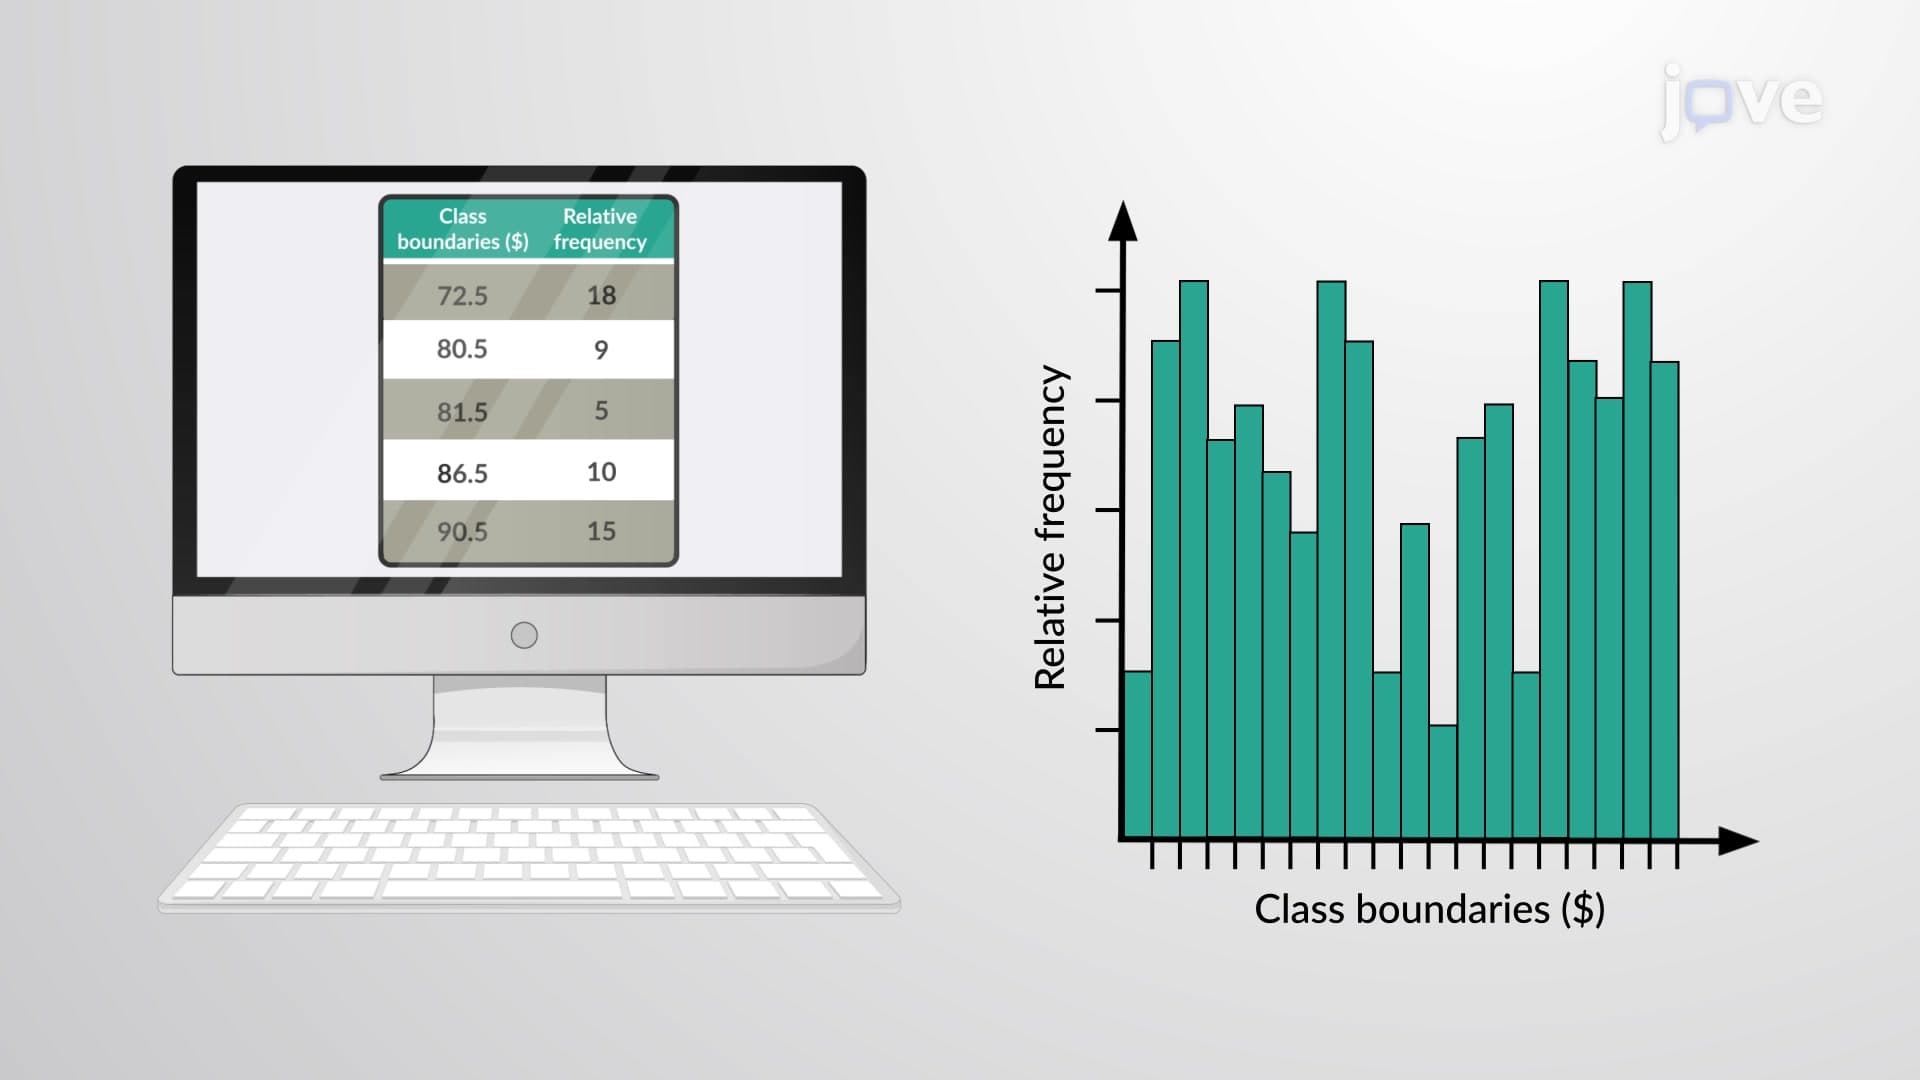
Relative Frequency Histogram