Related Experiment Video
Updated: Jul 1, 2026
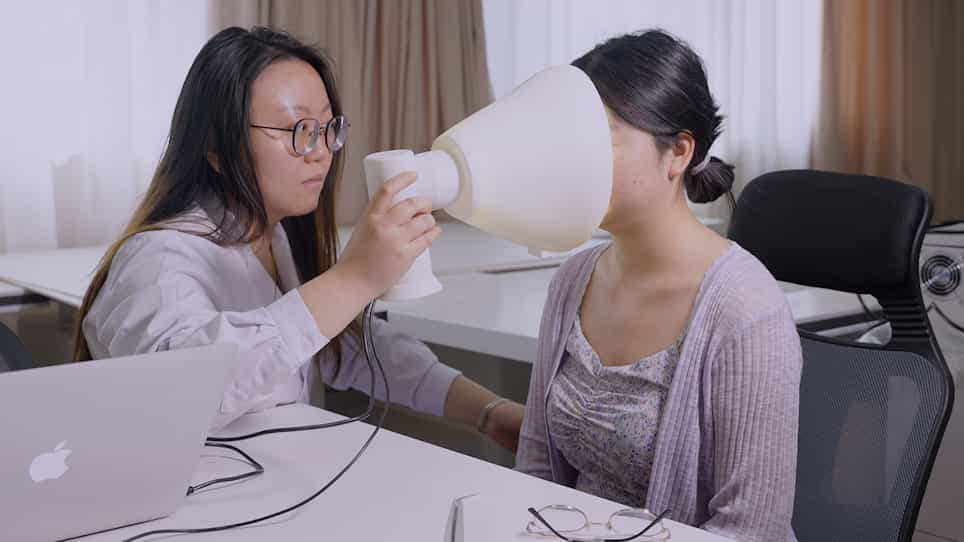

Objectification of Tongue Diagnosis in Traditional Medicine, Data Analysis, and Study Application
Published on: April 14, 2023
A survey on advancements in image-text multimodal models: From general techniques to biomedical implementations
Ruifeng Guo1, Jingxuan Wei1, Linzhuang Sun1
1Shenyang Institute of Computing Technology, Chinese Academy of Sciences, Shenyang, 110168, China; University of Chinese Academy of Sciences, Beijing, 100049, China.

Abstract:
With the significant advancements of Large Language Models (LLMs) in the field of Natural Language Processing (NLP), the development of image-text multimodal models has garnered widespread attention. Current surveys on image-text multimodal models mainly focus on representative models or application domains, but lack a review on how general technical models influence the development of domain-specific models, which is crucial for domain researchers. Based on this, this paper first reviews the technological evolution of image-text multimodal models, from early explorations of feature space to visual language encoding structures, and then to the latest large model architectures. Next, from the perspective of technological evolution, we explain how the development of general image-text multimodal technologies promotes the progress of multimodal technologies in the biomedical field, as well as the importance and complexity of specific datasets in the biomedical domain. Then, centered on the tasks of image-text multimodal models, we analyze their common components and challenges. After that, we summarize the architecture, components, and data of general image-text multimodal models, and introduce the applications and improvements of image-text multimodal models in the biomedical field. Finally, we categorize the challenges faced in the development and application of general models into external factors and intrinsic factors, further refining them into 2 external factors and 5 intrinsic factors, and propose targeted solutions, providing guidance for future research directions. For more details and data, please visit our GitHub page: https://github.com/i2vec/A-survey-on-image-text-multimodal-models.