Related Experiment Video
Updated: Jun 23, 2025
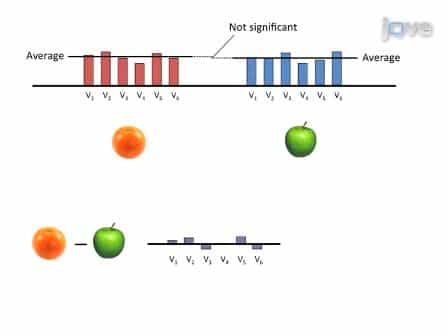

Cross-Modal Multivariate Pattern Analysis
Published on: November 9, 2011
View-Driven Multi-View Clustering via Contrastive Double-Learning
Shengcheng Liu1, Changming Zhu1, Zishi Li1
1Information Engineering College, Shanghai Maritime University, Shanghai 201306, China.

Abstract:
Multi-view clustering requires simultaneous attention to both consistency and the diversity of information between views. Deep learning techniques have shown impressive abilities to learn complex features when working with extensive datasets; however, existing deep multi-view clustering methods often focus only on either consistency information or diversity information, making it difficult to balance both aspects. Therefore, this paper proposes a view-driven multi-view clustering using the contrastive double-learning method (VMC-CD), aiming to generate better clustering results. This method first adopts a view-driven approach to consider information from other views to encourage diversity, thus guiding feature learning. Additionally, it presents the idea of dual contrastive learning to enhance the alignment of views at both the clustering and feature levels. The VMC-CD method's superiority over various cutting-edge methods is substantiated by experimental findings across three datasets, affirming its effectiveness.
Related Concept Videos
 01:12
Observational Learning
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 01:05
Collisions in Multiple Dimensions: Introduction
 01:13
Multiple Comparison Tests
It would be easy to compare two samples using a significance alpha level of 0.05. In other words, there is only one sample pair to be compared. However, it would be difficult to identify a significantly different sample if the number...
 01:27
Associative Learning
Classical conditioning, also known...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...