Related Experiment Video
Updated: Jun 16, 2025

Using the FishSim Animation Toolchain to Investigate Fish Behavior: A Case Study on Mate-Choice Copying In Sailfin Mollies
Published on: November 8, 2018
Disentangling Selection Into Mode From Mode Effects
Colm O'Muircheartaigh1, L Philip Schumm2, Ned English3
1Harris School of Public Policy, University of Chicago, Chicago, Illinois, USA.

Objectives:
We investigate the impact of data collection mode on responses to variables in the National Social Life, Health, and Aging Project (NSHAP) Round 4 and discuss how potential mode differences should (and should not) be addressed in substantive analyses.
Methods:
Among the set of respondents who were eligible to be contacted remotely in Round 4, we randomly selected 398 to be contacted instead for an in-person interview. We compare response rates and the distributions of selected key outcomes among those 398 respondents to those among the control group who were initially approached remotely. In contrast, we compared all R4 respondents according to the mode in which they completed the interview, including those not part of the randomized experiment.
Results:
Among those included in the experiment, there was no evidence of systematic differences in responses to physical and mental health questions between remote and in-person modes, nor in responses to number recall measures. In-person respondents scored moderately lower on cognitive function measures requiring careful attention to a figure and/or task, though this difference became less with each similar item. Remote respondents named fewer social network members. Comparing all respondents according to their final mode yielded substantially different results in all cases.
Discussion:
Mode did not appear to affect reports of physical and mental health based on a randomized comparison, though it did moderately affect other items in predictable ways. Naïve estimates of mode effects based on comparing all respondents according to mode yielded misleading results, and should not be used to adjust for mode differences in analyses.
More Related Videos
 06:33
Decomposing the Variance in Reading Comprehension to Reveal the Unique and Common Effects of Language and Decoding
Published on: October 11, 2018
 06:52
Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
Related Concept Videos
 01:46
Types of Selection
 01:07
What is a Mode?
There can be more than one mode in a data set if multiple values have the same highest frequency. For instance, suppose that the Statistics exam scores of 20 students are: 50; 53; 59; 59; 63; 63; 72; 72; 72; 72; 72; 76; 78; 81; 83; 84; 84; 84; 90; 93. Here, the mode is 72, as it occurs most frequently, five times.
A data set with two modes is called bimodal. For example,...
 01:21
Frequency-dependent Selection
 01:06
Skewness
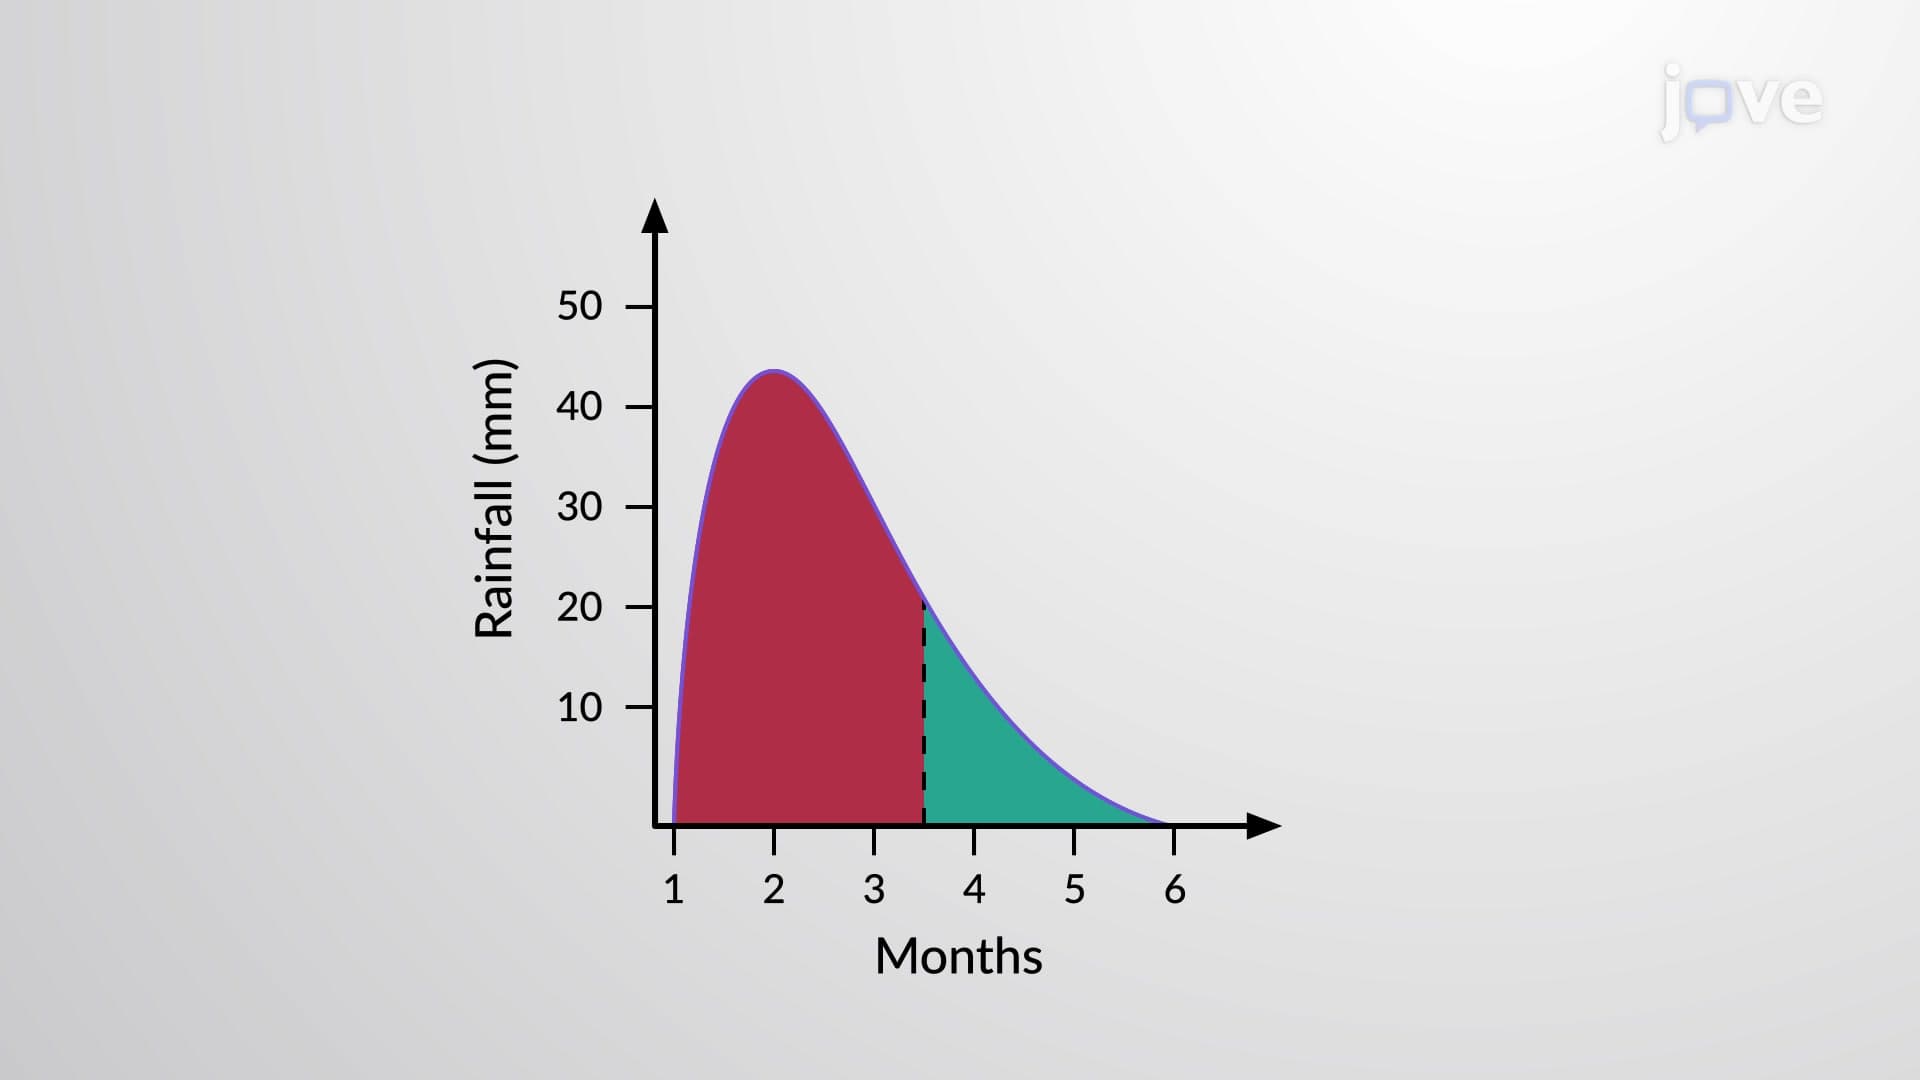
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:20
Mate Choice
 01:09
Epistasis Analysis