Related Experiment Video
Updated: Jun 14, 2025

The Use of Reverse Phase Protein Arrays RPPA to Explore Protein Expression Variation within Individual Renal Cell Cancers
Published on: January 22, 2013
Accumulating evidence across studies: Consistent methods protect against false findings produced by p-hacking
Duane T Wegener1, Jolynn Pek1, Leandre R Fabrigar2
1Department of Psychology, Ohio State University, Columbus, Ohio, United States of America.

Abstract:
Much empirical science involves evaluating alternative explanations for the obtained data. For example, given certain assumptions underlying a statistical test, a "significant" result generally refers to implausibility of a null (zero) effect in the population producing the obtained study data. However, methodological work on various versions of p-hacking (i.e., using different analysis strategies until a "significant" result is produced) questions whether significant p-values might often reflect false findings. Indeed, initial simulations of single studies showed that the potential for finding "significant" but false findings might be much higher than the nominal .05 value when various analysis flexibilities are undertaken. In many settings, however, research articles report multiple studies using consistent methods across the studies, where those consistent methods would constrain the flexibilities used to produce high false-finding rates for simulations of single studies. Thus, we conducted simulations of study sets. These simulations show that consistent methods across studies (i.e., consistent in terms of which measures are analyzed, which conditions are included, and whether and how covariates are included) dramatically reduce the potential for flexible research practices (p-hacking) to produce consistent sets of significant results across studies. For p-hacking to produce even modest probabilities of a consistent set of studies would require (a) a large amount of selectivity in study reporting and (b) severe (and quite intentional) versions of p-hacking. With no more than modest selective reporting and with consistent methods across studies, p-hacking does not provide a plausible explanation for consistent empirical results across studies, especially as the size of the reported study set increases. In addition, the simulations show that p-hacking can produce high rates of false findings for single studies with very large samples. In contrast, a series of methodologically-consistent studies (even with much smaller samples) is much less vulnerable to the forms of p-hacking examined in the simulations.
Related Concept Videos
 01:09
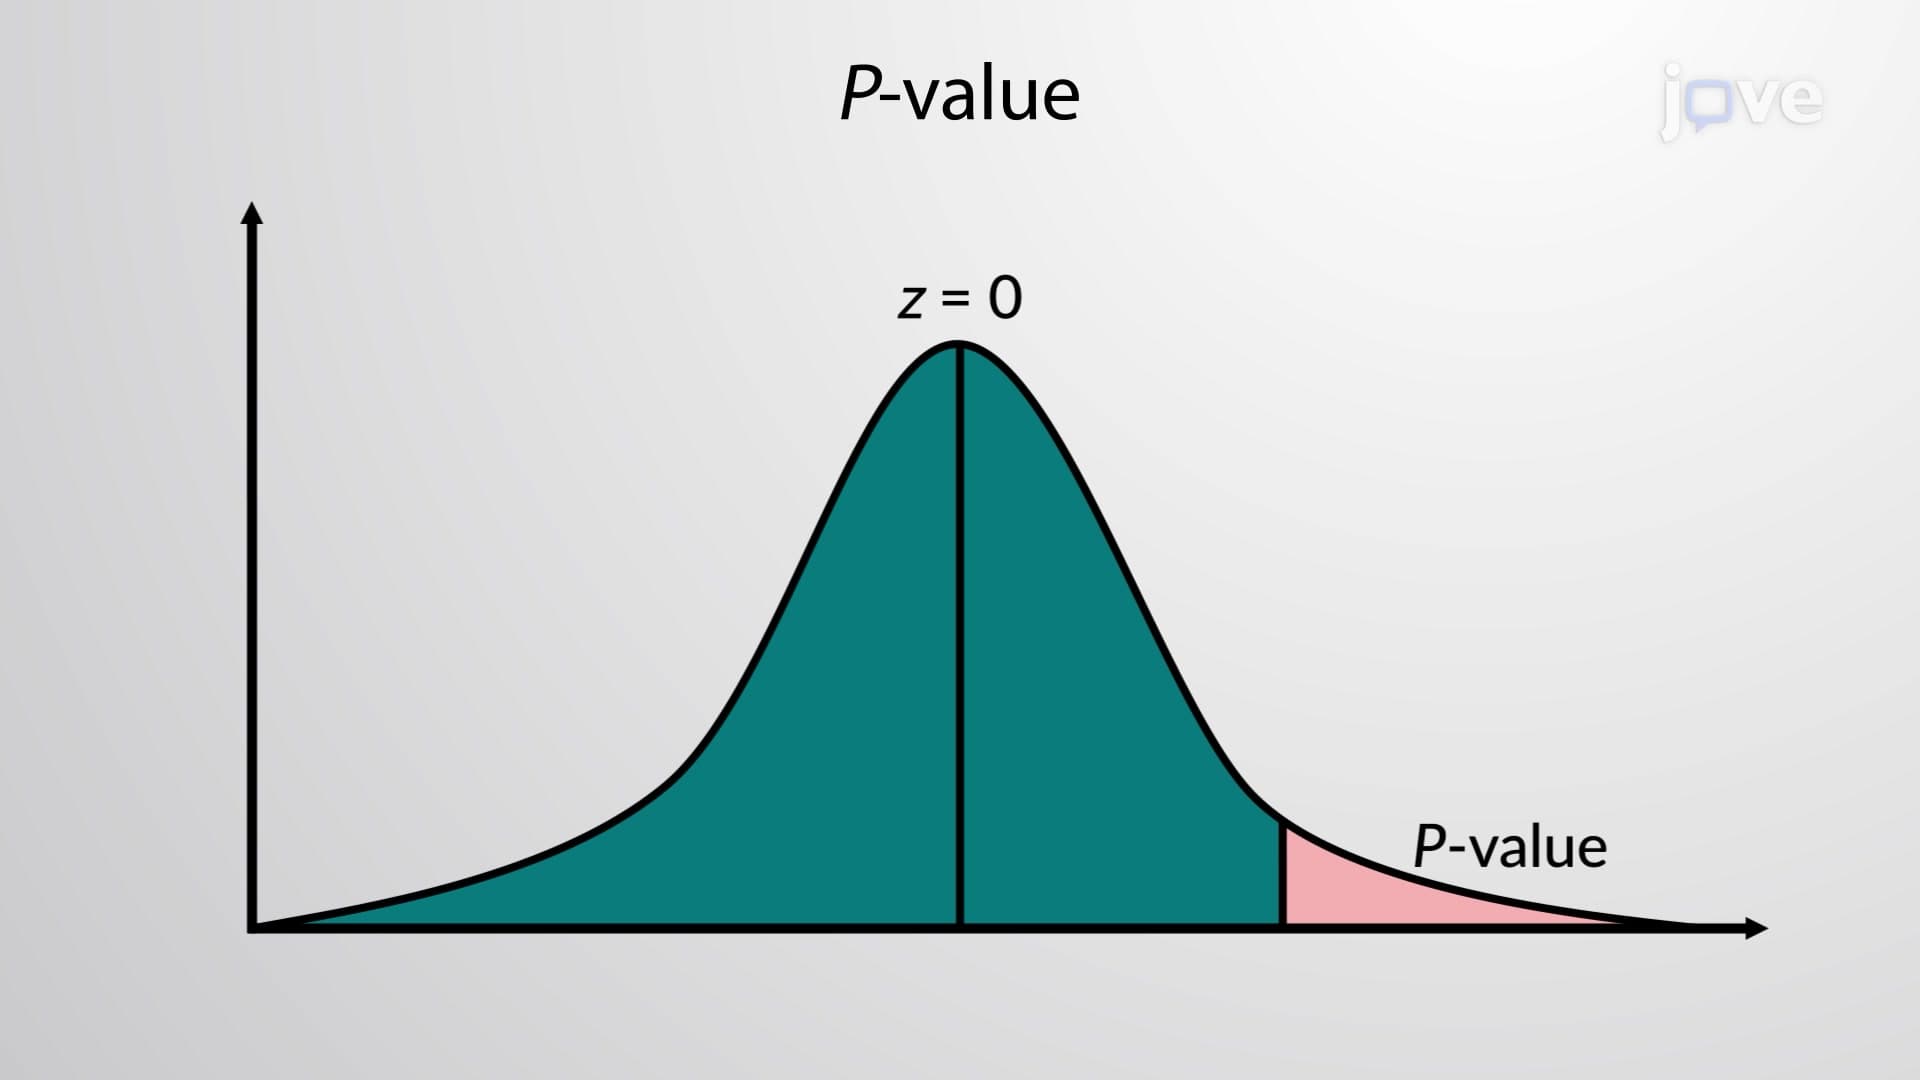
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
 01:50
Statistical Significance
 01:10
Bonferroni Test
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
 01:22
Bias
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...