
Automated Measurement of Speech Recognition, Reaction Time, and Speech Rate and Their Relation to Self-Reported
Inga Holube1,2, Stefan Taesler1, Saskia Ibelings1,2
1Institute of Hearing Technology and Audiology, Jade University of Applied Sciences, Oldenburg, Germany.

Abstract:
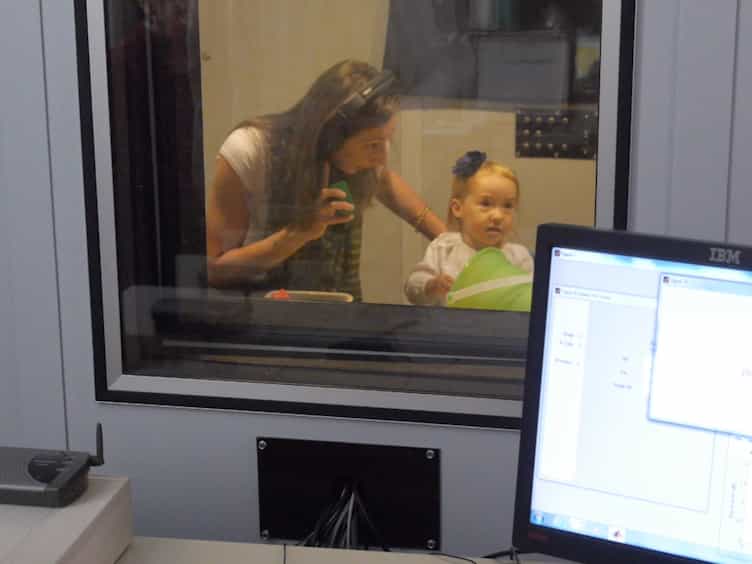
In speech audiometry, the speech-recognition threshold (SRT) is usually established by adjusting the signal-to-noise ratio (SNR) until 50% of the words or sentences are repeated correctly. However, these conditions are rarely encountered in everyday situations. Therefore, for a group of 15 young participants with normal hearing and a group of 12 older participants with hearing impairment, speech-recognition scores were determined at SRT and at four higher SNRs using several stationary and fluctuating maskers. Participants' verbal responses were recorded, and participants were asked to self-report their listening effort on a categorical scale (self-reported listening effort, SR-LE). The responses were analyzed using an Automatic Speech Recognizer (ASR) and compared to the results of a human examiner. An intraclass correlation coefficient of r = .993 for the agreement between their corresponding speech-recognition scores was observed. As expected, speech-recognition scores increased with increasing SNR and decreased with increasing SR-LE. However, differences between speech-recognition scores for fluctuating and stationary maskers were observed as a function of SNR, but not as a function of SR-LE. The verbal response time (VRT) and the response speech rate (RSR) of the listeners' responses were measured using an ASR. The participants with hearing impairment showed significantly lower RSRs and higher VRTs compared to the participants with normal hearing. These differences may be attributed to differences in age, hearing, or both. With increasing SR-LE, VRT increased and RSR decreased. The results show the possibility of deriving a behavioral measure, VRT, measured directly from participants' verbal responses during speech audiometry, as a proxy for SR-LE.

Related Concept Videos
 01:06
Echo
Imagine the sound is reflected back to the ears. Assuming that the source is very close to the human, the difference between hearing the two sounds—the emitted sound and the reflected sound—may be more than the minimum time for perceiving distinct sounds. If this is the case, then the...
 01:29
Non-Verbal Cues