Related Experiment Video
Updated: Jul 24, 2026

Three Different Protocols of Corneal Collagen Crosslinking in Keratoconus: Conventional, Accelerated and Iontophoresis
Published on: November 12, 2015
Evaluating the reliability of the responses of large language models to keratoconus-related questions
Mustafa Kayabaşı1, Seher Köksaldı1, Ceren Durmaz Engin2
1Department of Ophthalmology, Mus State Hospital, Mus, Turkey.

Clinical Relevance:
Artificial intelligence has undergone a rapid evolution and large language models (LLMs) have become promising tools for healthcare, with the ability of providing human-like responses to questions. The capabilities of these tools in addressing questions related to keratoconus (KCN) have not been previously explored.
Background:
In this study, the responses were evaluated from three LLMs - ChatGPT-4, Copilot, and Gemini - to common patient questions regarding KCN.
Methods:
Fifty real-life patient inquiries regarding general information, aetiology, symptoms and diagnosis, progression, and treatment of KCN were presented to the LLMs. Evaluations of the answers were conducted by three ophthalmologists with a 5-point Likert scale ranging from 'strongly disagreed' to 'strongly agreed'. The reliability of the responses provided by LLMs was evaluated using the DISCERN and the Ensuring Quality Information for Patients (EQIP) scales. Readability metrics (Flesch Reading Ease Score, Flesch-Kincaid Grade Level, and Coleman-Liau Index) were calculated to evaluate the complexity of responses.
Results:
ChatGPT-4 consistently scored 3 points or higher for all (100%) its responses, while Copilot had five (10%) and Gemini had two (4%) responses scoring 2 points or below. ChatGPT-4 achieved a 'strongly agree' rate of 74% across all questions, markedly superior to Copilot at 34% and Gemini at 42% (p < 0.001); and recorded the highest 'strongly agree' rates in general information and symptoms & diagnosis categories (90% for both). The median Likert scores differed among LLMs (p < 0.001), with ChatGPT-4 scoring highest and Copilot scoring lowest. Although ChatGPT-4 exhibited more reliability based on the DISCERN scale, it was characterised by lower readability and higher complexity. While all LLMs provided responses categorised as 'extremely difficult to read', the responses provided by Copilot showed higher readability.
Conclusions:
Despite the responses provided by ChatGPT-4 exhibiting lower readability and greater complexity, it emerged as the most proficient in answering KCN-related questions.

Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:28
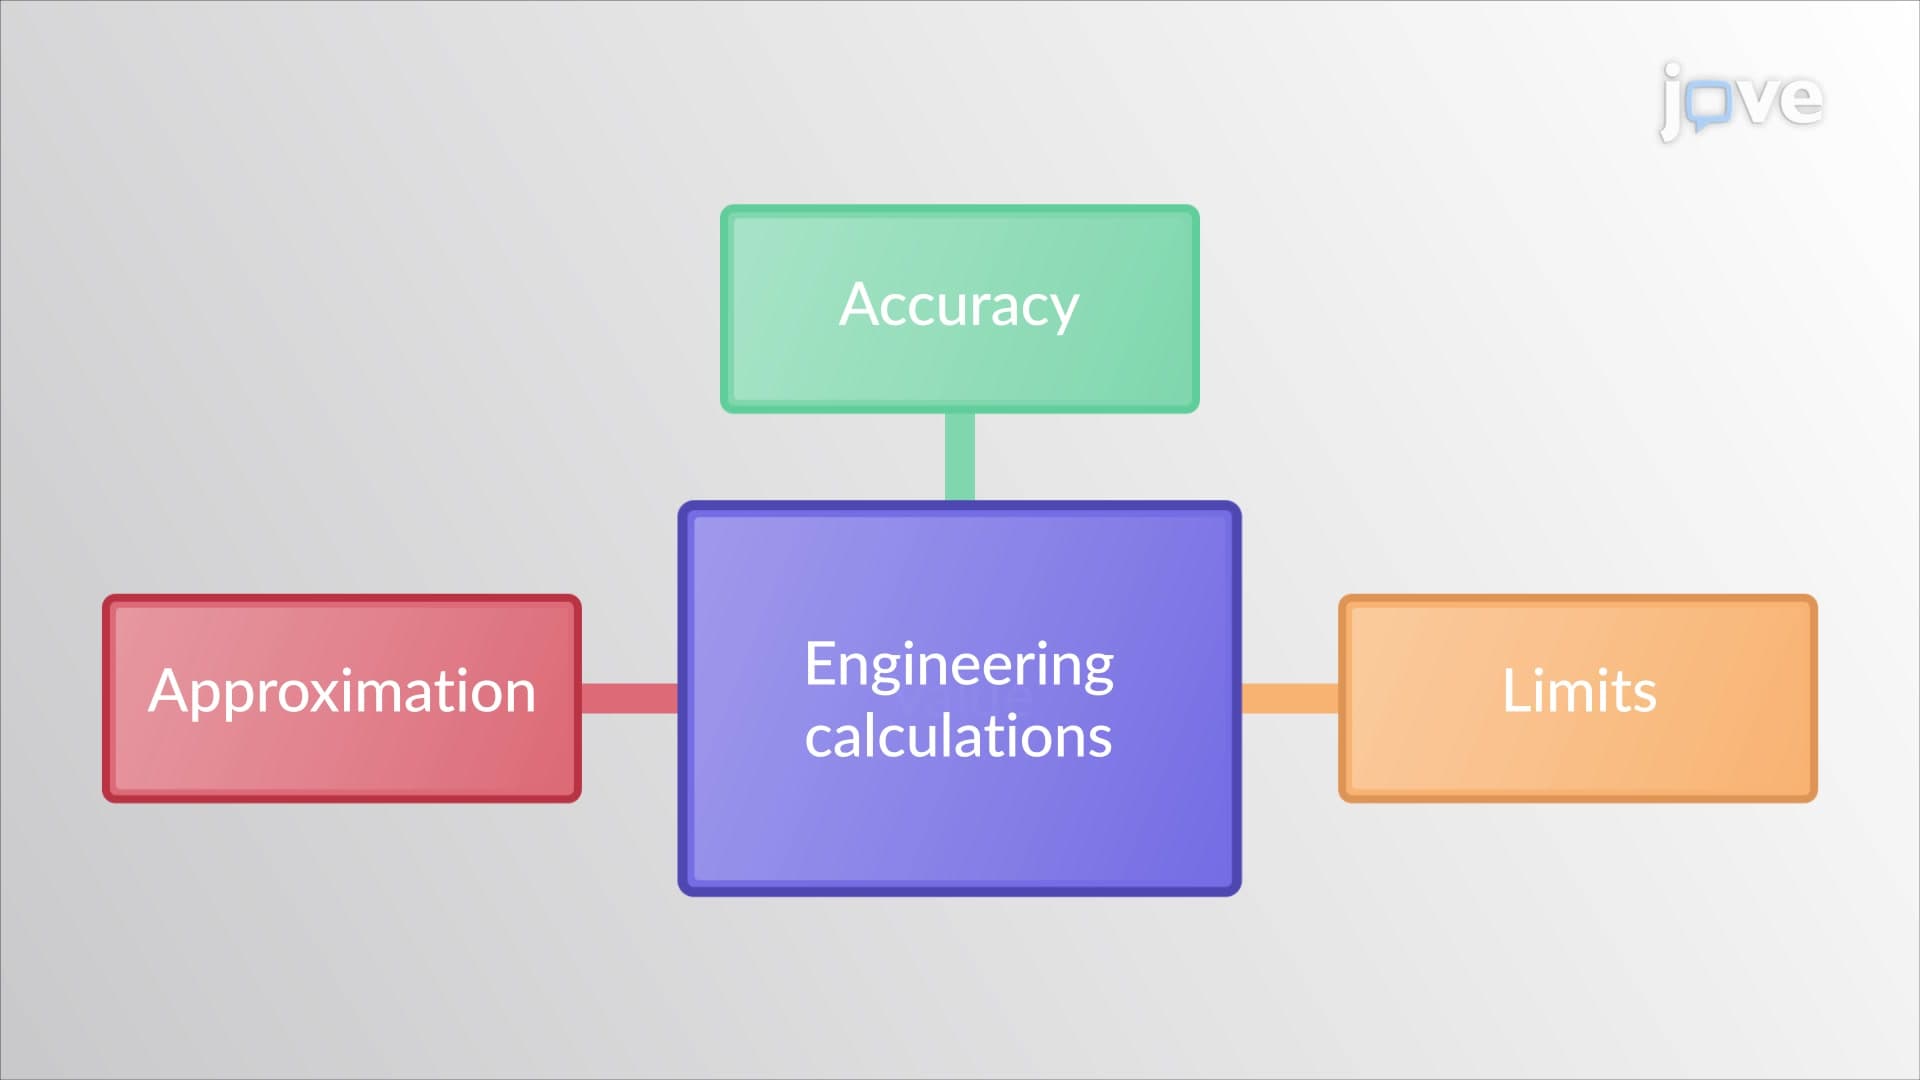
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.
 01:23
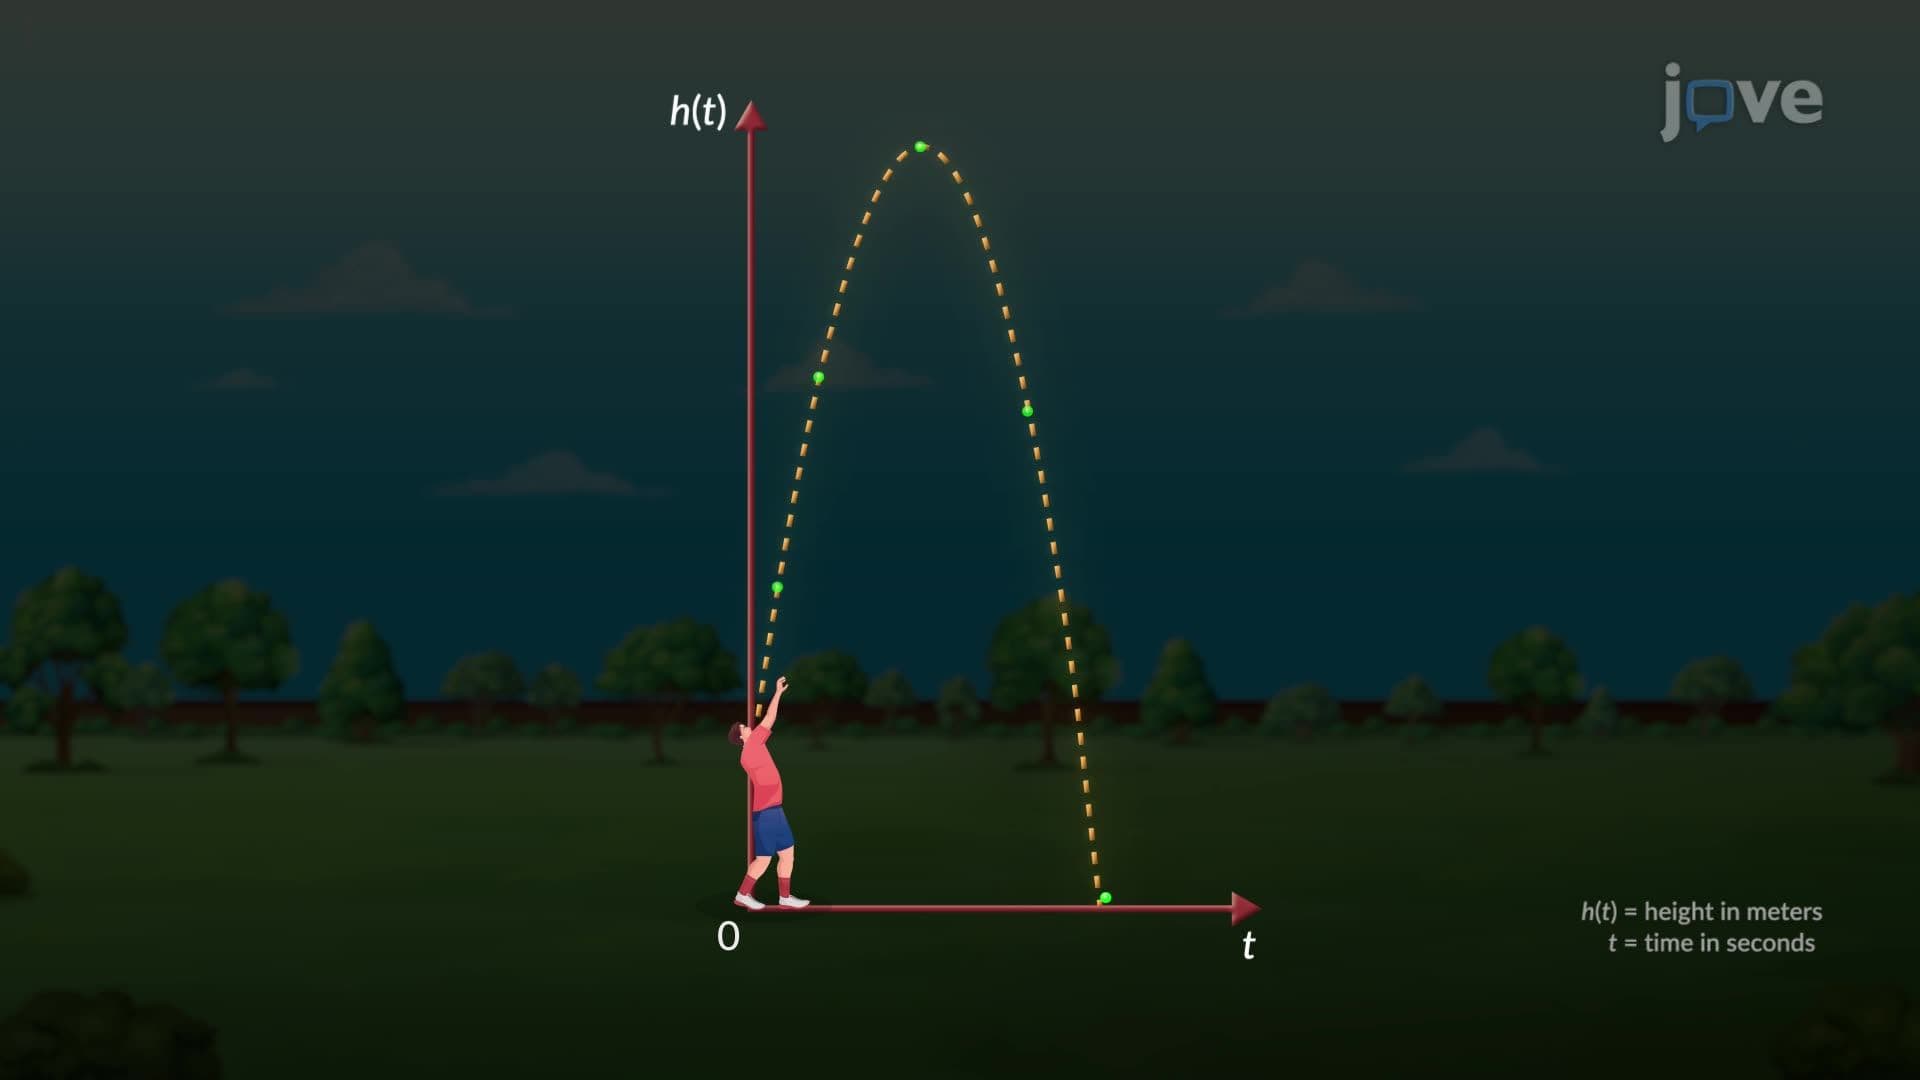
Quadratic Models