
Identifying Key Nodes for the Influence Spread Using a Machine Learning Approach
Mateusz Stolarski1, Adam Piróg2, Piotr Bródka1
1Department of Artificial Intelligence, Wrocław University of Science and Technology, 50-370 Wrocław, Poland.

Abstract:
The identification of key nodes in complex networks is an important topic in many network science areas. It is vital to a variety of real-world applications, including viral marketing, epidemic spreading and influence maximization. In recent years, machine learning algorithms have proven to outperform the conventional, centrality-based methods in accuracy and consistency, but this approach still requires further refinement. What information about the influencers can be extracted from the network? How can we precisely obtain the labels required for training? Can these models generalize well? In this paper, we answer these questions by presenting an enhanced machine learning-based framework for the influence spread problem. We focus on identifying key nodes for the Independent Cascade model, which is a popular reference method. Our main contribution is an improved process of obtaining the labels required for training by introducing "Smart Bins" and proving their advantage over known methods. Next, we show that our methodology allows ML models to not only predict the influence of a given node, but to also determine other characteristics of the spreading process-which is another novelty to the relevant literature. Finally, we extensively test our framework and its ability to generalize beyond complex networks of different types and sizes, gaining important insight into the properties of these methods.
Related Concept Videos
 01:08
Outliers and Influential Points
 01:07
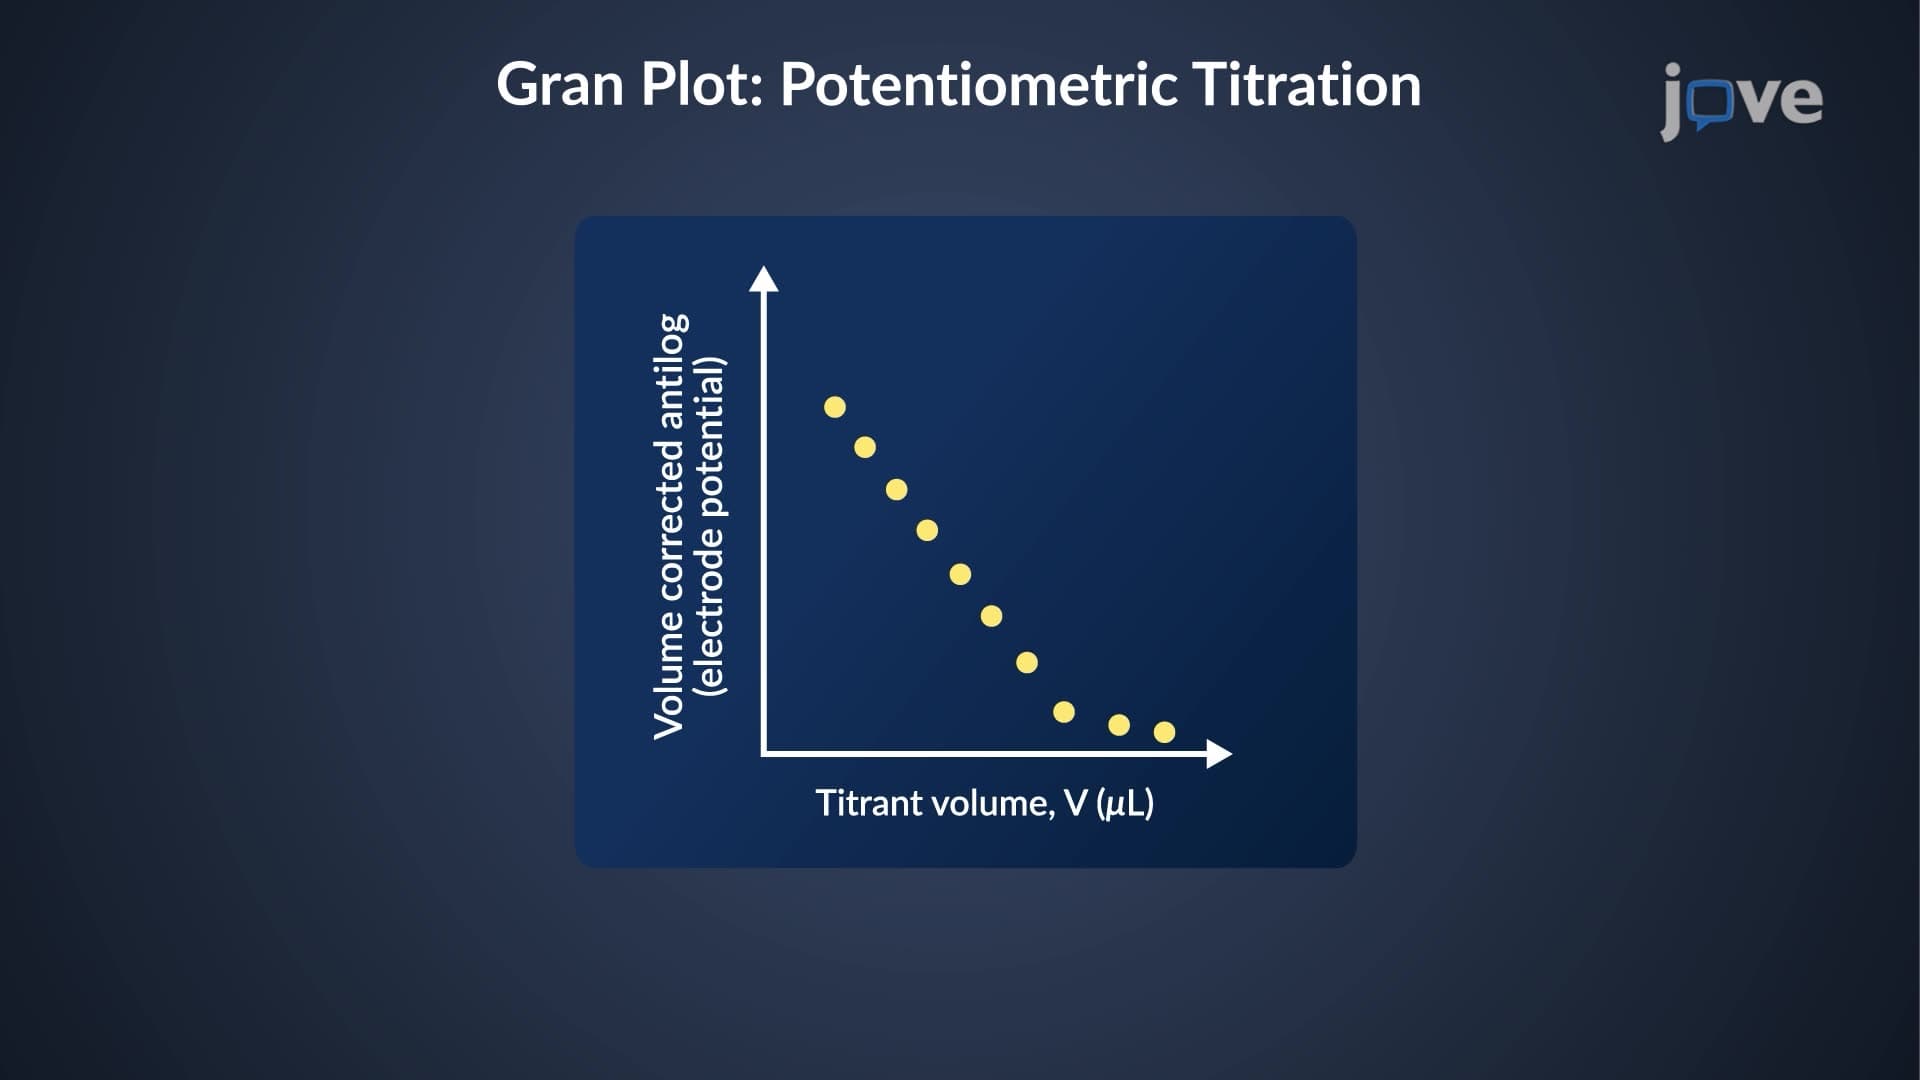
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:24
Confidence Coefficient
 01:19
Survival Tree
Building a Survival Tree
Constructing a...
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...