Related Experiment Video
Updated: Jun 6, 2025
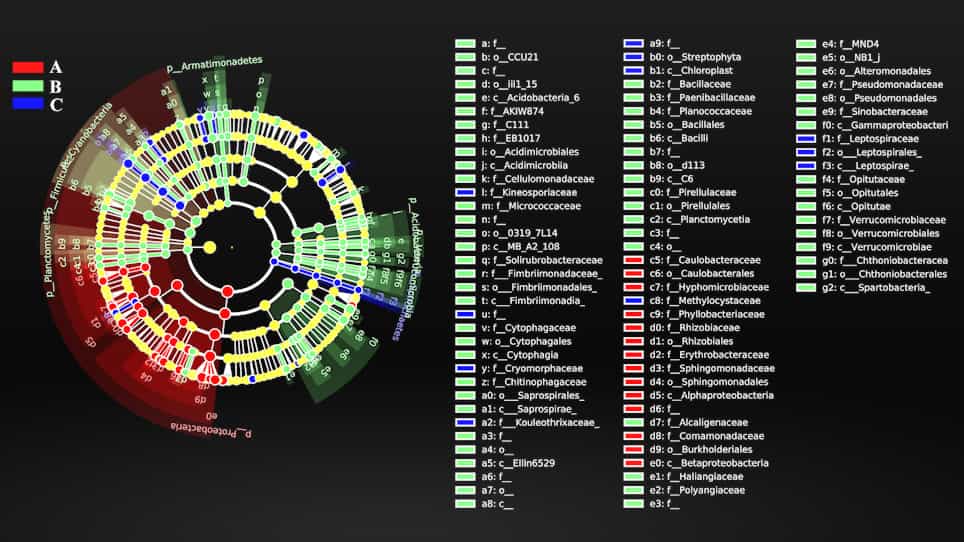

Assisted Selection of Biomarkers by Linear Discriminant Analysis Effect Size LEfSe in Microbiome Data
Published on: May 16, 2022
Detecting Interactions in High-Dimensional Data Using Cross Leverage Scores
Sven Teschke1, Katja Ickstadt1,2, Alexander Munteanu1
1Faculty of Statistics, TU Dortmund University, Dortmund, Germany.

Abstract:
We develop a variable selection method for interactions in regression models on large data in the context of genetics. The method is intended for investigating the influence of single-nucleotide polymorphisms (SNPs) and their interactions on health outcomes, which is a problem. We introduce cross leverage scores (CLSs) to detect interactions of variables while maintaining interpretability. Using this method, it is not necessary to consider every possible interaction between variables individually, which would be very time-consuming even for moderate amounts of variables. Instead, we calculate the CLS for each variable and obtain a measure of importance for this variable. Calculating the scores remains time-consuming for large data sets. The key idea for scaling to large data is to divide the data into smaller random batches or consecutive windows of variables. This avoids complex and time-consuming computations on high-dimensional matrices by performing the computations only for small subsets of the data, which is less costly. We compare these methods to provable approximations of CLS based on sketching, which aims at summarizing data succinctly. In a simulation study, we show that the CLSs are directly linked to the importance of a variable in the sense of an interaction effect. We further show that the approximation approaches are appropriate for performing the calculations efficiently on arbitrarily large data while preserving the interaction detection effect of the CLS. This underlines their scalability to genome wide data. In addition, we evaluate the methods on real data from the HapMap project.
Related Concept Videos
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
 01:09
Wilcoxon Signed-Ranks Test for Matched Pairs
 01:08
Outliers and Influential Points
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:25
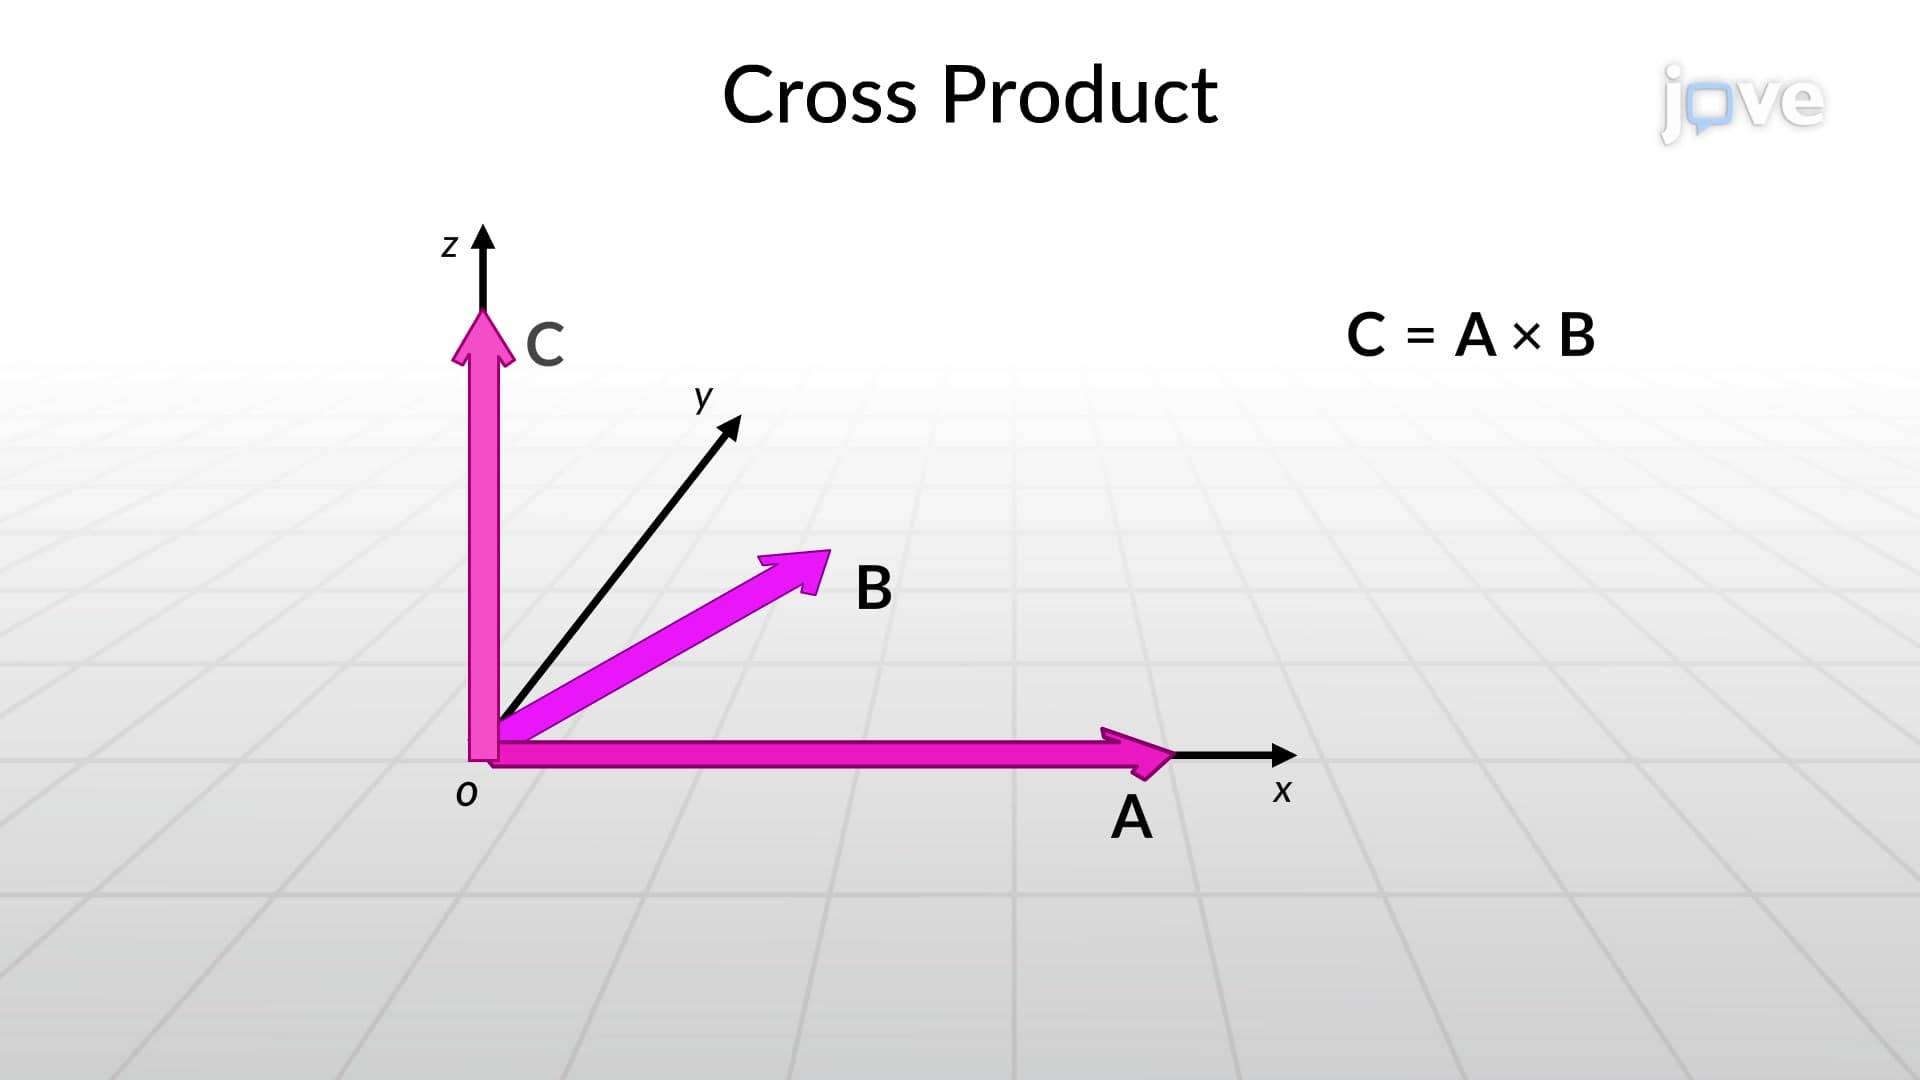
Cross Product
The magnitude of the cross product is obtained by multiplying the magnitude of both the vectors and the sine of the angle between them. This means that a larger angle between the vectors will lead to a greater magnitude of the cross product.
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...