Related Experiment Video
Updated: Jun 6, 2025
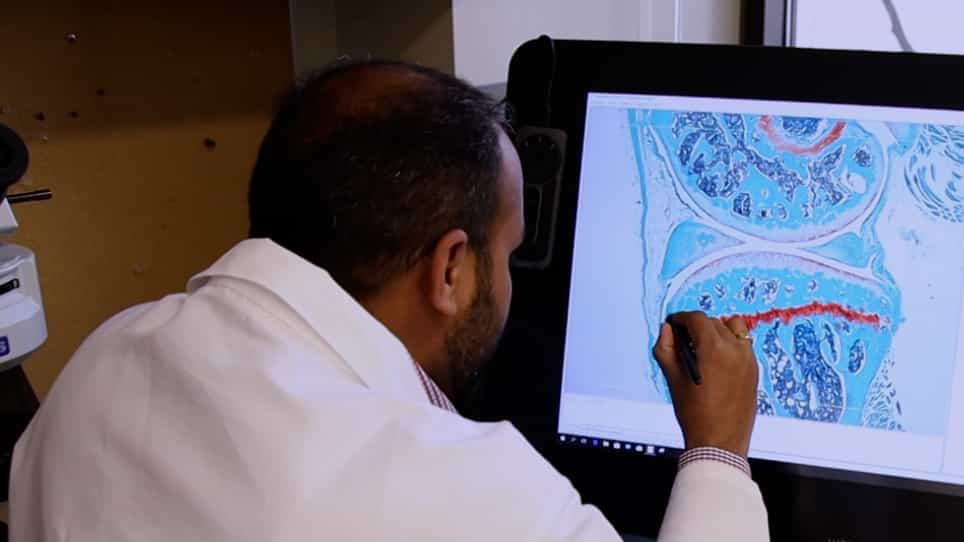

Standardized Histomorphometric Evaluation of Osteoarthritis in a Surgical Mouse Model
Published on: May 6, 2020
Large language models' performances regarding common patient questions about osteoarthritis: A comparative analysis
Mingde Cao1, Qianwen Wang2, Xueyou Zhang2
1Department of Orthopaedics and Traumatology, Faculty of Medicine, The Chinese University of Hong Kong, Hong Kong 999077, China; Center for Neuromusculoskeletal Restorative Medicine (CNRM), The Chinese University of Hong Kong, Hong Kong 999077, China.

Background:
Large Language Models (LLMs) have gained much attention and, in part, have replaced common search engines as a popular channel for obtaining information due to their contextually relevant responses. Osteoarthritis (OA) is a common topic in skeletal muscle disorders, and patients often seek information about it online. Our study evaluated the ability of 3 LLMs (ChatGPT-3.5, ChatGPT-4.0, and Perplexity) to accurately answer common OA-related queries.
Methods:
We defined 6 themes (pathogenesis, risk factors, clinical presentation, diagnosis, treatment and prevention, and prognosis) based on a generalization of 25 frequently asked questions about OA. Three consultant-level orthopedic specialists independently rated the LLMs' replies on a 4-point accuracy scale. The final ratings for each response were determined using a majority consensus approach. Responses classified as "satisfactory" were evaluated for comprehensiveness on a 5-point scale.
Results:
ChatGPT-4.0 demonstrated superior accuracy, with 64% of responses rated as "excellent", compared to 40% for ChatGPT-3.5 and 28% for Perplexity (Pearson's χ2 test with Fisher's exact test, all p < 0.001). All 3 LLM-chatbots had high mean comprehensiveness ratings (Perplexity = 3.88; ChatGPT-4.0 = 4.56; ChatGPT-3.5 = 3.96, out of a maximum score of 5). The LLM-chatbots performed reliably across domains, except for "treatment and prevention" However, ChatGPT-4.0 still outperformed ChatGPT-3.5 and Perplexity, garnering 53.8% "excellent" ratings (Pearson's χ2 test with Fisher's exact test, all p < 0.001).
Conclusion:
Our findings underscore the potential of LLMs, specifically ChatGPT-4.0 and Perplexity, to deliver accurate and thorough responses to OA-related queries. Targeted correction of specific misconceptions to improve the accuracy of LLMs remains crucial.
Related Concept Videos
 01:16
Bones of the Lower Limb: Femur and Patella
 01:31
Osteoclasts in Bone Remodeling
 01:18
Classification of Bones
Long and Short Bones
The appendicular skeleton, particularly the upper and lower limbs, is primarily made of long and short bones. The...
 01:09
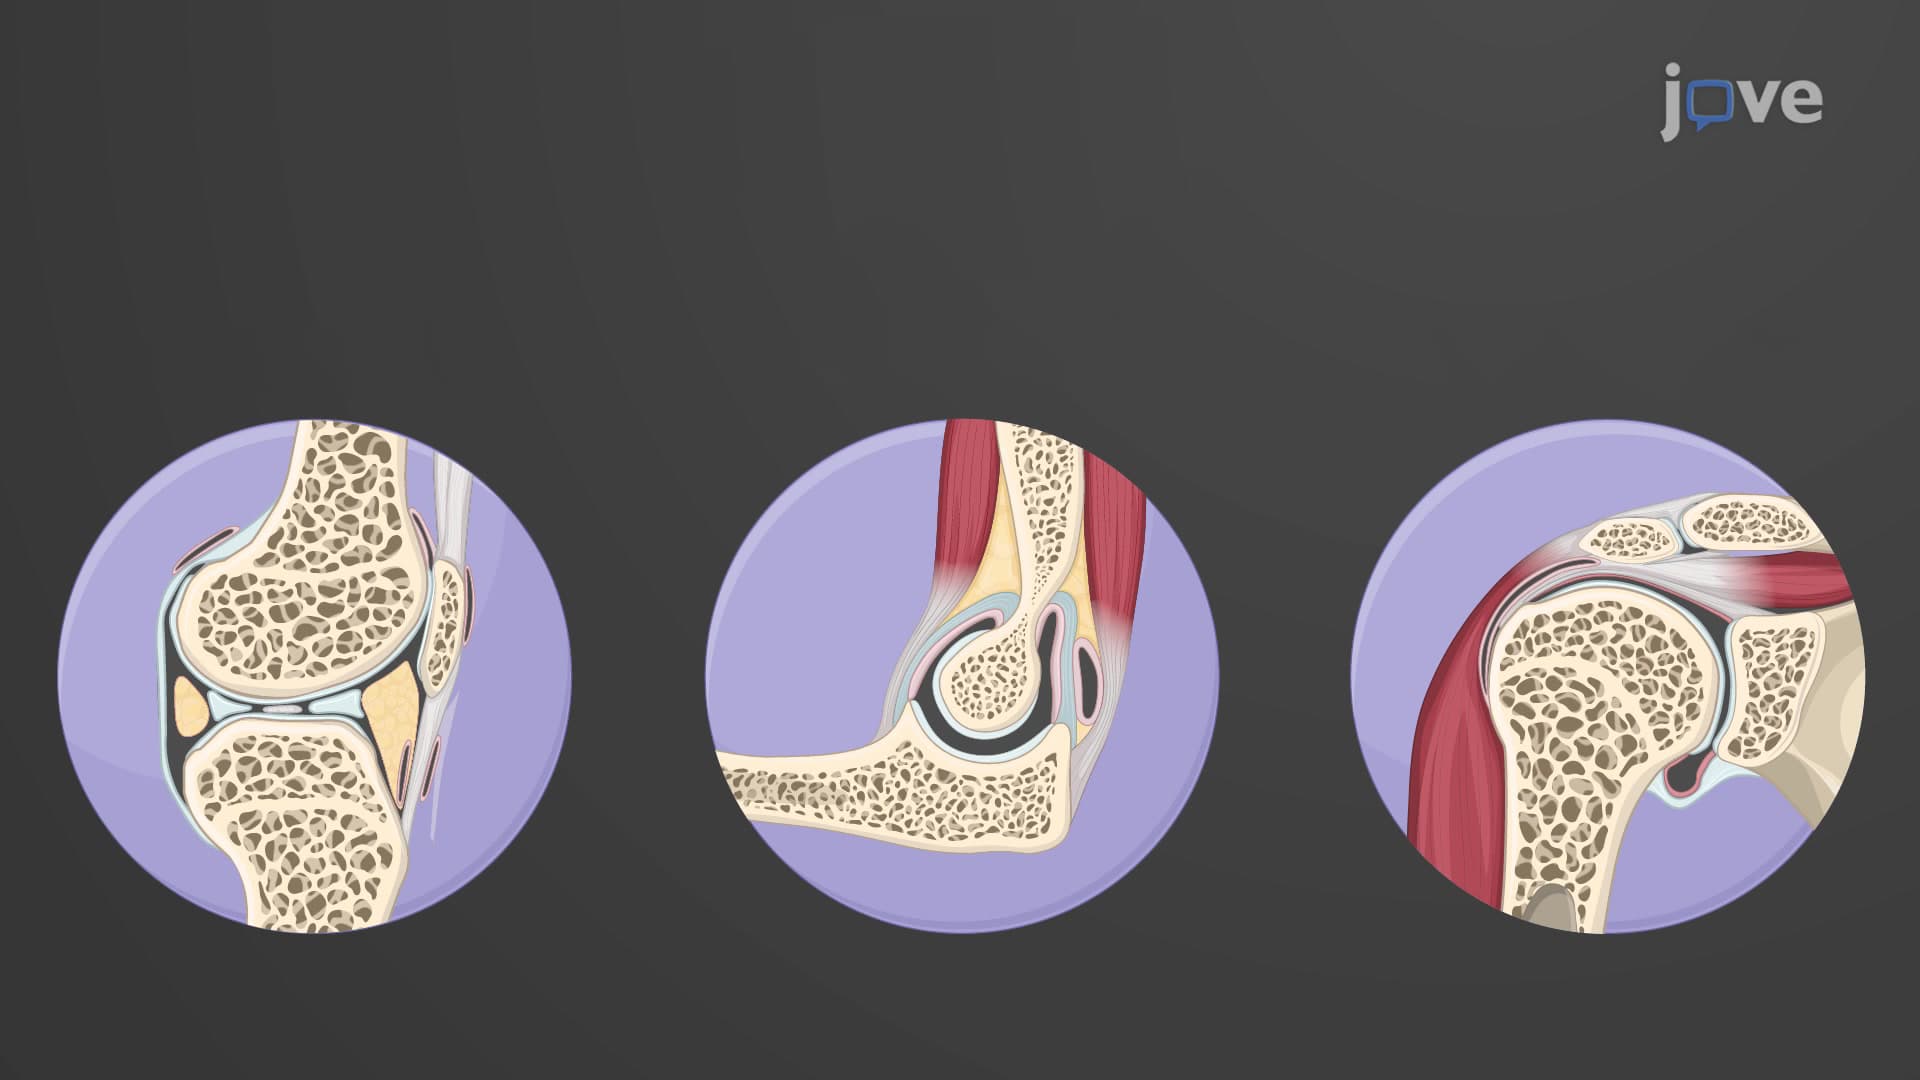
Functional Classification of Joints
The functional classification of joints is determined by the amount of mobility between the adjacent bones. Joints are functionally classified as a synarthrosis or immobile joint, an amphiarthrosis or slightly moveable joint, or as a diarthrosis, a freely moveable joint. Fibrous and cartilaginous joints can be functionally classified as either synarthroses or amphiarthroses, whereas all synovial joints are classified as diarthroses.
Synarthrosis
An...
 01:29
Bone Disorders
Bone deposition is also affected by the levels of sex hormones like estrogen and testosterone that promote osteoblast activity and bone matrix synthesis. When the level of these hormones decreases due to aging, it causes a reduction in bone deposition. As a result, bone resorption by osteoclasts...
 01:23
Knee Joint
A total of seven ligaments support the knee joint. The patellar ligament, which is also attached to the quadriceps femoris...