
Prediction of undernutrition and identification of its influencing predictors among under-five children in Bangladesh
Md Merajul Islam1,2, Nobab Md Shoukot Jahan Kibria1, Sujit Kumar1
1Department of Statistics, Jatiya Kabi Kazi Nazrul Islam University, Trishal, Mymensingh, Bangladesh.

Insights
Machine learning models can predict child undernutrition risk in Bangladesh. Key predictors include parental education, wealth, and child
Area of Science:
- Child health
- Machine learning applications
- Global public health
Background:
- Child undernutrition is a critical global health issue, particularly in developing nations like Bangladesh.
- Identifying and predicting undernutrition risk is essential for targeted interventions.
Purpose of the Study:
- To develop predictive models for child undernutrition risk in Bangladesh.
- To identify key predictors of stunting, wasting, and underweight using explainable AI.
Main Methods:
- Utilized Bangladesh Demographic and Health Survey (BDHS) 2017-18 data.
- Employed Boruta technique for predictor selection and XGBoost, Random Forest, ANN, and logistic regression for prediction.
- Applied SHapley Additive exPlanations (SHAP) for model interpretability.
Main Results:
- Extreme Gradient Boosting (XGB) model showed superior performance in predicting undernutrition.
- Identified significant predictors including father's education, mother's education, wealth, and child's BMI.
- SHAP analysis provided detailed insights into the influence of various socio-economic and health factors.
Conclusions:
- An integrated framework effectively predicts undernutrition risk and identifies critical influencing factors.
- The findings support targeted strategies to combat child undernutrition in Bangladesh.
Background And Objectives:
Child undernutrition is a leading global health concern, especially in low and middle-income developing countries, including Bangladesh. Thus, the objectives of this study are to develop an appropriate model for predicting the risk of undernutrition and identify its influencing predictors among under-five children in Bangladesh using explainable machine learning algorithms.
Materials And Methods:
This study used the latest nationally representative cross-sectional Bangladesh demographic health survey (BDHS), 2017-18 data. The Boruta technique was implemented to identify the important predictors of undernutrition, and logistic regression, artificial neural network, random forest, and extreme gradient boosting (XGB) were adopted to predict undernutrition (stunting, wasting, and underweight) risk. The models' performance was evaluated through accuracy and area under the curve (AUC). Additionally, SHapley Additive exPlanations (SHAP) were employed to illustrate the influencing predictors of undernutrition.
Results:
The XGB-based model outperformed the other models, with the accuracy and AUC respectively 81.73% and 0.802 for stunting, 76.15% and 0.622 for wasting, and 79.13% and 0.712 for underweight. Moreover, the SHAP method demonstrated that the father's education, wealth, mother's education, BMI, birth interval, vitamin A, watching television, toilet facility, residence, and water source are the influential predictors of stunting. While, BMI, mother education, and BCG of wasting; and father education, wealth, mother education, BMI, birth interval, toilet facility, breastfeeding, birth order, and residence of underweight.
Conclusion:
The proposed integrating framework will be supportive as a method for selecting important predictors and predicting children who are at high risk of stunting, wasting, and underweight in Bangladesh.

Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:52
Regression Toward the Mean
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:19
Variation
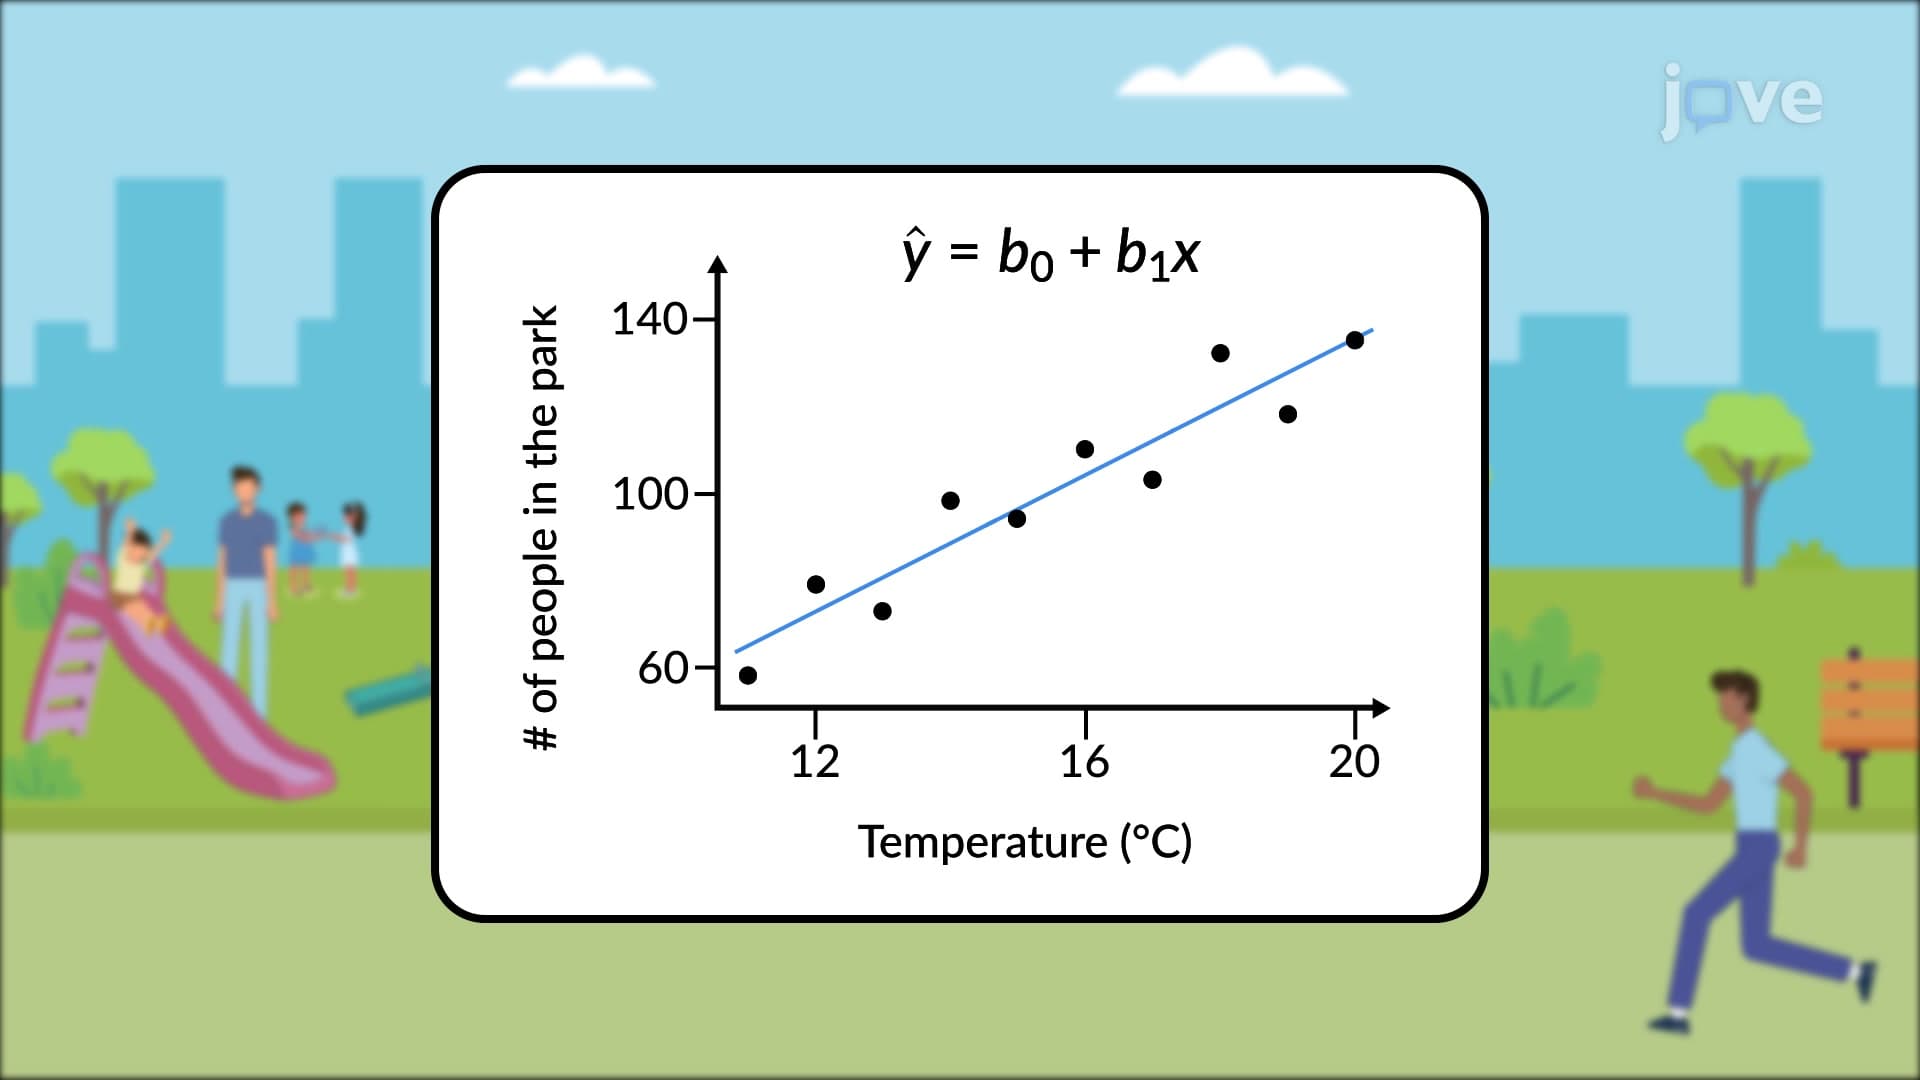
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as: