Related Experiment Video
Updated: Jun 5, 2025


An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
Approximation of reliabilities for random-regression single-step genomic best linear unbiased predictor models
M Bermann1, I Aguilar2, A Alvarez Munera1
1Department of Animal and Dairy Science, University of Georgia, Athens, GA 30602.

Abstract:
Random-regression models (RRM) are used in national genetic evaluations for longitudinal traits. The outputs of RRM are an index based on random-regression coefficients and its reliability. The reliabilities are obtained from the inverse of the coefficient matrix of mixed model equations (MME). The reliabilities must be approximated for large datasets because it is impossible to invert the MME. There is no extensive literature on methods to approximate the reliabilities of RRM when genomic information is included by single-step GBLUP. We developed an algorithm to approximate such reliabilities. Our method combines the reliability of the index without genomic information with the reliability of a GBLUP model in terms of effective record contributions. We tested our algorithm in the 3-lactation model for milk yield from the Czech Republic. The data had 30 million test-day records, 2.5 million animals in the pedigree, and 54,000 genotyped animals. The correlation between our approximation and the reliabilities obtained from the inversion of the MME was 0.98, and the slope and intercept of the regression were 0.91 and 0.02, respectively. The elapsed time to approximate the reliabilities for the Czech data was 21 min.
Related Concept Videos
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:19
Variation
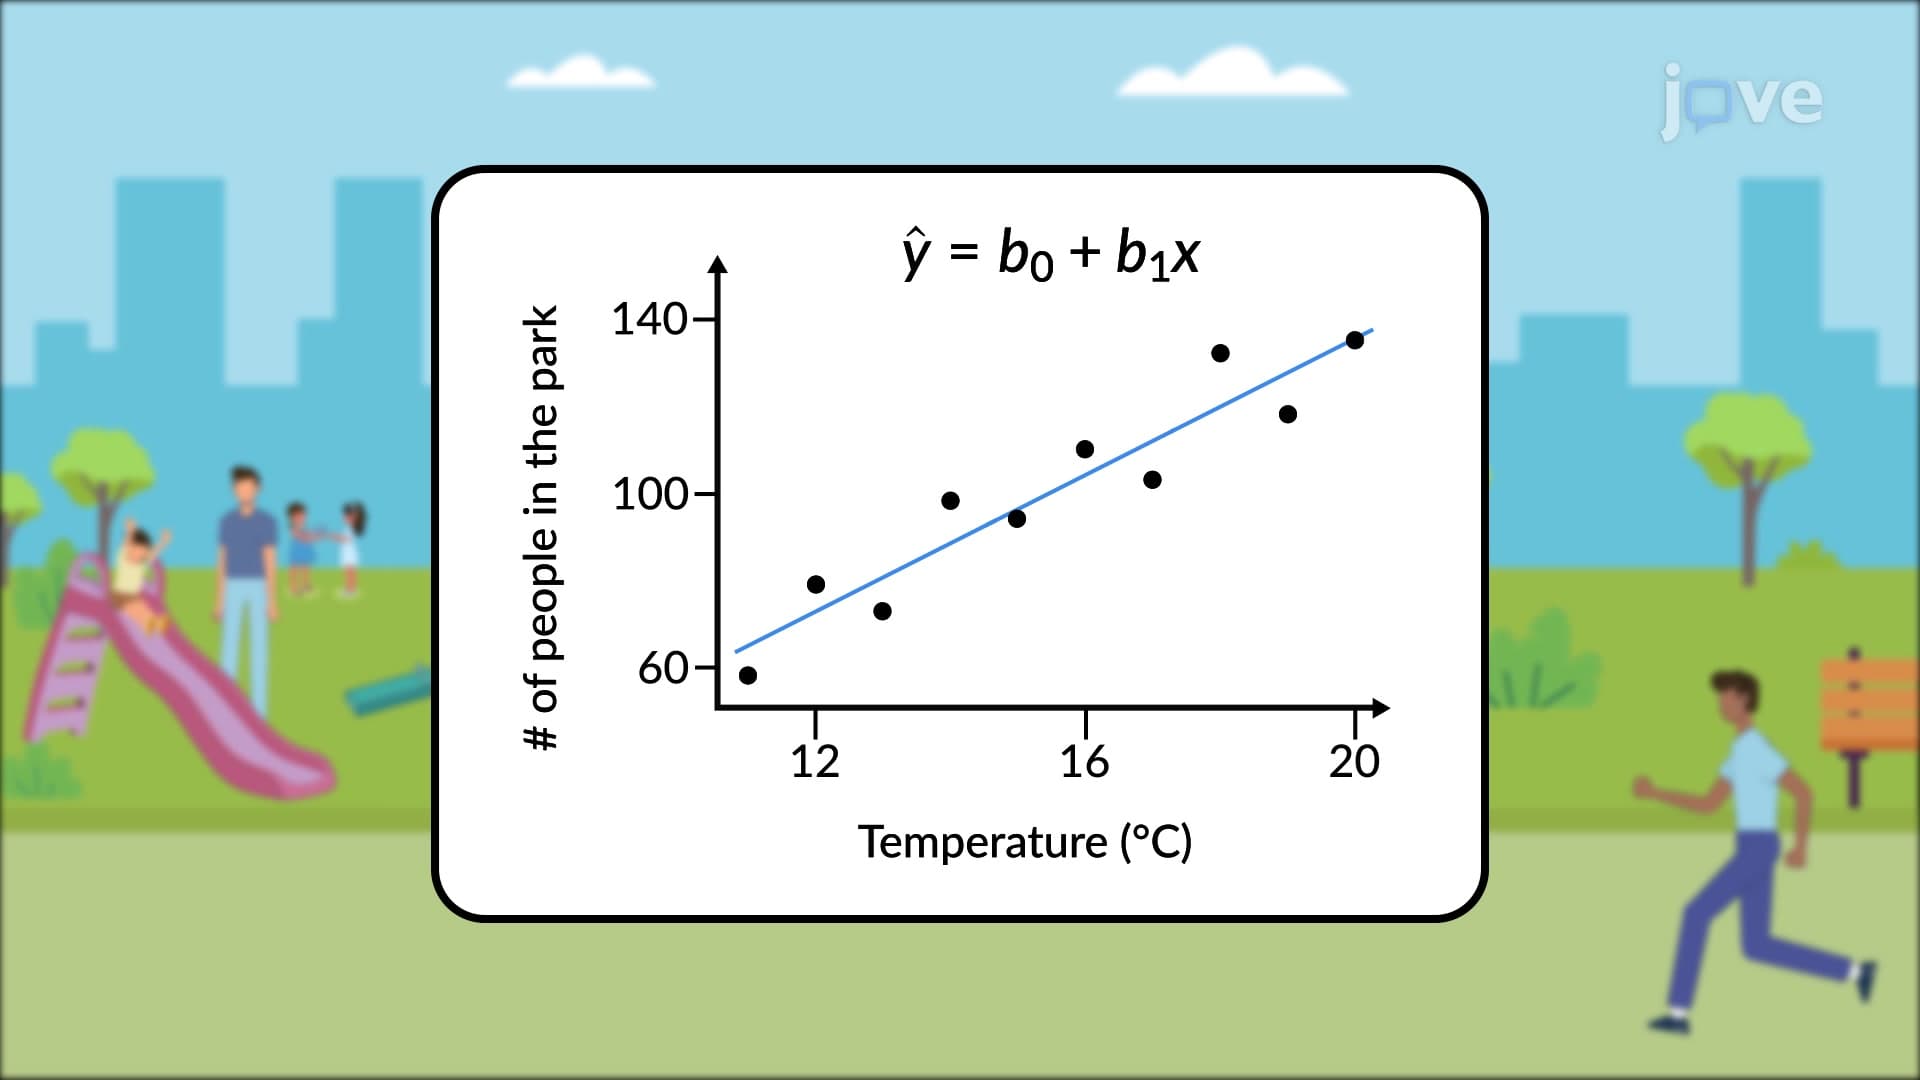
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...