Related Experiment Video
Updated: Jun 27, 2026

Measuring Attention and Visual Processing Speed by Model-based Analysis of Temporal-order Judgments
Published on: January 23, 2017
Quantifying interpretation reproducibility in Vision Transformer models with TAVAC
Yue Zhao1, Dylan Agyemang2, Yang Liu1
1The Jackson Laboratory for Genomic Medicine, Farmington, CT, USA.

Abstract:
Deep learning algorithms can extract meaningful diagnostic features from biomedical images, promising improved patient care in digital pathology. Vision Transformer (ViT) models capture long-range spatial relationships and offer robust prediction power and better interpretability for image classification tasks than convolutional neural network models. However, limited annotated biomedical imaging datasets can cause ViT models to overfit, leading to false predictions due to random noise. To address this, we introduce Training Attention and Validation Attention Consistency (TAVAC), a metric for evaluating ViT model overfitting and quantifying interpretation reproducibility. By comparing high-attention regions between training and testing, we tested TAVAC on four public image classification datasets and two independent breast cancer histological image datasets. Overfitted models showed significantly lower TAVAC scores. TAVAC also distinguishes off-target from on-target attentions and measures interpretation generalization at a fine-grained cellular level. Beyond diagnostics, TAVAC enhances interpretative reproducibility in basic research, revealing critical spatial patterns and cellular structures of biomedical and other general nonbiomedical images.
Related Concept Videos
 01:28
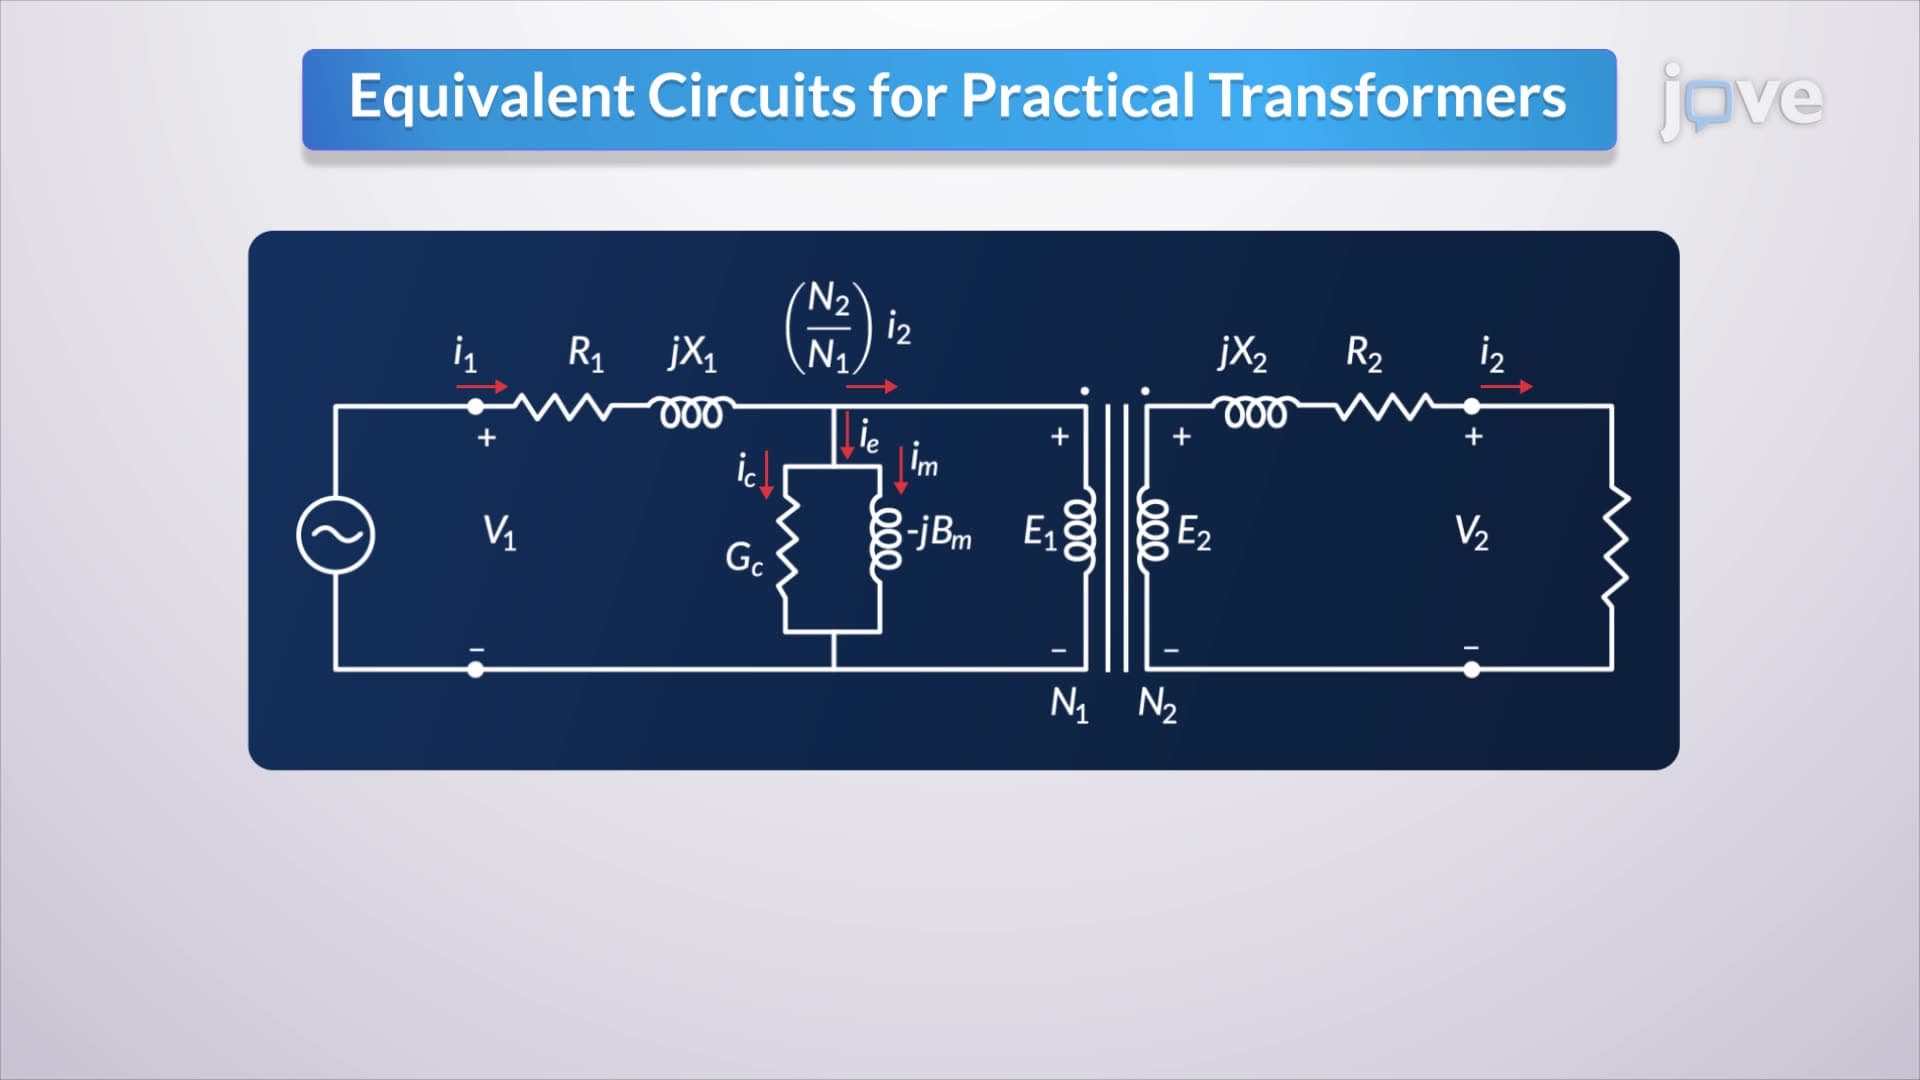
Equivalent Circuits for Practical Transformers
In a practical transformer, each winding exhibits resistance and leakage reactance. The winding...
 01:19
Three-Winding Transformers
In the per-unit equivalent circuit of a grounded Y-Y three-phase...
 01:25
Transformers with Off-Nominal Turns Ratios