Related Experiment Video
Updated: Jun 4, 2025

Milk Collection Methods for Mice and Reeves' Muntjac Deer
Published on: July 19, 2014
Invited review: A review of some commonly used meta-analysis methods in dairy science research
1Department of Animal Science, Michigan State University, East Lansing, MI 48824.

Abstract:
Meta-analyses have become increasingly common, providing meaningful summaries of cumulative knowledge in the dairy science literature. Some of the corresponding meta-analytic techniques have been developed by knowledgeable dairy scientists, some of which predate tractable likelihood-based random or mixed effects model meta-analytic techniques and associated software developed by statisticians. This review compares various meta-analytic techniques on aggregate data (i.e., study-specific treatment effect or slope estimates and their standard errors) generated from simulated data involving regression, completely randomized designs (CRD), and Latin square design scenarios. In all cases, meta-estimates generated from the analysis of individual performance data (IPD), using the same statistical model as that used to simulate the data, were considered to be gold-standard references for meta-estimates derived from various meta-analysis strategies on aggregate data. In all cases, likelihood-based techniques outperformed techniques developed by dairy scientists for meta-estimate proximity to corresponding IPD estimates. An extensive simulation study comparing meta-analytic techniques within a CRD framework indicated that these advantages widen with increasing study heterogeneity in effect sizes, smaller number of experimental replicates (i.e., cows) per treatment per study, and lower within-study variability; nevertheless, the impact of meta-analytic methods on estimated standard errors of these meta-estimates were rather trivial. To best utilize aggregate data from Latin square studies in meta-analyses, a concerted effort is required to recover standard errors of mean differences rather than the standard errors of the means themselves. Perhaps the most compelling reason for choosing likelihood-based methods for meta-analysis is their ability to provide reliable prediction intervals on effect sizes, noting that these intervals are currently under-reported in the dairy science literature. Compared with the reporting of meta-estimates and their standard errors, prediction intervals provide a far more appropriate indication of uncertainty on treatment effects in future studies and should be greater emphasized in extension or outreach efforts. Although R software packages such as metafor are readily available for likelihood-based methods, both SAS and R code for linear mixed models can be readily modified to facilitate these analyses as demonstrated extensively in the supplemental materials of this review.
Related Concept Videos
 01:12
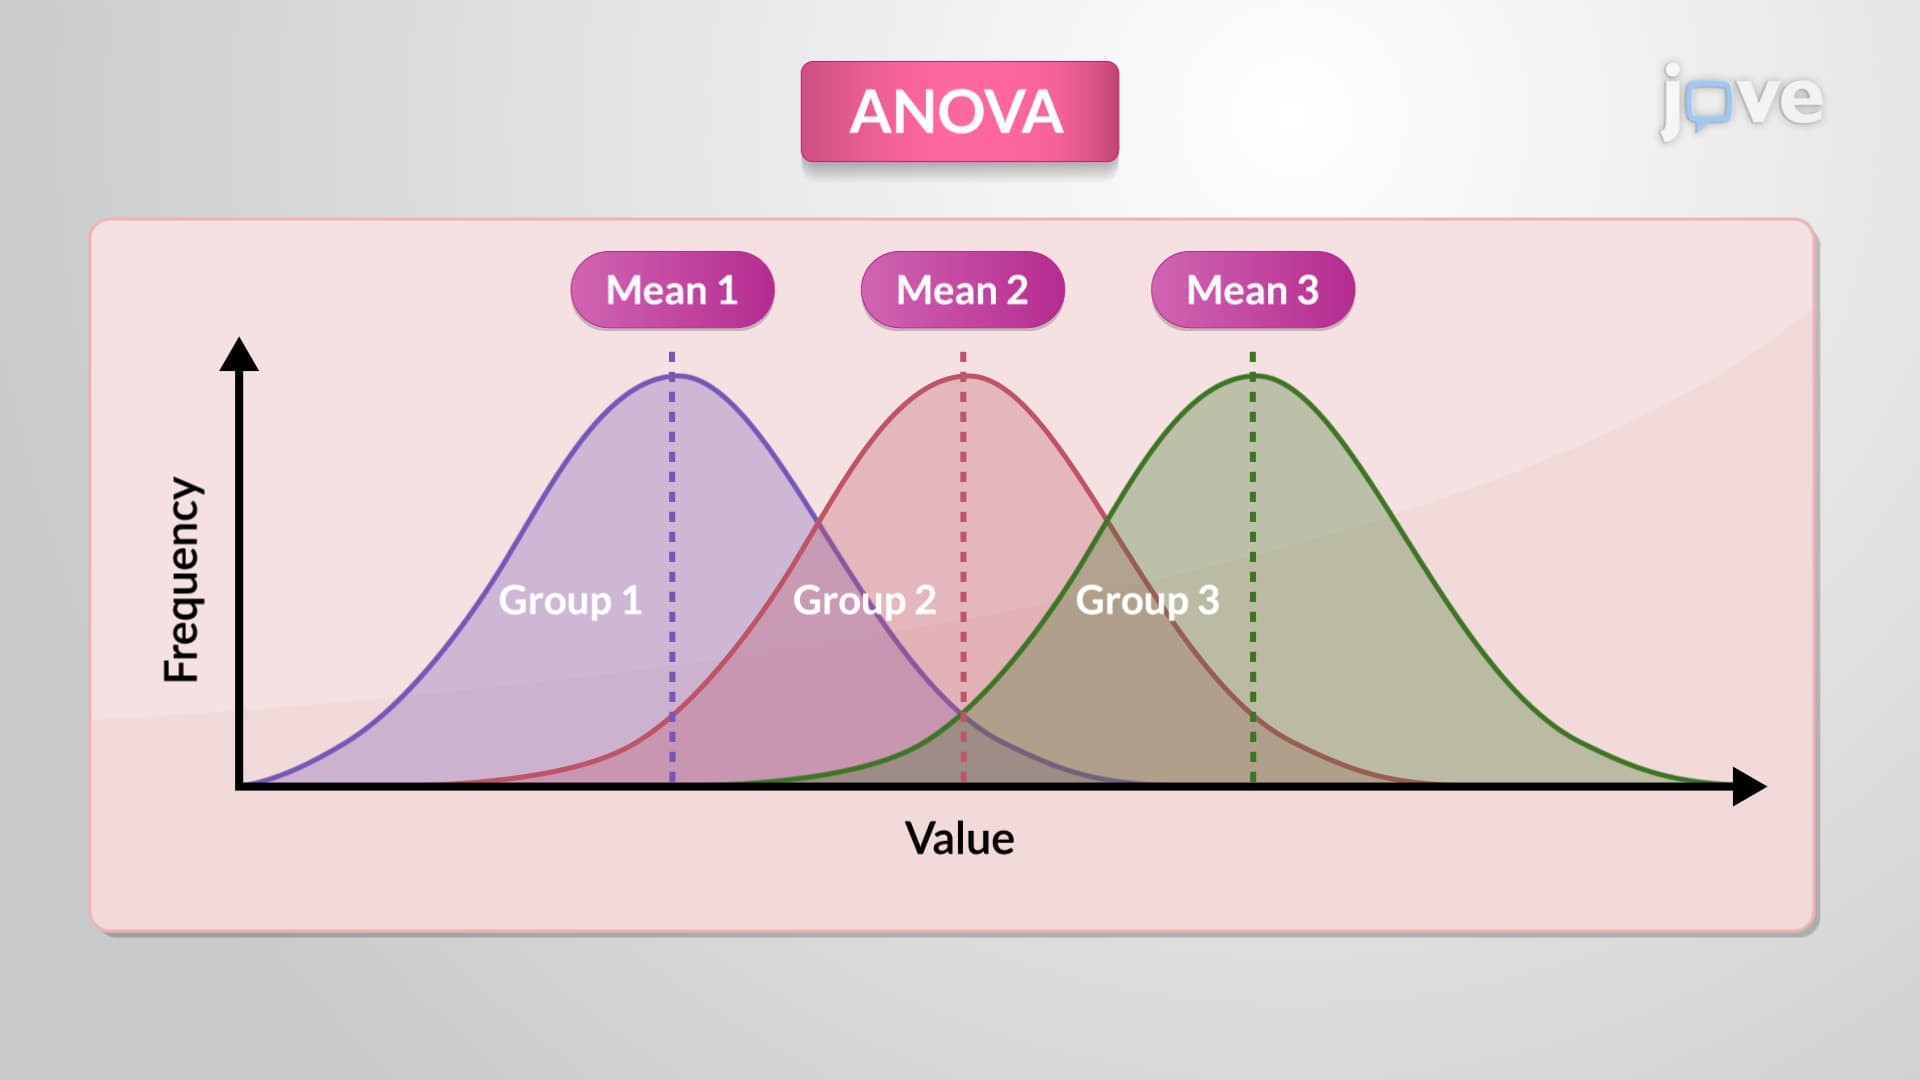
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:16
What is an ANOVA?
Before performing ANOVA, one must ensure that the samples used for this analysis have three crucial characteristics or statistical assumptions. The first assumption states that the samples should be drawn from normally distributed samples, while the second requires that all the drawn samples should be randomly and...
 01:23
Types of Biopharmaceutical Studies: Controlled and Non-Controlled Approaches
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast,...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:13
What is ANOVA?
Before performing ANOVA, one must ensure that the samples used for this analysis have three crucial characteristics or statistical assumptions. The first assumption states that the samples should be drawn from normally distributed samples, while the second requires that all the drawn samples be randomly and independently...