Related Experiment Video
Updated: May 31, 2025
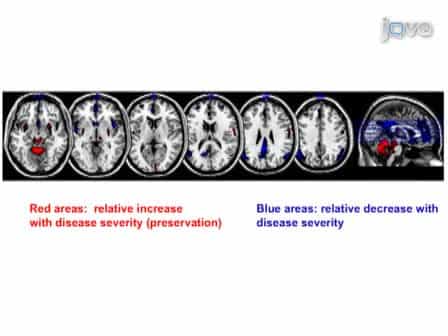

Basics of Multivariate Analysis in Neuroimaging Data
Published on: July 24, 2010
High-dimensional multiple imputation for partially observed confounders including natural language processing-derived
Janick Weberpals1, Pamela A Shaw2, Kueiyu Joshua Lin1
1Division of Pharmacoepidemiology and Pharmacoeconomics, Department of Medicine, Brigham and Women's Hospital, Harvard Medical School, Boston, MA, United States.

Abstract:
Multiple imputation (MI) models can be improved with auxiliary covariates (ACs), but their performance in high-dimensional data remains unclear. We aimed to develop and compare high-dimensional MI (HDMI) methods using structured and natural language processing (NLP)-derived AC in studies with partially observed confounders. We conducted a plasmode simulation with acute kidney injury as outcome and simulated 100 cohorts with a null treatment effect, incorporating creatinine labs, atrial fibrillation (AFib), and other investigator-derived confounders in the outcome generation. Missingness was imposed on creatinine based on creatinine itself and AFib. Different HDMI candidate ACs were created using structured and NLP-derived features, and we mimicked scenarios where AFib was unobserved by omitting it from all analyses. Using the least absolute shrinkage and selection operator, we selected HDMI covariates for MI and propensity score models. The treatment effect was estimated after propensity score matching in MI datasets, and HDMI methods were compared to baseline imputation and complete case analysis. High-dimensional MI using claims data showed the lowest bias (0.072). Combining claims and sentence embeddings led to an improvement in the efficiency with a root mean square error (RMSE) of 0.173 and 94% coverage. Natural language processing-derived AC alone did not outperform baseline MI. High-dimensional MI approaches may decrease bias in studies where confounder missingness depends on unobserved factors.
More Related Videos
 06:48
Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
 08:19
Simultaneous Data Collection of fMRI and fNIRS Measurements Using a Whole-Head Optode Array and Short-Distance Channels
Published on: October 20, 2023
Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:27
Confounding in Epidemiological Studies
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:25
Strategies for Assessing and Addressing Confounding
Confounding can be addressed at both the design phase of a study and through analytical methods after data...
 01:22
Multi-input and Multi-variable systems
In the absence...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.