Computational Study Protocol: Leveraging Synthetic Data to Validate a Benchmark Study for Differential Abundance Tests for 16S Microbiome Sequencing Data
Related Experiment Video
Updated: May 3, 2026
Guided Protocol for Fecal Microbial Characterization by 16S rRNA-Amplicon Sequencing
Published on: March 19, 2018
1Institute of Medical Biometry and Statistics, Faculty of Medicine and Medical Center, University of Freiburg, Baden-Württemberg, Germany.

Background:
Synthetic data's utility in benchmark studies depends on its ability to closely mimic real-world conditions and reproduce results obtained from experimental data. Building on Nearing et al.'s study (1), who assessed 14 differential abundance tests using 38 experimental 16S rRNA datasets in a case-control design, we are generating synthetic datasets that mimic the experimental data to verify their findings. We will employ statistical tests to rigorously assess the similarity between synthetic and experimental data and to validate the conclusions on the performance of these tests drawn by Nearing et al. (1). This protocol adheres to the SPIRIT guidelines, demonstrating how established reporting frameworks can support robust, transparent, and unbiased study planning.
Methods:
We replicate Nearing et al.'s (1) methodology, incorporating synthetic data simulated using two distinct tools, mirroring the 38 experimental datasets. Equivalence tests will be conducted on a non-redundant subset of 46 data characteristics comparing synthetic and experimental data, complemented by principal component analysis for overall similarity assessment. The 14 differential abundance tests will be applied to synthetic and experimental datasets, evaluating the consistency of significant feature identification and the number of significant features per tool. Correlation analysis and multiple regression will explore how differences between synthetic and experimental data characteristics may affect the results.
Conclusions:
Synthetic data enables the validation of findings through controlled experiments. We assess how well synthetic data replicates experimental data, try to validate previous findings with the most recent versions of the DA methods and delineate the strengths and limitations of synthetic data in benchmark studies. Moreover, to our knowledge this is the first computational benchmark study to systematically incorporate synthetic data for validating differential abundance methods while strictly adhering to a pre-specified study protocol following SPIRIT guidelines, contributing to transparency, reproducibility, and unbiased research.
Related Concept Videos
 01:29
Modern Molecular Taxonomy
 01:19
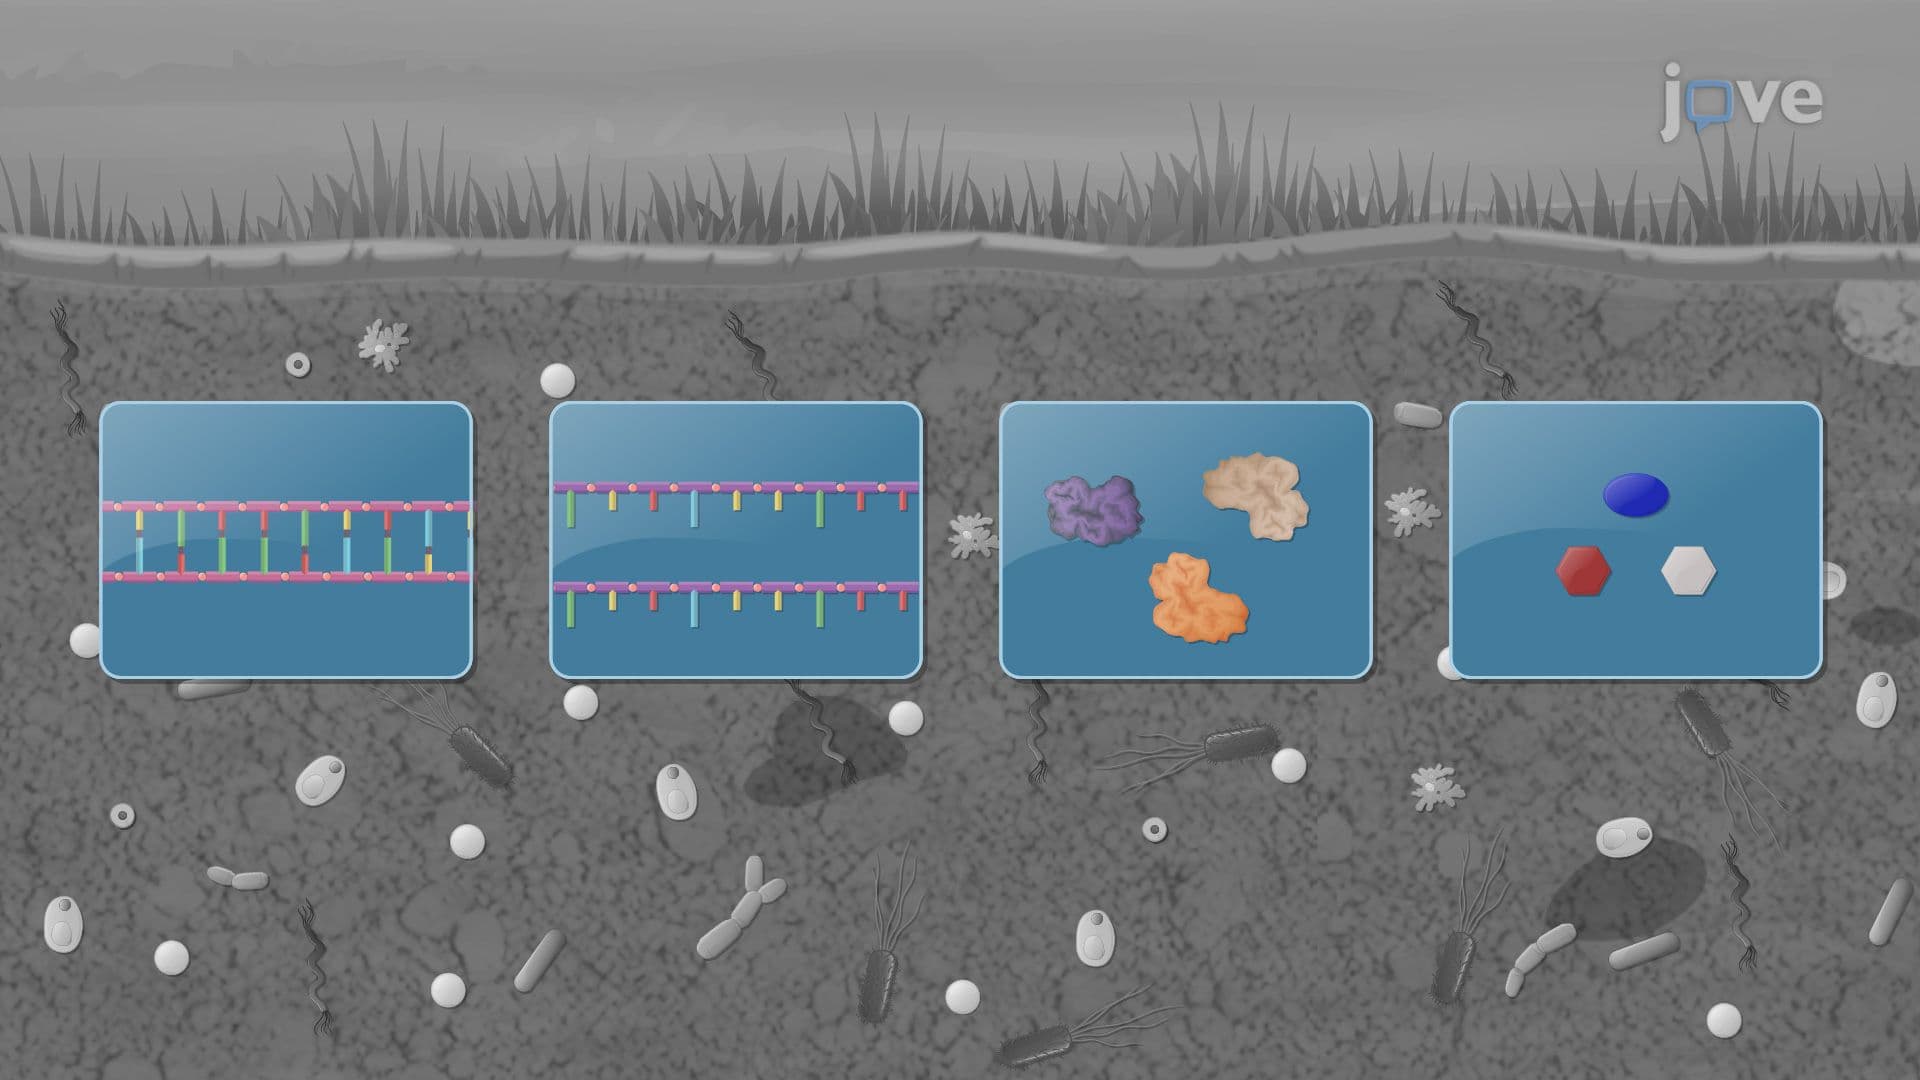
Methods to Assess Microbial Communities