Related Experiment Video
Updated: May 30, 2025

Identification of Alternative Splicing and Polyadenylation in RNA-seq Data
Published on: June 24, 2021
Missing value replacement in strings and applications
Giulia Bernardini1, Chang Liu2, Grigorios Loukides3
1Department of Mathematics, Informatics and Geosciences, University of Trieste, Trieste, Italy.

Abstract:
Missing values arise routinely in real-world sequential (string) datasets due to: (1) imprecise data measurements; (2) flexible sequence modeling, such as binding profiles of molecular sequences; or (3) the existence of confidential information in a dataset which has been deleted deliberately for privacy protection. In order to analyze such datasets, it is often important to replace each missing value, with one or more valid letters, in an efficient and effective way. Here we formalize this task as a combinatorial optimization problem: the set of constraints includes the context of the missing value (i.e., its vicinity) as well as a finite set of user-defined forbidden patterns, modeling, for instance, implausible or confidential patterns; and the objective function seeks to minimize the number of new letters we introduce. Algorithmically, our problem translates to finding shortest paths in special graphs that contain forbidden edges representing the forbidden patterns. Our work makes the following contributions: (1) we design a linear-time algorithm to solve this problem for strings over constant-sized alphabets; (2) we show how our algorithm can be effortlessly applied to fully sanitize a private string in the presence of a set of fixed-length forbidden patterns [Bernardini et al. 2021a]; (3) we propose a methodology for sanitizing and clustering a collection of private strings that utilizes our algorithm and an effective and efficiently computable distance measure; and (4) we present extensive experimental results showing that our methodology can efficiently sanitize a collection of private strings while preserving clustering quality, outperforming the state of the art and baselines. To arrive at our theoretical results, we employ techniques from formal languages and combinatorial pattern matching.
Related Concept Videos
 01:20
Mismatch Repair
The Mutator Protein Family Plays a Key Role in DNA Mismatch Repair
The human genome has more than 3 billion base pairs of DNA per cell. Prior to cell division, that vast amount of genetic...
 02:52
Predicting Products: Substitution vs. Elimination
The following factors can influence the mechanisms competing against each other:
 02:18
Alternative RNA Splicing
 02:27
Nonsense-mediated mRNA Decay
 02:34
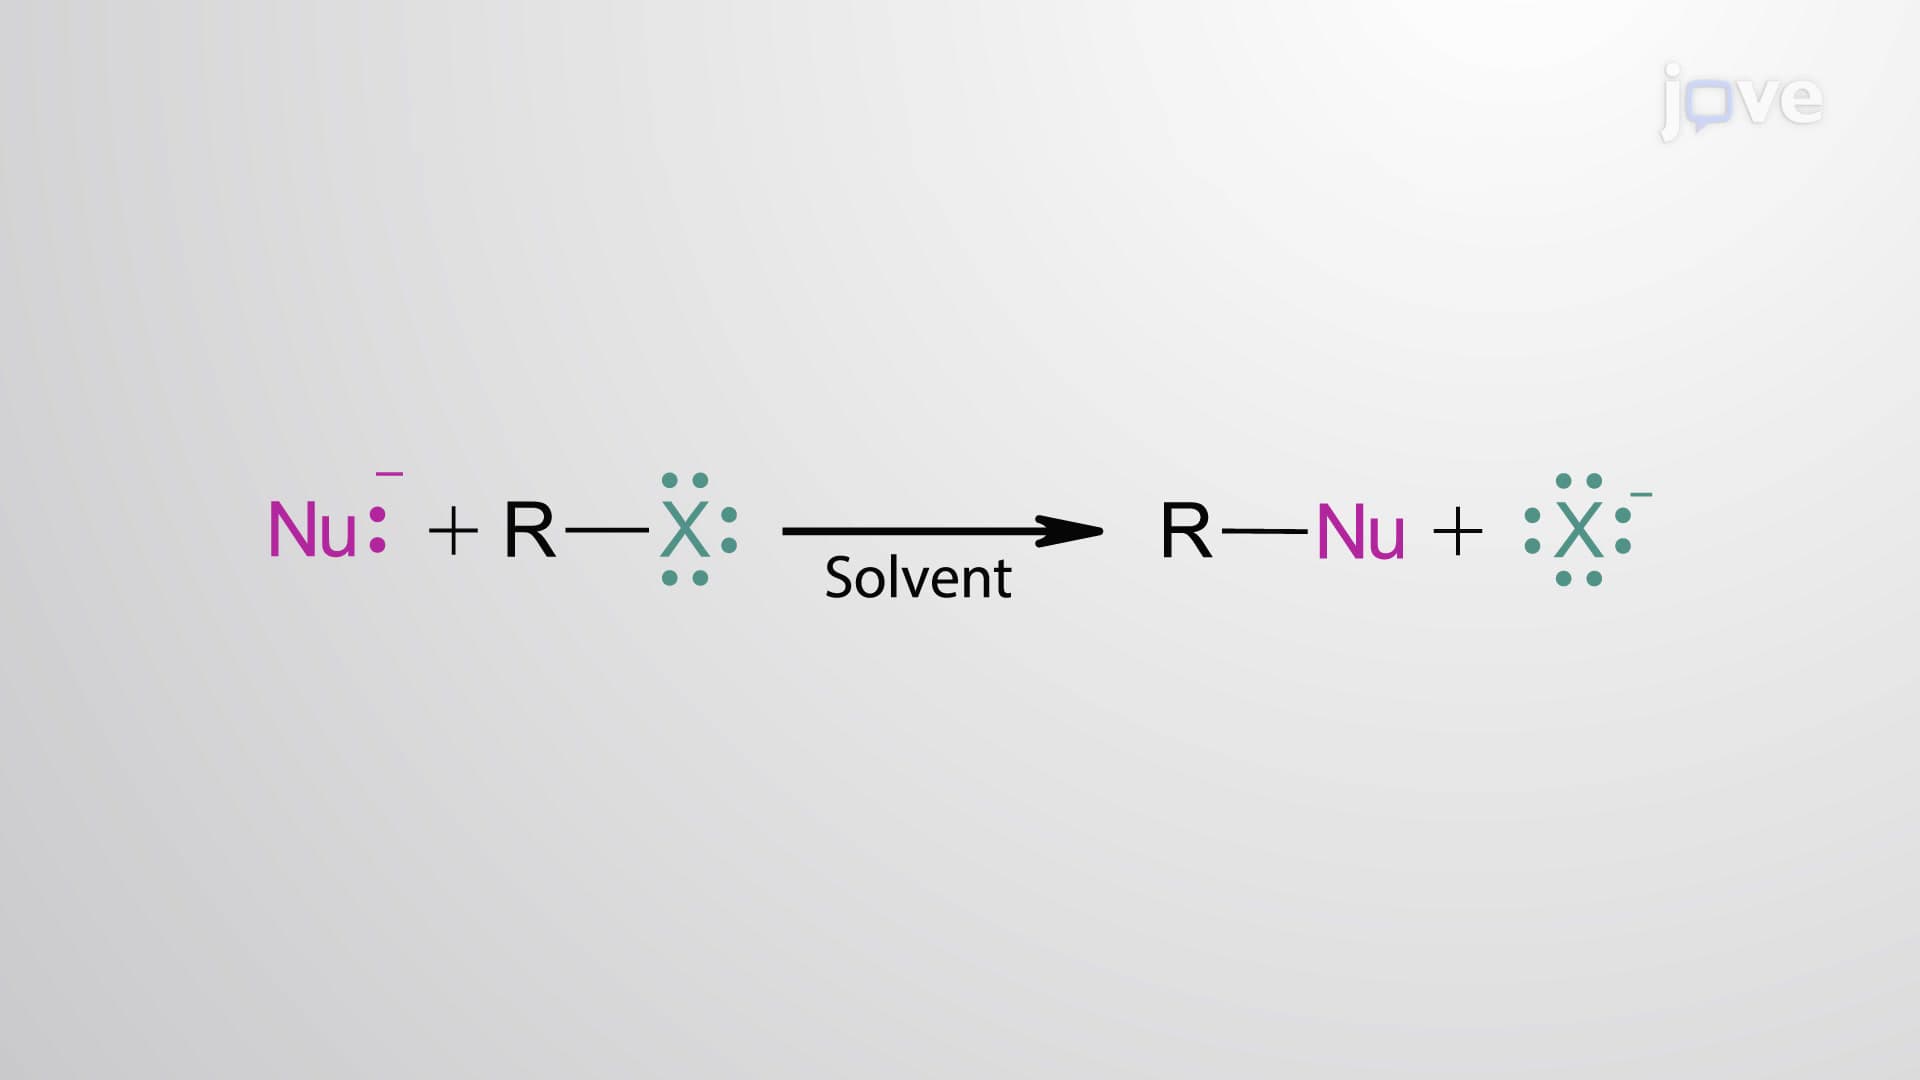
Nucleophilic Substitution Reactions
In 1896, the German chemist Paul Walden discovered that he could interconvert pure enantiomeric (+) and (-) malic acids through a series of reactions. This conversion suggested the involvement of optical inversion during the substitution reaction. Further, in 1930, Sir Christopher Ingold described for the first time two different forms of nucleophilic substitution reactions, which are known as SN1 (nucleophilic substitution unimolecular) and SN2 (nucleophilic substitution...
 01:35
Mutations
Chromosomal Alterations Are Large-Scale Mutations
While point mutations are changes in a single nucleotide in...