Related Experiment Video
Updated: May 29, 2025

Cloud-Based Phrase Mining and Analysis of User-Defined Phrase-Category Association in Biomedical Publications
Published on: February 23, 2019
Project Victoria: A pragmatic data model to automate RWE generation from the national French claims database
Kevin Ouazzani1, Xavier Ansolabehere1, Florence Journeau1
1Clinityx, Boulogne-Billancourt, France.

Abstract:
Objective: This paper describes Victoria, an empirically built data pipeline for SNDS to: - Build an automated, scalable pipeline supporting changes to the data model inherent to the use of large databases, - Deliver a documented pipeline with clear processes, enabling scientific, epidemiological researches, - Ease access to SNDS data in compliance with regulatory requirements. Methods: This paper describes the 2-steps process of the Victoria pipeline and its final output. The initial cleaning step consists in formatting, deleting empty, error or duplicate records and renaming variables without changing their values, accordingly with the official SNDS documentation. The second step consists in creating 2 linearised data models: every line of each table is an event, and each table is indexed with a unique patient identifier, without the need for a central patient or identifier table. These 2 models are: - the epidemiological model, used for answering most of the research questions requiring population phenotyping (demography, diagnosis, procedures characteristics). - the medico-economic model is used for costs and healthcare consumption analyses. It contains more complex information about reimbursements rates and the data quality assessment is focused on costs rather than medico-administrative information. Results: The pipeline was executed on 2 different datasets representing ∼85 000 and ∼870 000 beneficiaries with the following configuration: one master with 4 cores and 16Go of RAM and respectively 4 and 6 workers. The total execution time for the smaller dataset was 25 h and 96 h for the larger one. The longest part of those times is represented by the format conversion to parquet. The cleaning step took only 4 h in both cases. The epidemiological model took 344 min for the smaller dataset and 1934 min for the larger one. The medico-economic model took the longest time with 704 min and 2145 min, respectively. Conclusion: Victoria pipeline is a successfully implemented SNDS pipeline. Compared to previous pipelines, reviewability is part of its design as unit tests and quality assessments can natively be developed to ensure data and analysis quality. The pipeline has been used for 2 published studies. The recent work toward OMOP conversion will be integrated in upcoming versions and, as Victoria is set to run on a CD platform, the potential evolution if SNDS format can be considered.
More Related Videos

Related Concept Videos
 01:29
Econometric Views (EViews)
 01:13
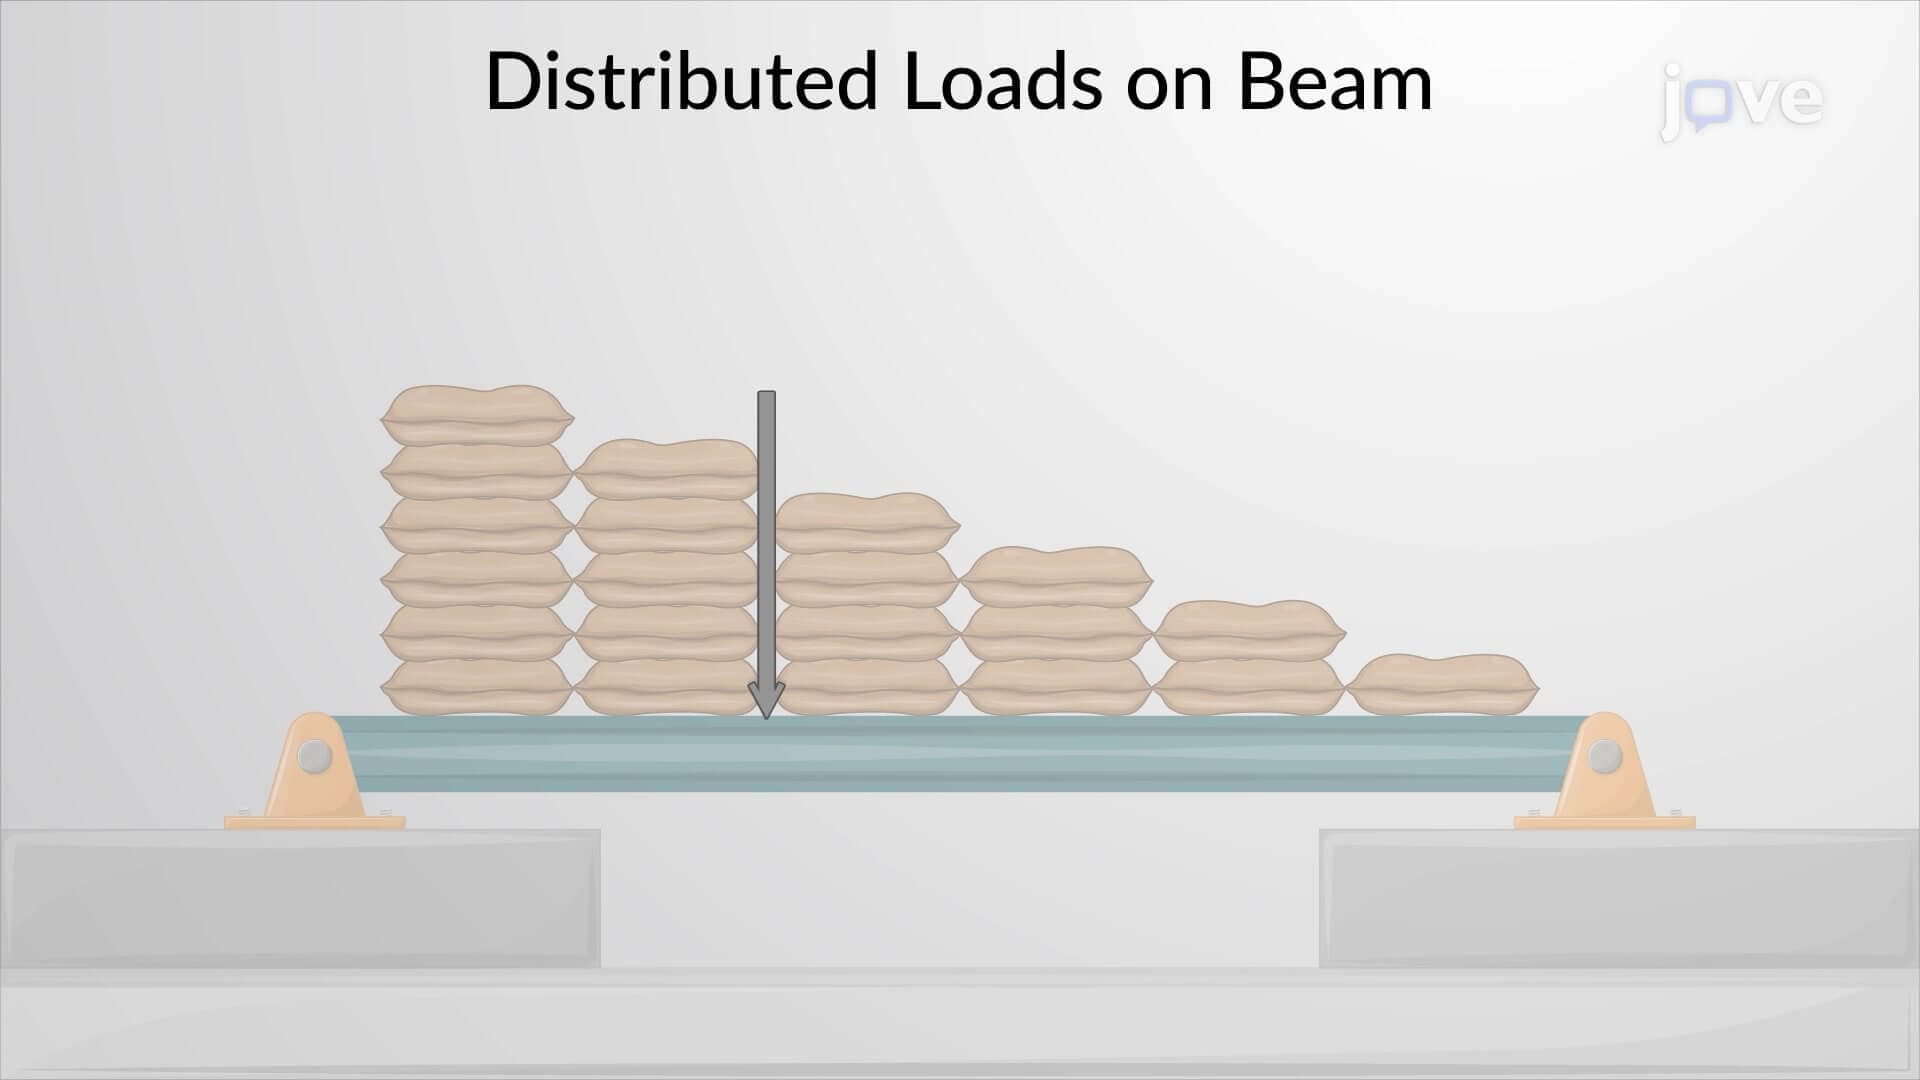
Resultant of a General Distributed Loading
Examples such as load distribution due to wind and load distribution on a bridge illustrate how this concept is used to analyze and design safe, reliable structures under variable loading conditions. Most structures, such as residential buildings, bridges, and towers, are...
 01:17
Design Example: Analyzing Capacity Contours for Flood Risk Assessment
 01:18
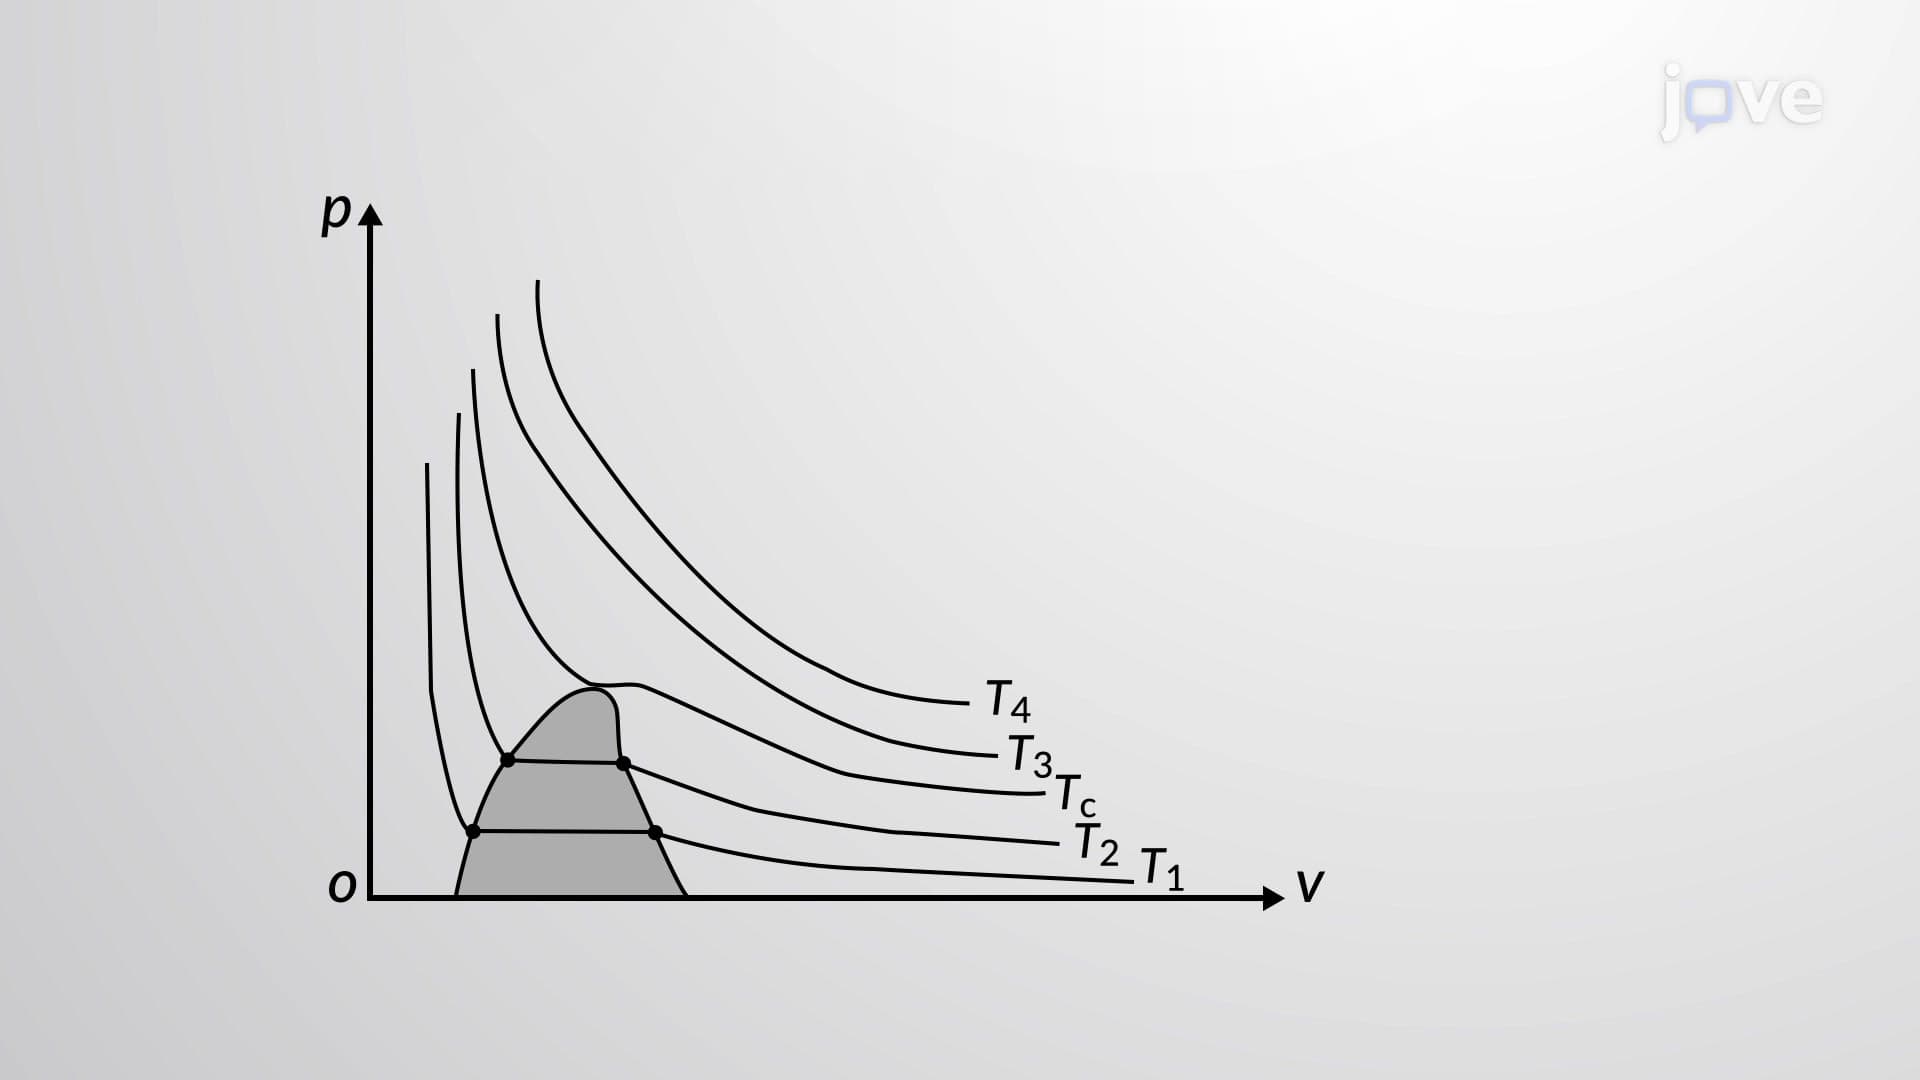
pV-Diagrams
 01:23
GIS Software, Hardware, and Sources of GIS Data
 01:21
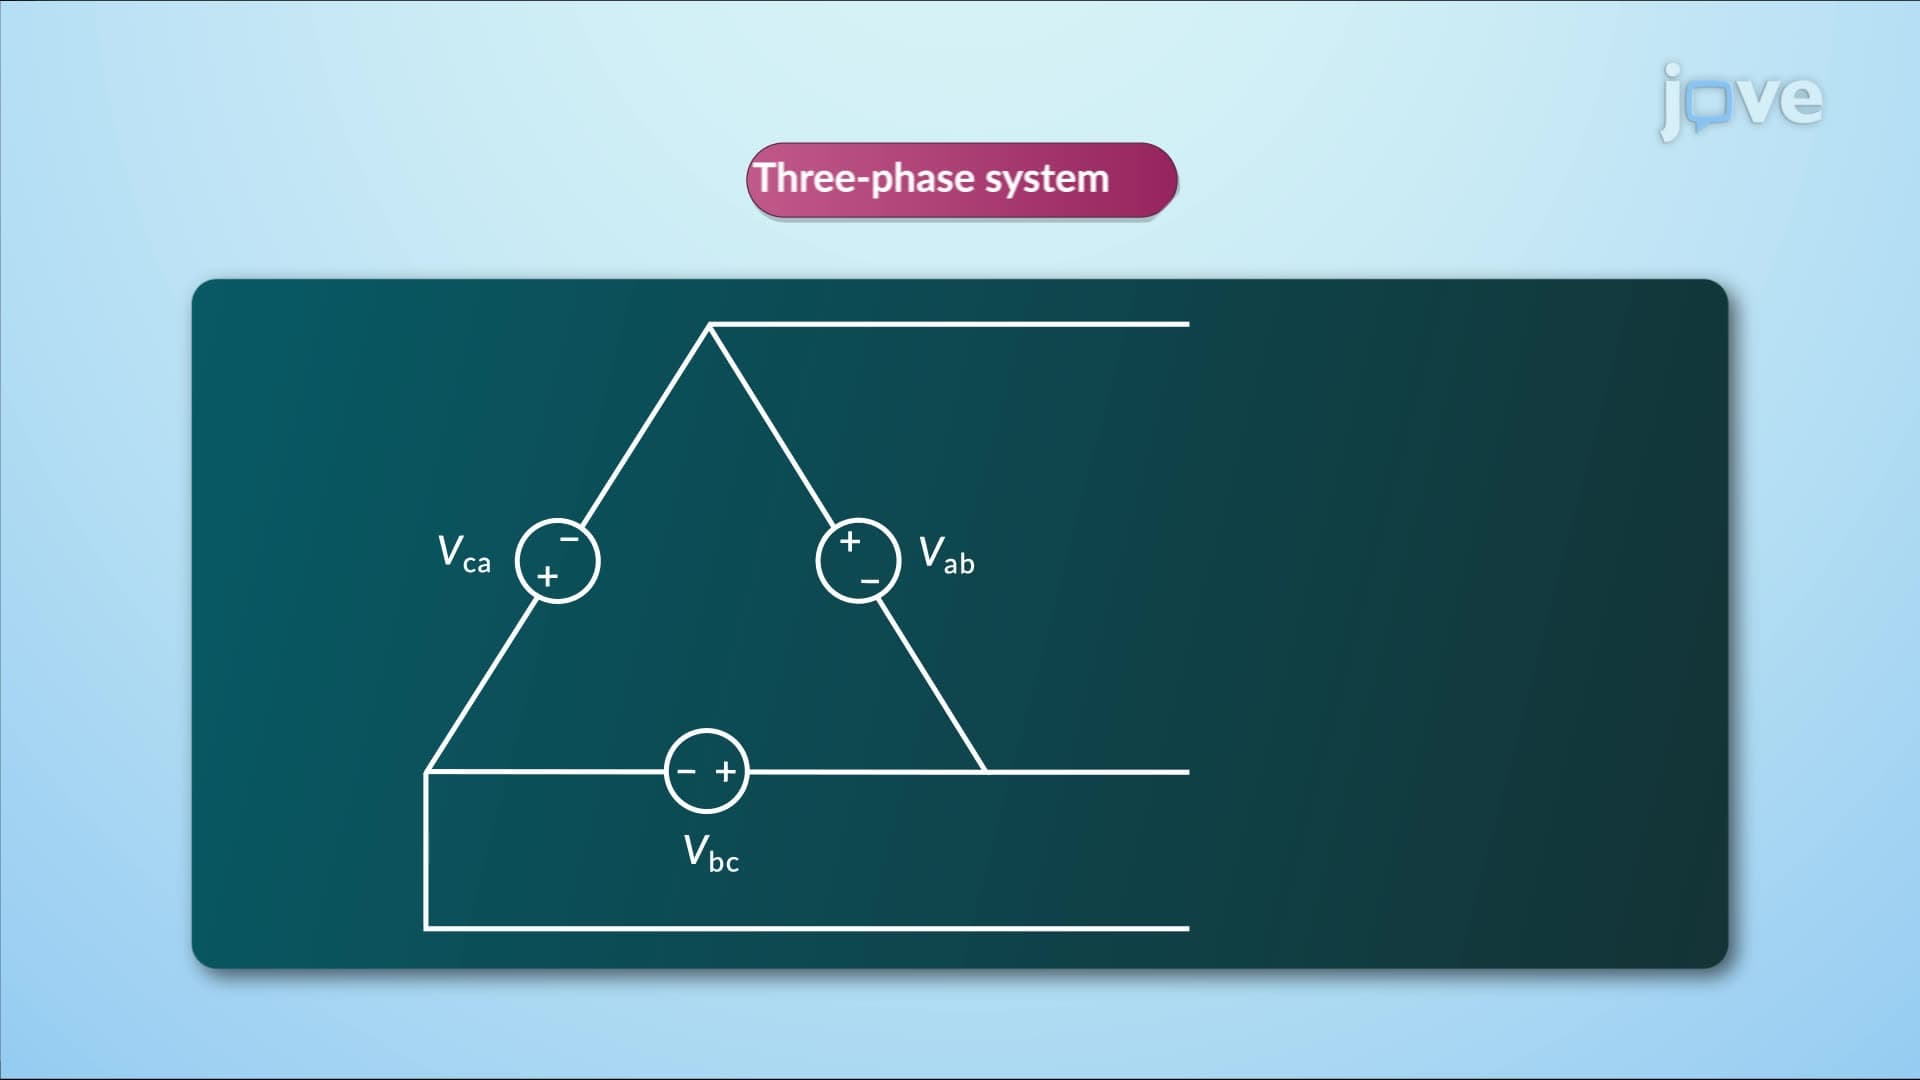
Generation of Three-Phase Voltage
As the rotor...