Related Experiment Video
Updated: May 25, 2025
Author Spotlight: Emerging Technologies and Advanced Tools for Decoding Metabolomics Data Analysis
Published on: November 10, 2023
A critical analysis of Adaptive Box-Cox transformation for skewed distributed data management: Metabolomics of
Leonardo Sibono1, Massimiliano Grosso1, Eva Tejedor-Calvo2
1Department of Mechanical, Chemical and Materials Engineering, Via Marengo 2, Università degli Studi di Cagliari, Cagliari, Italy.

Background:
Metabolic variations retrieved in metabolomic data are considered a benchmark for detecting biomatrix variability. Therefore, identifying target metabolites is crucial to keep track of any substrate modification and preserve it from any undesired alteration. Unfortunately, such a task can be negatively affected by detecting false positives, often triggered by complicated data distributions. In this work, we undertook an investigation of the metabolic profile of Spanish and Argentine truffles using a robust methodology. The issue of skewed data distributions has been effectively addressed through a normalization preprocessing, enhancing biomarker identification and samples classification.
Results:
A data normality-improved parametric test (ANOVA) was employed to define the target metabolites, which significantly vary between two regions of origin: Spain and Argentina. Specifically, Adaptive Box-Cox transformation was employed to improve the ANOVA test's performance so that data distributions were fitted to a Gaussian variable. Using the Bonferroni-Holm method for false discovery rate correction, we demonstrated the effectiveness of this transformation for the case under investigation. Results were compared with two non-parametric tests (Kruskall-Wallis and Permutation test), selected as a reference methodology, to provide a better understanding of non-normal distributions often encountered in metabolomic data analysis. 17 metabolites out of the 57 investigated metabolites exhibited notable variability across the two geographical regions. The validity of this methodology was supported through the discrimination of samples belonging to different groups. In this regard, both univariate and multivariate statistical models were tested through Monte Carlo simulations and yielded consistent results.
Significance:
Data analysis outcomes are sensitive to variables distributions. The present study shows an effective tool to increase data normality, thereby enhancing the statistical power for biomarker discovery and improving models' classification performances. These results find justification from the current knowledge within the field of food sciences, enabling their application in advancing research in the truffle analysis domain.
Related Concept Videos
 00:57
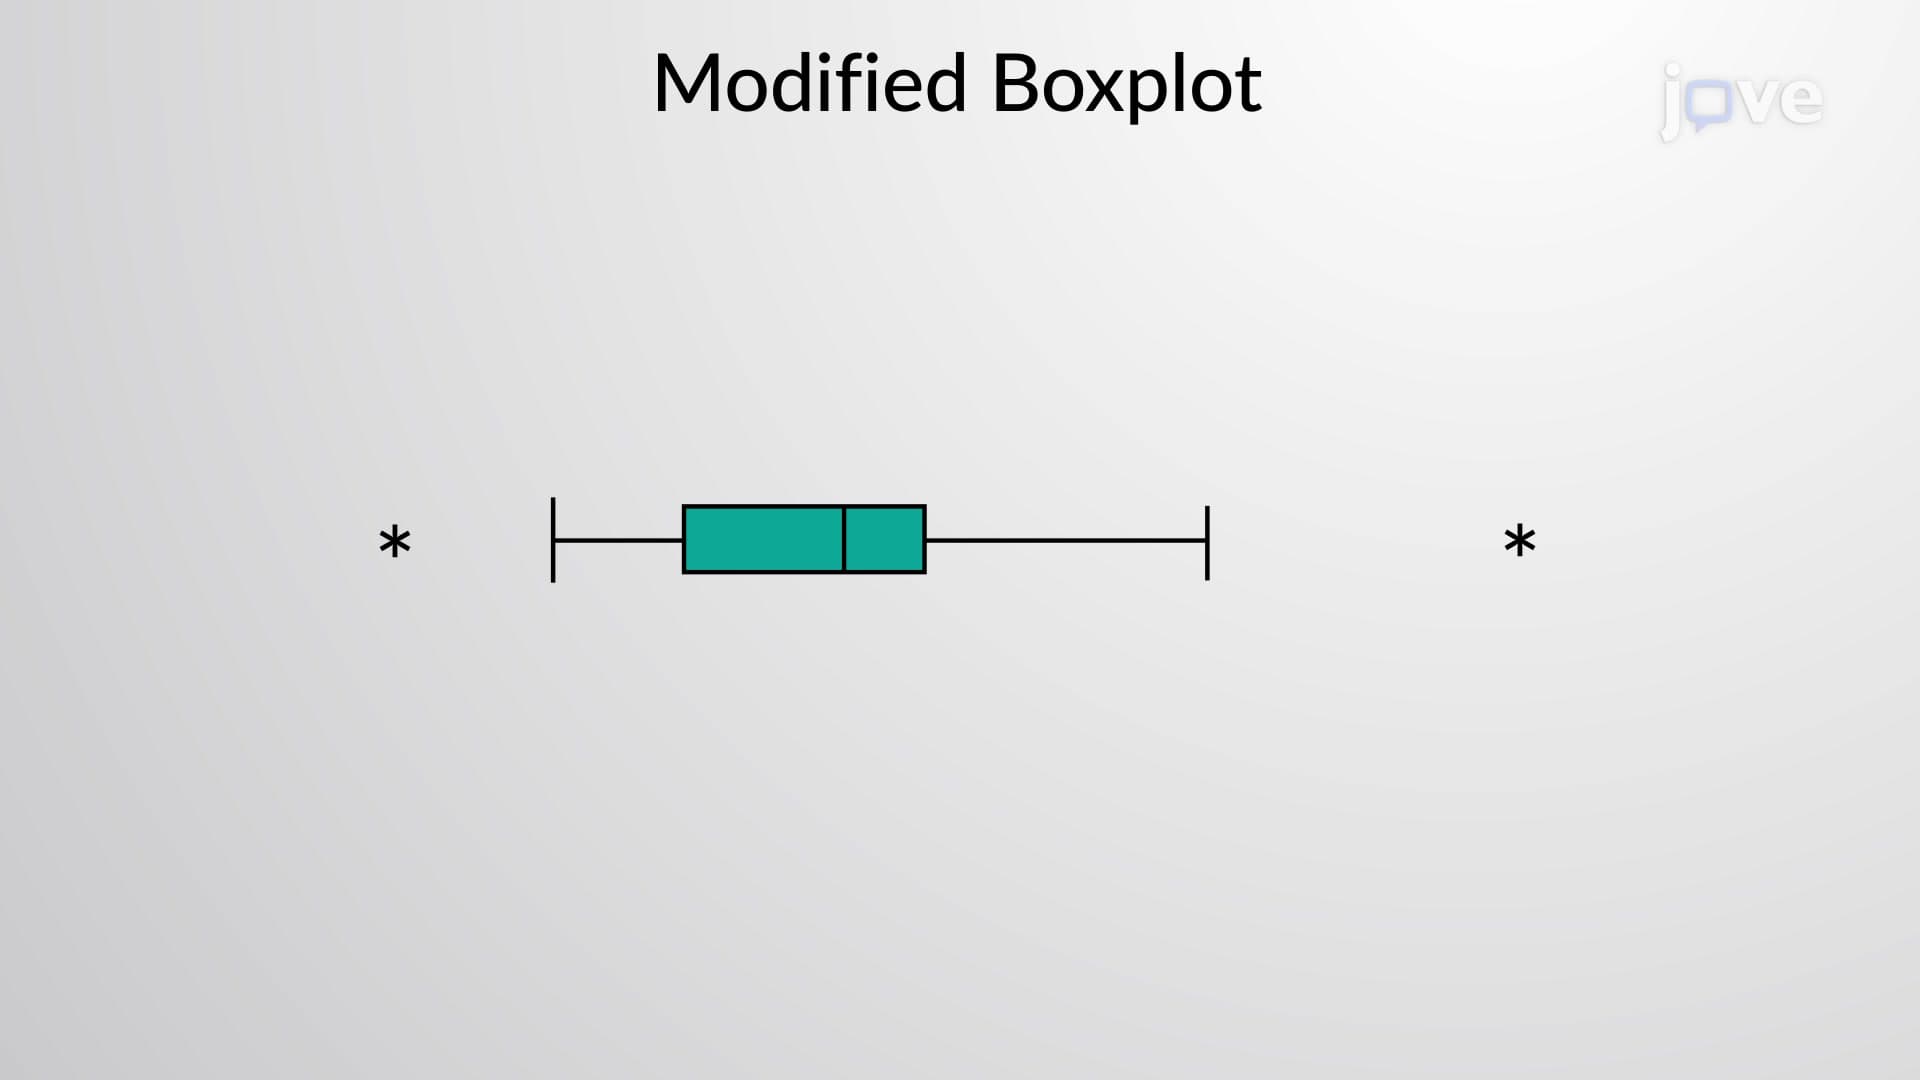
Modified Boxplots
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:12
Analysis of Population Pharmacokinetic Data
 01:14
Analysis Methods of Pharmacokinetic Data: Model and Model-Independent Approaches
The model approach uses mathematical models to describe changes in drug concentration over time. Pharmacokinetic models help characterize drug behavior in patients, predict drug concentration in the body fluids, calculate optimum dosage regimens, and evaluate the risk of toxicity. However, ensuring that the model fits the experimental data accurately...
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...