Can large language models assist with pediatric dosing accuracy?
Related Experiment Video
Updated: May 23, 2025

Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
Chedva Levin1,2, Brurya Orkaby1,3, Erika Kerner4
1Faculty of School of Life and Health Sciences, Nursing Department, The Jerusalem College of Technology-Lev Academic Center, Jerusalem, Israel.

Background And Objective:
Medication errors in pediatric care remain a significant healthcare challenge despite technological advancements, necessitating innovative approaches. This study aims to evaluate Large Language Models' (LLMs) potential in reducing pediatric medication dosage calculation errors compared to experienced nurses.
Methods:
This cross-sectional study (June-August 2024) involved 101 nurses from pediatric and neonatal departments and three LLMs (ChatGPT-4o, Claude-3.0, Llama 3 8B). Participants completed a nine-question survey on pediatric medication calculations. Primary outcomes were accuracy and response time. Secondary measures included seniority and group membership on accuracy.
Results:
Significant differences (P < 0.001) were observed between nurses and LLMs. Nurses averaged 93.14 ± 9.39 accuracy. Claude-3.0 and ChatGPT-4o achieved 100 accuracy, while Llama 3 8B was 66 accurate. LLMs were faster (15.7-75.12 seconds) than nurses (1621.2 ± 8379.3 s). The Generalized Linear Model analysis revealed task performance was significantly influenced by duration (Wald χ² = 27,881.261, p < 0.001) and interaction between relative seniority and group membership (Wald χ² = 3,938.250, p < 0.001), with participants achieving a mean total grade of 91.03 (SD = 13.87).
Conclusions:
Claude-3.0 and ChatGPT-4o demonstrated perfect accuracy and rapid calculation capabilities, showing promise in reducing pediatric medication dosage errors. Further research is needed to explore their integration into practice.
Impact:
Key Message Large Language Models (LLMs) like ChatGPT-4o and Claude-3.0 demonstrate perfect accuracy and significantly faster response times in pediatric medication dosage calculations, showing potential to reduce errors and save time. Addition to Existing Literature This study provides novel insights by quantitatively comparing LLM performance with experienced nurses, contributing to the understanding of AI's role in improving medication safety. Impact The findings emphasize the value of LLMs as supplemental tools in healthcare, particularly in high-stakes pediatric care, where they can reduce calculation errors and improve clinical efficiency.
Related Concept Videos
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:21
Factors Affecting Drug Response: Overview
 01:20
Pharmacokinetic Models: Overview
There are three primary types of models: empirical, compartment, and physiological. Empirical models, with minimal...
 01:09
One-Compartment Open Model for IV Bolus Administration: Estimation of Elimination Rate Constant, Half-Life and Volume of Distribution
 01:18
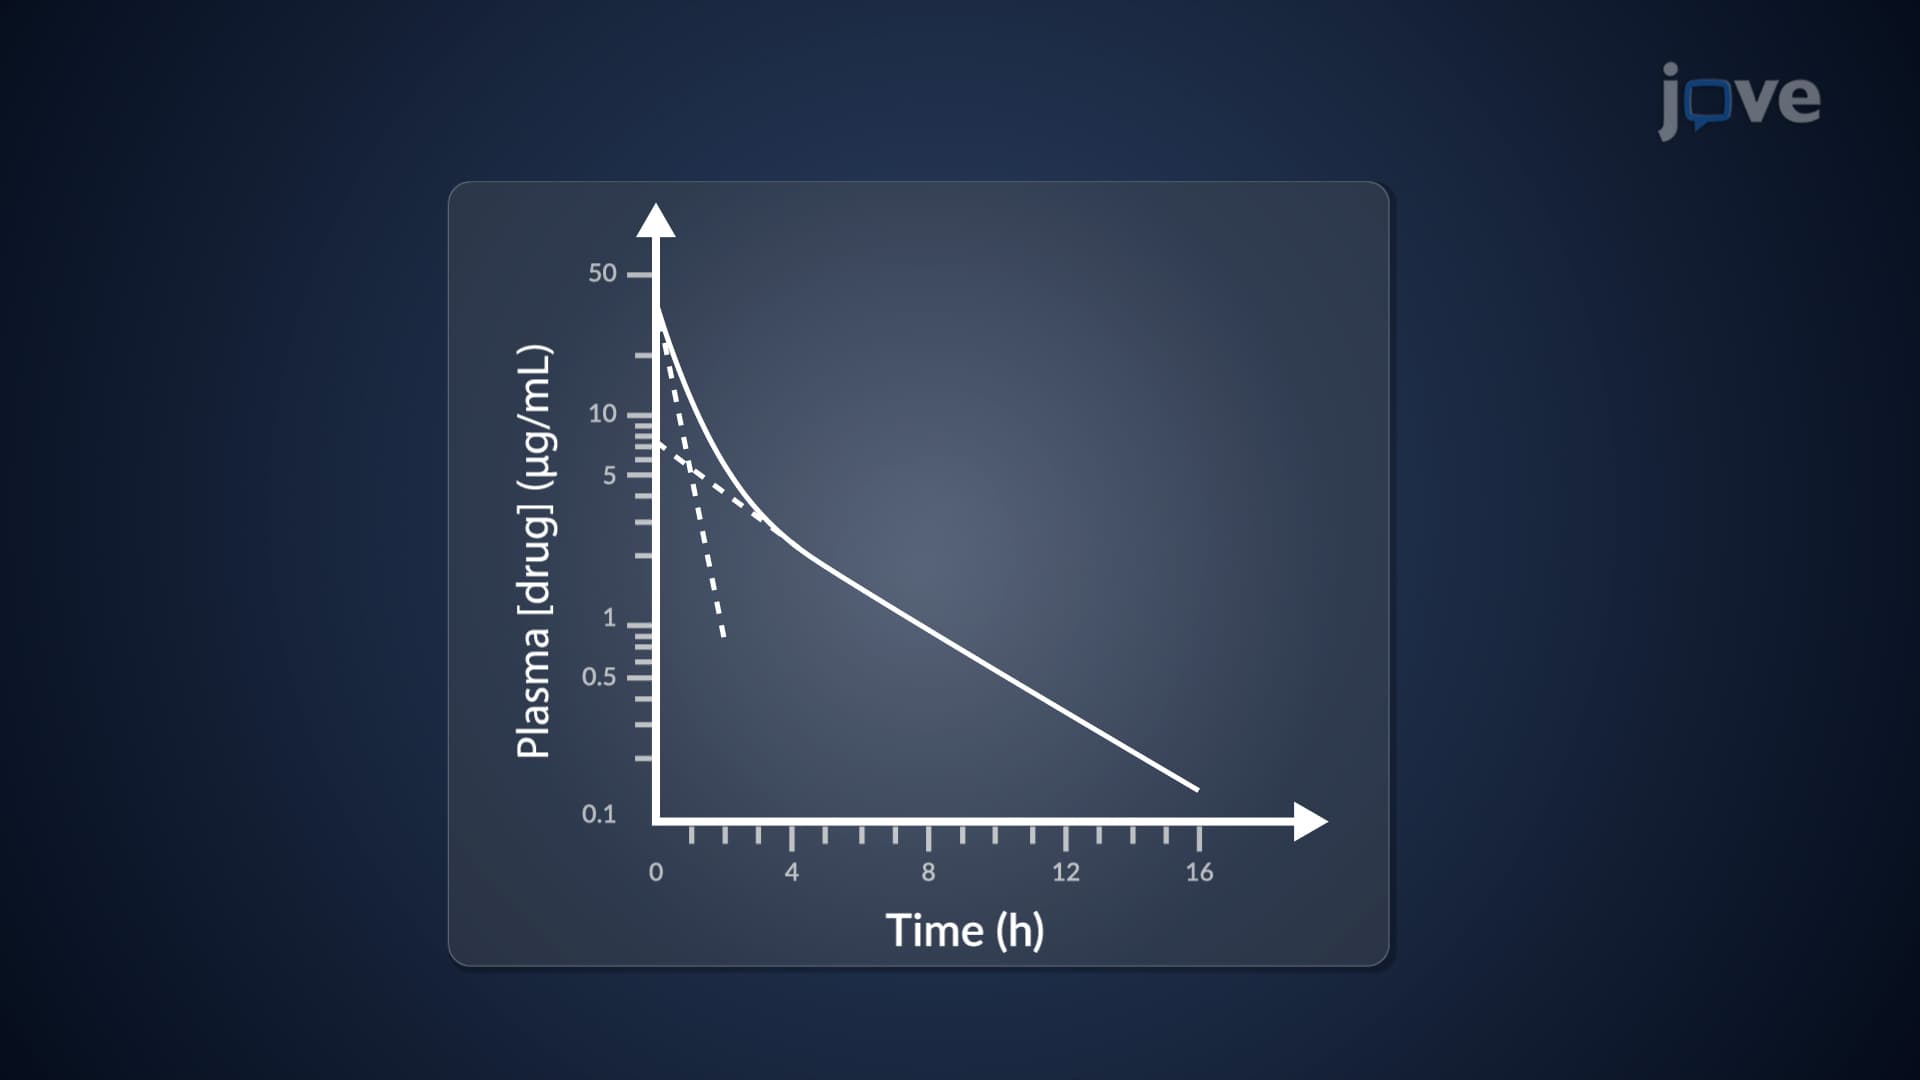
Two-Compartment Open Model: IV Bolus Administration
The disparity between drug input and the sum of drug transfer rates between...