Related Experiment Video
Updated: May 23, 2025


An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
Information-theoretic evaluation of covariate distributions models
Niklas Hartung1, Aleksandra Khatova2,3
1Institute of Mathematics, University of Potsdam, Karl-Liebknecht-Str. 24-25, 14476, Potsdam, Germany. niklas.hartung@uni-potsdam.de.

Abstract:
Statistical modelling of covariate distributions allows to generate virtual populations or to impute missing values in a covariate dataset. Covariate distributions typically have non-Gaussian margins and show nonlinear correlation structures, which simple descriptions like multivariate Gaussian distributions fail to represent. Prominent non-Gaussian frameworks for covariate distribution modelling are copula-based models and models based on multiple imputation by chained equations (MICE). While both frameworks have already found applications in the life sciences, a systematic investigation of their goodness-of-fit to the theoretical underlying distribution, indicating strengths and weaknesses under different conditions, is still lacking. To bridge this gap, we thoroughly evaluated covariate distribution models in terms of Kullback-Leibler (KL) divergence, a scale-invariant information-theoretic goodness-of-fit criterion for distributions. Methodologically, we proposed a new approach to construct confidence intervals for KL divergence by combining nearest neighbour-based KL divergence estimators with subsampling-based uncertainty quantification. In relevant data sets of different sizes and dimensionalities with both continuous and discrete covariates, non-Gaussian models showed consistent improvements in KL divergence, compared to simpler Gaussian or scale transform approximations. KL divergence estimates were also robust to the inclusion of latent variables and large fractions of missing values. While good generalization behaviour to new data could be seen in copula-based models, MICE shows a trend for overfitting and its performance should always be evaluated on separate test data. Parametric copula models and MICE were found to scale much better with the dimension of the dataset than nonparametric copula models. These findings corroborate the potential of non-Gaussian models for modelling realistic life science covariate distributions.

Related Concept Videos
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:26
Distributions to Estimate Population Parameter
 01:32
Probability Distributions
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:15
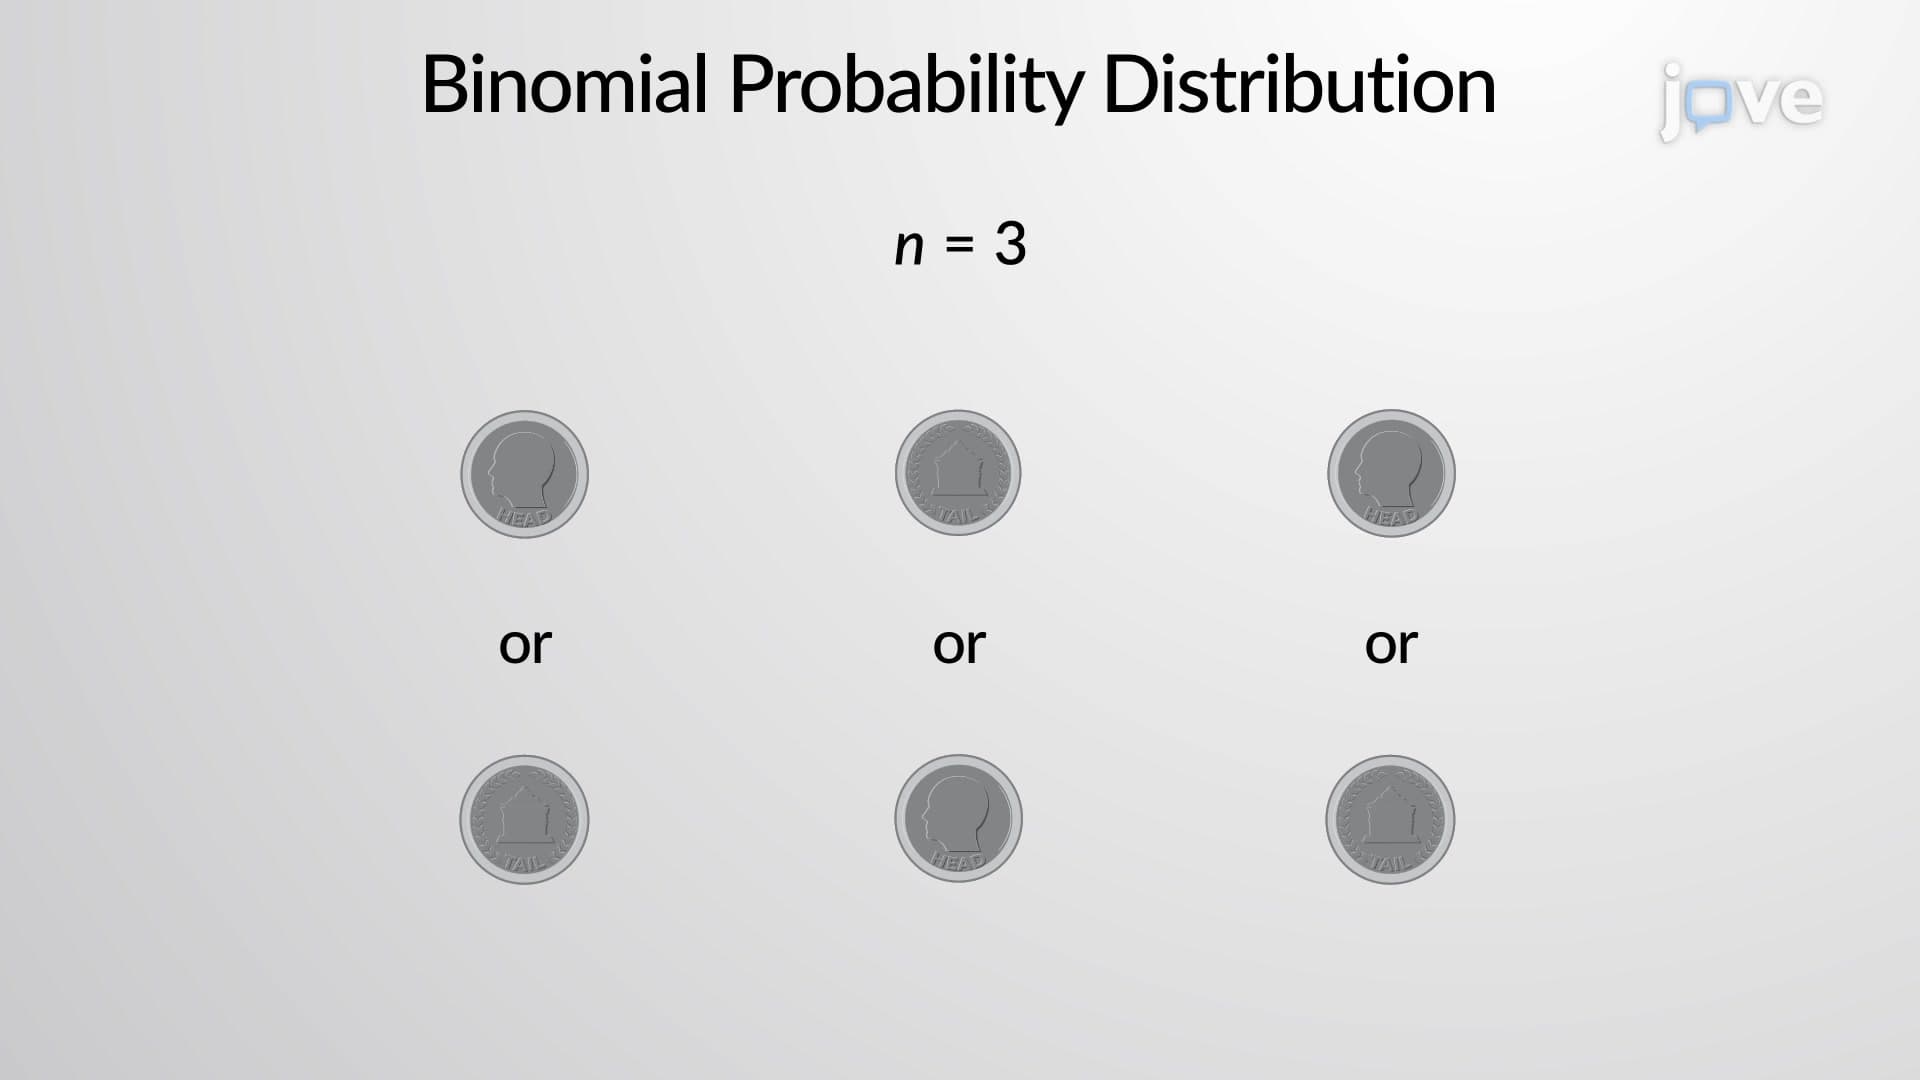
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...