Related Experiment Video
Updated: Jul 15, 2026
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Linear Recursive Feature Machines provably recover low-rank matrices
Adityanarayanan Radhakrishnan1,2, Mikhail Belkin3, Dmitriy Drusvyatskiy4
1Applied Math, Harvard University, MA 02138.

Abstract:
A fundamental problem in machine learning is to understand how neural networks make accurate predictions, while seemingly bypassing the curse of dimensionality. A possible explanation is that common training algorithms for neural networks implicitly perform dimensionality reduction-a process called feature learning. Recent work [A. Radhakrishnan, D. Beaglehole, P. Pandit, M. Belkin, Science 383, 1461-1467 (2024).] posited that the effects of feature learning can be elicited from a classical statistical estimator called the average gradient outer product (AGOP). The authors proposed Recursive Feature Machines (RFMs) as an algorithm that explicitly performs feature learning by alternating between 1) reweighting the feature vectors by the AGOP and 2) learning the prediction function in the transformed space. In this work, we develop theoretical guarantees for how RFM performs dimensionality reduction by focusing on the class of overparameterized problems arising in sparse linear regression and low-rank matrix recovery. Specifically, we show that RFM restricted to linear models (lin-RFM) reduces to a variant of the well-studied Iteratively Reweighted Least Squares (IRLS) algorithm. Furthermore, our results connect feature learning in neural networks and classical sparse recovery algorithms and shed light on how neural networks recover low rank structure from data. In addition, we provide an implementation of lin-RFM that scales to matrices with millions of missing entries. Our implementation is faster than the standard IRLS algorithms since it avoids forming singular value decompositions. It also outperforms deep linear networks for sparse linear regression and low-rank matrix completion.
Related Concept Videos
 01:15
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...
 01:19
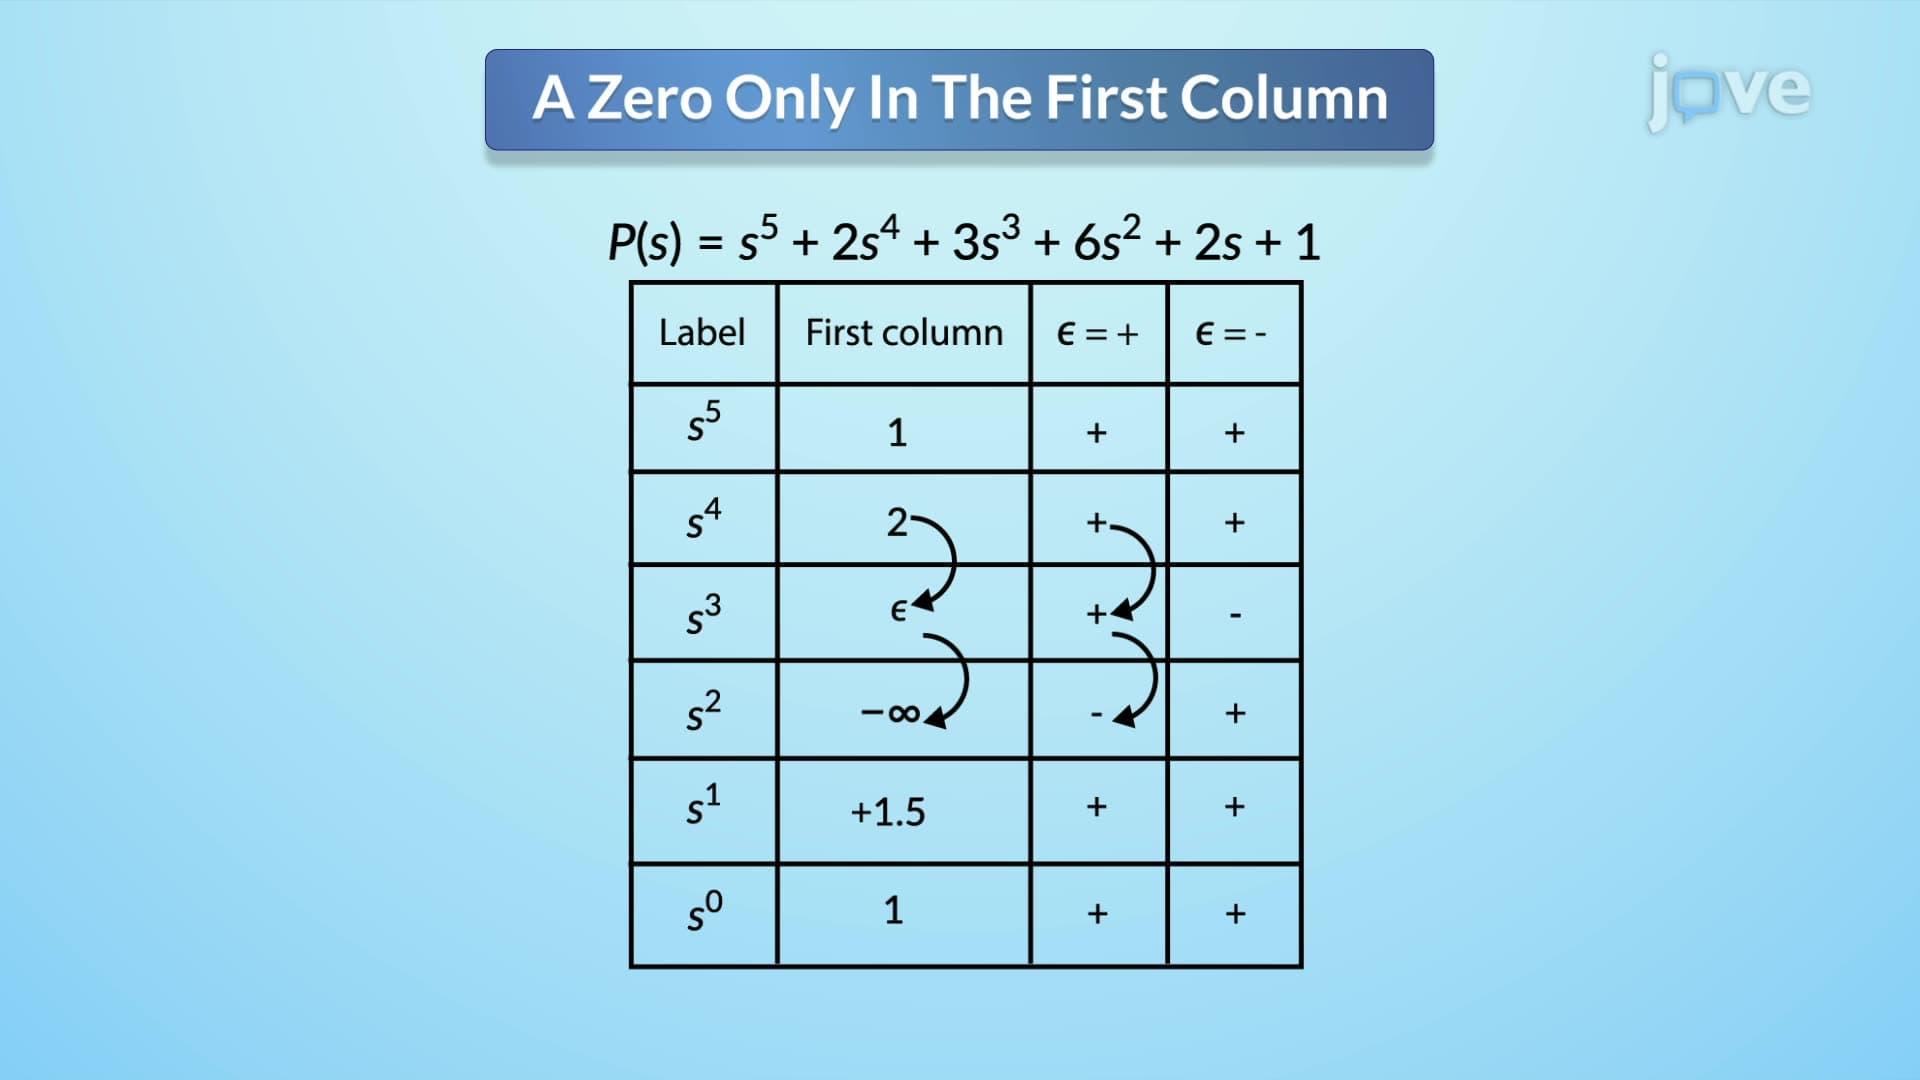
Routh-Hurwitz Criterion II
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first column of the Routh...
 01:24
Sequence Networks of Rotating Machines
Zero-sequence current induces a voltage drop across the generator's neutral impedance and other...
 01:26
Linearization and Approximation
 01:29
Application of Linearization and Approximation
 01:23
Linear Approximations