Preliminary assessment of large language models' performance in answering questions on developmental dysplasia of the hip
Related Experiment Video
Updated: May 11, 2025
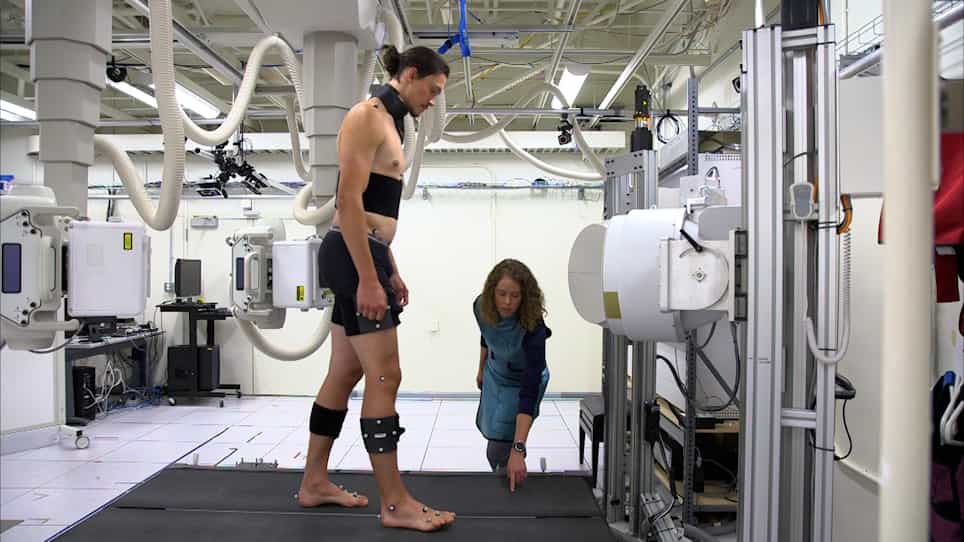
In Vivo Quantification of Hip Arthrokinematics during Dynamic Weight-bearing Activities using Dual Fluoroscopy
Published on: July 2, 2021
Shiwei Li1, Jun Jiang1, Xiaodong Yang1
1Department of Pediatric Surgery, West China Hospital, Sichuan University, Chengdu, China.

Objective:
To evaluate the performance of three large language models in answering questions regarding pediatric developmental dysplasia of the hip.
Methods:
We formulated 18 open-ended clinical questions in both Chinese and English and established a gold standard set of answers to benchmark the responses of the large language models. These questions were presented to ChatGPT-4o, Gemini, and Claude 3.5 Sonnet. The responses were evaluated by two independent reviewers using a 5-point scale. The average score, rounded to the nearest whole number, was taken as the final score. A final score of 4 or 5 indicated an accurate response, whereas a final score of 1, 2, or 3 indicated an inaccurate response.
Results:
The raters demonstrated a high level of agreement in scoring the answers, with weighted Kappa coefficients of 0.865 for Chinese responses (p < 0.001) and 0.875 for English responses (p < 0.001). No significant differences were observed among the three large language models in terms of accuracy when answering questions, with rates of 83.3%, 77.8%, and 77.8% for Claude 3.5 Sonnet, ChatGPT-4o, and Gemini in the Chinese responses (p = 1), and 83.3%, 83.3%, and 72.2% for ChatGPT-4o, Claude 3.5 Sonnet, and Gemini in the English responses (p = 0.761). In addition, there was no significant difference in the performance of the same large language model between the Chinese and English settings.
Conclusions:
Large language models demonstrate high accuracy in delivering information on dysplasia of the hip, maintaining consistent performance across both Chinese and English, which suggests their potential utility as medical support tools.
Level Of Evidence:
Level II.
More Related Videos
 10:11
Portable Intermodal Preferential Looking IPL: Investigating Language Comprehension in Typically Developing Toddlers and Young Children with Autism
Published on: December 14, 2012
 03:14
Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
