A Two-Stage Selective Experience Replay for Double-Actor Deep Reinforcement Learning
Related Experiment Video
Updated: May 10, 2025
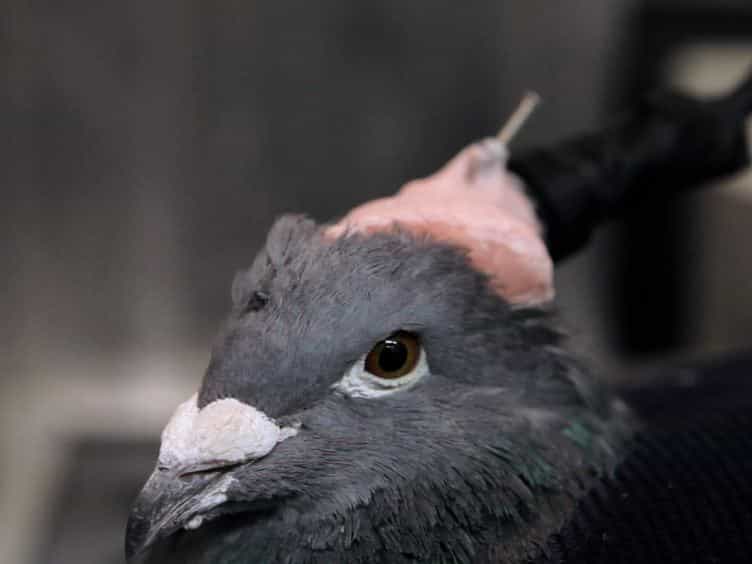
Recording Single Neurons' Action Potentials from Freely Moving Pigeons Across Three Stages of Learning
Published on: June 2, 2014

Abstract:
Deep reinforcement learning (DRL) has been widely applied to various applications, but improving the exploration and the accuracy of Q-value estimation remain key challenges. Recently, the double-actor architecture has emerged as a promising DRL framework that can enhance both exploration and Q-value estimation. Existing double-actor DRL methods sample from the replay buffer to update the two actors; however, the samples used to update each actor are generated by its previous versions and the other actor, resulting in a different data distribution compared with the current actor being updated, which can negatively impact the actor's update and lead to suboptimal policies. To this end, this work proposes a generic solution that can be seamlessly integrated into existing double-actor DRL methods to mitigate the adverse effects of data distribution differences on actor updates, thereby learning better policies. Specifically, we decompose the updates of double-actor DRL methods into two stages, each of which uses the same sampling approach to train a pair of actor-critic. This sampling approach classifies the samples in the replay buffer into distinct categories using a clustering technique, such as K-means, and subsequently employs the Jensen-Shannon (JS) divergence to evaluate the distributional differences between each sample category and the actor currently being updated. Samples are then prioritized from the categories with smaller distribution differences to the current actor to update it. In this way, we can effectively mitigate the distribution difference between the samples and the current actor being updated. Experiments demonstrate that our method enhances the performance of five state-of-the-art (SOTA) double-actor DRL methods and outperforms eight SOTA single-actor DRL methods across eight tasks.
Related Concept Videos
 01:07
Elaborative Rehearsals
The effectiveness of...
 01:22
Chunking and Rehearsal in Sensory Memory
 01:35
Long-term Potentiation