Related Experiment Video
Updated: May 10, 2025
Visualization Method for Proprioceptive Drift on a 2D Plane Using Support Vector Machine
Published on: October 27, 2016
Unsupervised Domain Adaptation Method Based on Relative Entropy Regularization and Measure Propagation
Lianghao Tan1, Zhuo Peng1, Yongjia Song2
1Department of Computer Science, Arizona State University, Tempe, AZ 85281, USA.

Abstract:
This paper presents a novel unsupervised domain adaptation (UDA) framework that integrates information-theoretic principles to mitigate distributional discrepancies between source and target domains. The proposed method incorporates two key components: (1) relative entropy regularization, which leverages Kullback-Leibler (KL) divergence to align the predicted label distribution of the target domain with a reference distribution derived from the source domain, thereby reducing prediction uncertainty; and (2) measure propagation, a technique that transfers probability mass from the source domain to generate pseudo-measures-estimated probabilistic representations-for the unlabeled target domain. This dual mechanism enhances both global feature alignment and semantic consistency across domains. Extensive experiments on benchmark datasets (OfficeHome and DomainNet) demonstrate that the proposed approach consistently outperforms State-of-the-Art methods, particularly in scenarios with significant domain shifts. These results confirm the robustness, scalability, and theoretical grounding of our framework, offering a new perspective on the fusion of information theory and domain adaptation.

Related Concept Videos
 00:59
Propagation of Uncertainty from Random Error
 01:10
Propagation of Uncertainty from Systematic Error
 01:19
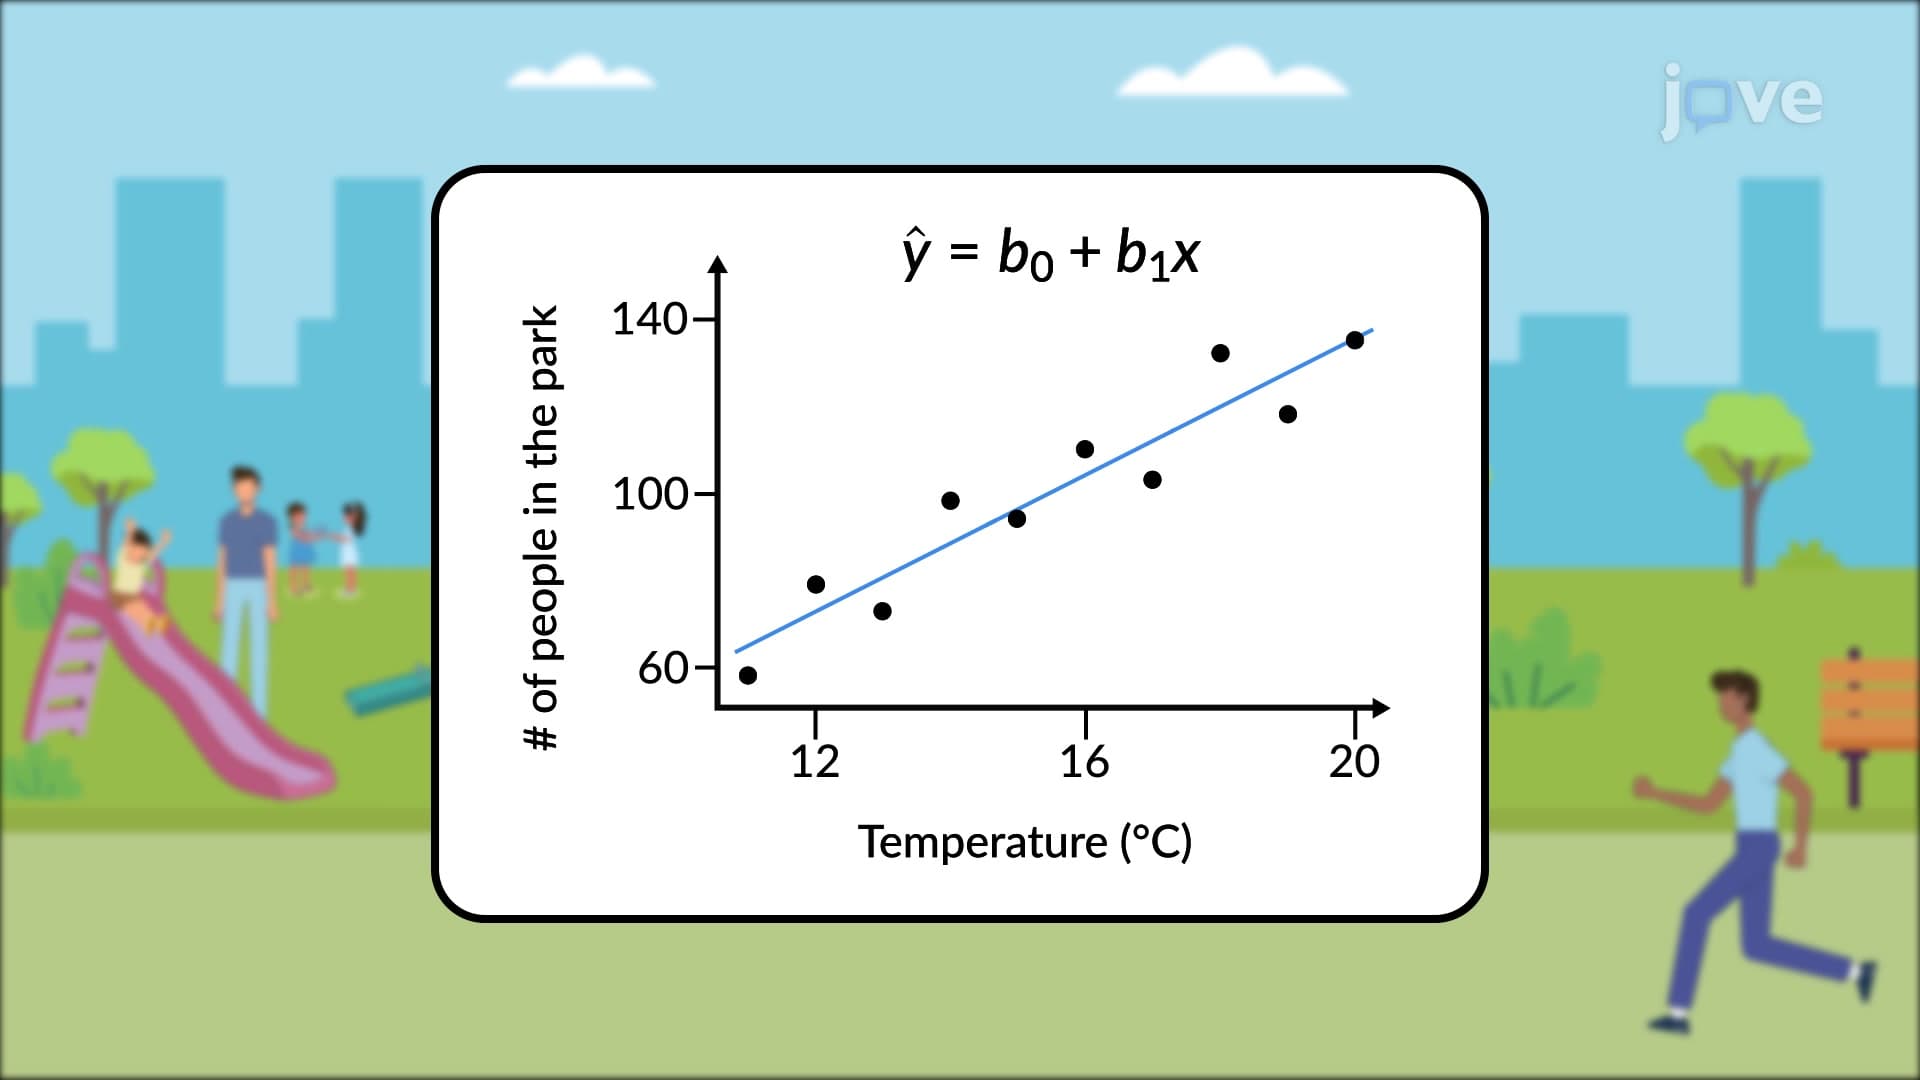
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:13
Mean Absolute Deviation
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 00:55
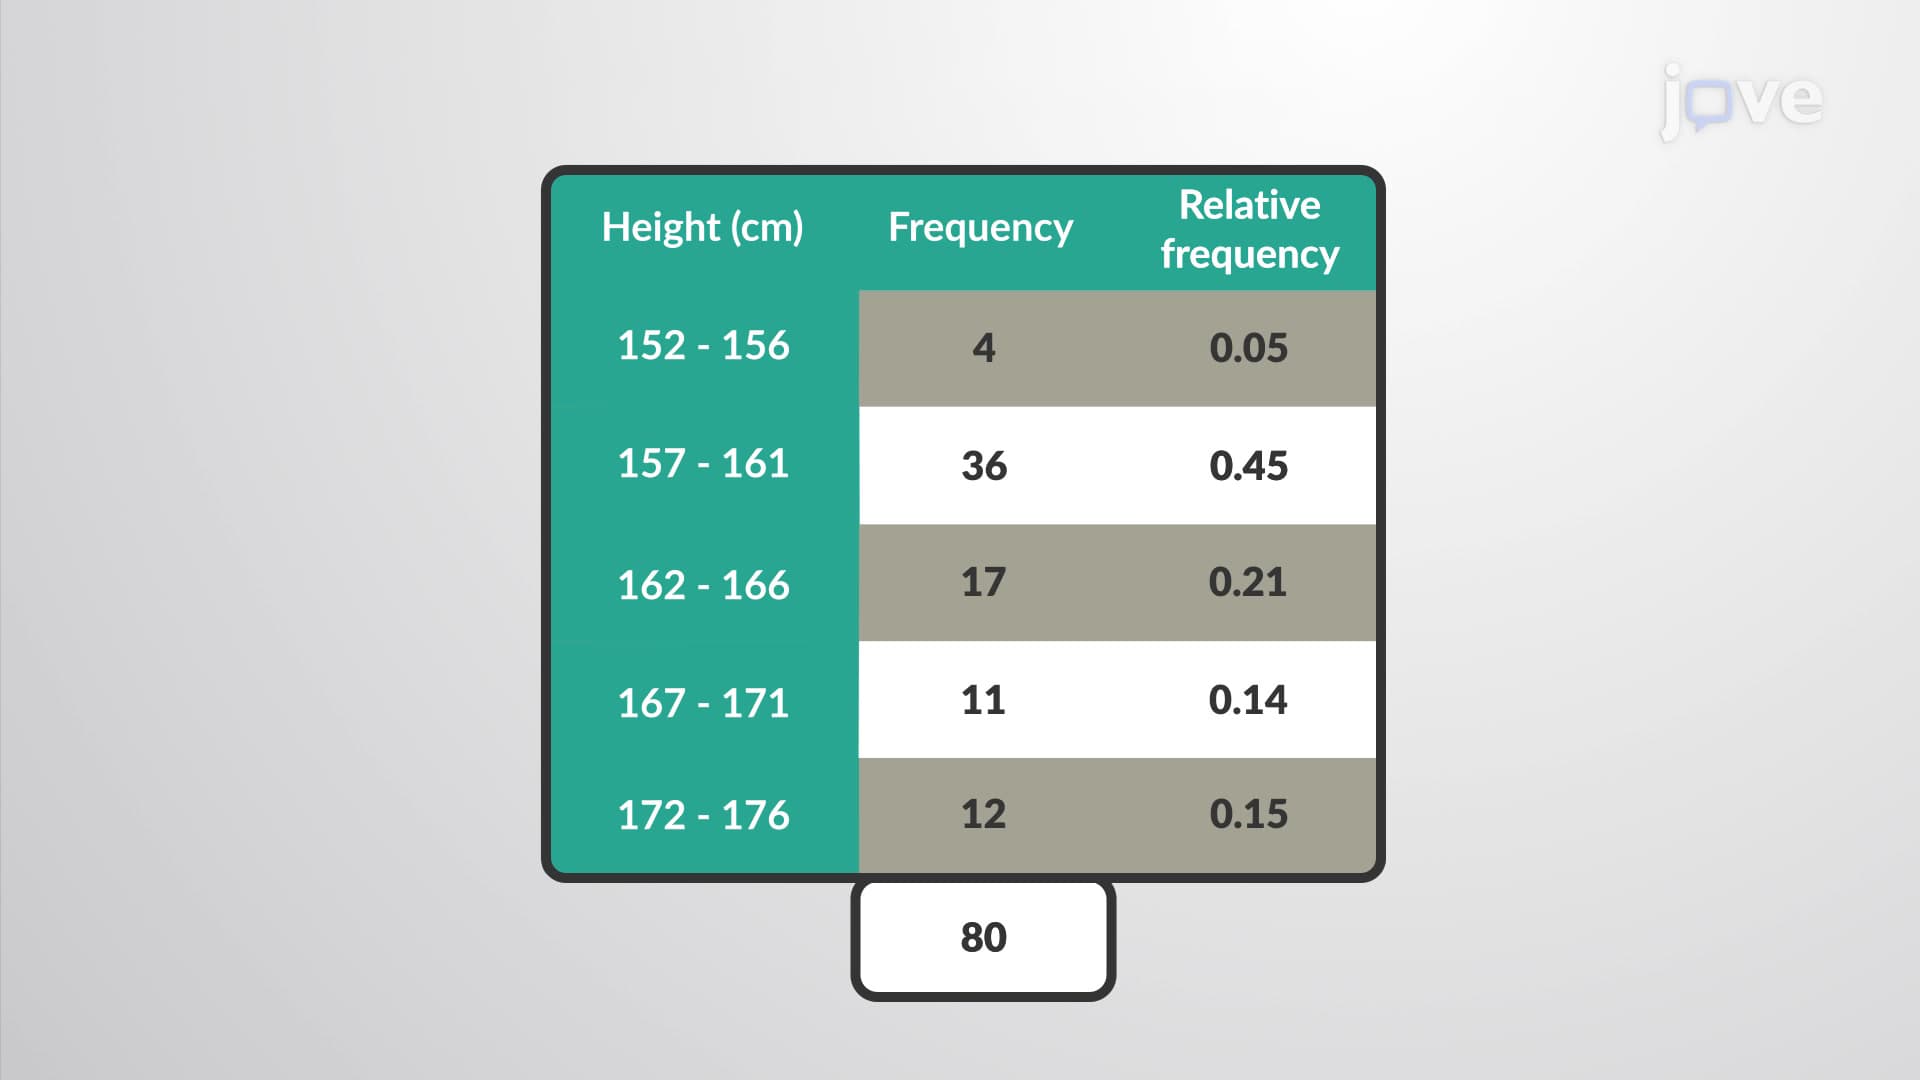
Relative Frequency Distribution