Related Experiment Video
Updated: May 13, 2025

Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Interpretable inverse iteration mean shift networks for clustering tasks
Bingjie Zhang1, Zihan Yu2, Jian Wang3
1School of Mathematics and Statistics, Weifang University, Weifang, 261061, China.

Abstract:
Neural networks have become the standard approach for tasks such as computer vision, machine translation and pattern recognition. While they exhibit significant feature representation capabilities, they often lack interpretability. This suggests that it might be beneficial to explore interpretable machine learning approaches in order to inform the neural network architectures. On the contrary, the mean shift algorithm (MS) has an unambiguous computational process, yet lacking in representation power. In order to draw on the advantages of both neural networks and the mean shift method, we propose the mean shift network (MS-Net) - a novel architecture, which is an inverse iteration fuzzy clustering network. Each layer of the proposed network possesses good interpretability, while the network as a whole is able to produce strong feature representations. To relax the limitations of the kernel function and ensure convergence, we design a continuously-differentiable Gaussian-inspired kernel as the activation function for the membership layer of MS-Net. Furthermore, we devise a weighted version of the architecture, called WMS-Net, to incorporate the importance of the training examples. We present theoretical results, with proofs of weak and strong convergence. We also consider two extensions to the proposed method, CB-MS-Net and CB-WMS-Net, which apply the curvature-based method to MS-Net and WMS-Net. Simulation results on 5 clustering tasks and 6 real-world datasets confirm the effectiveness of the proposed algorithms.
Related Concept Videos
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:11
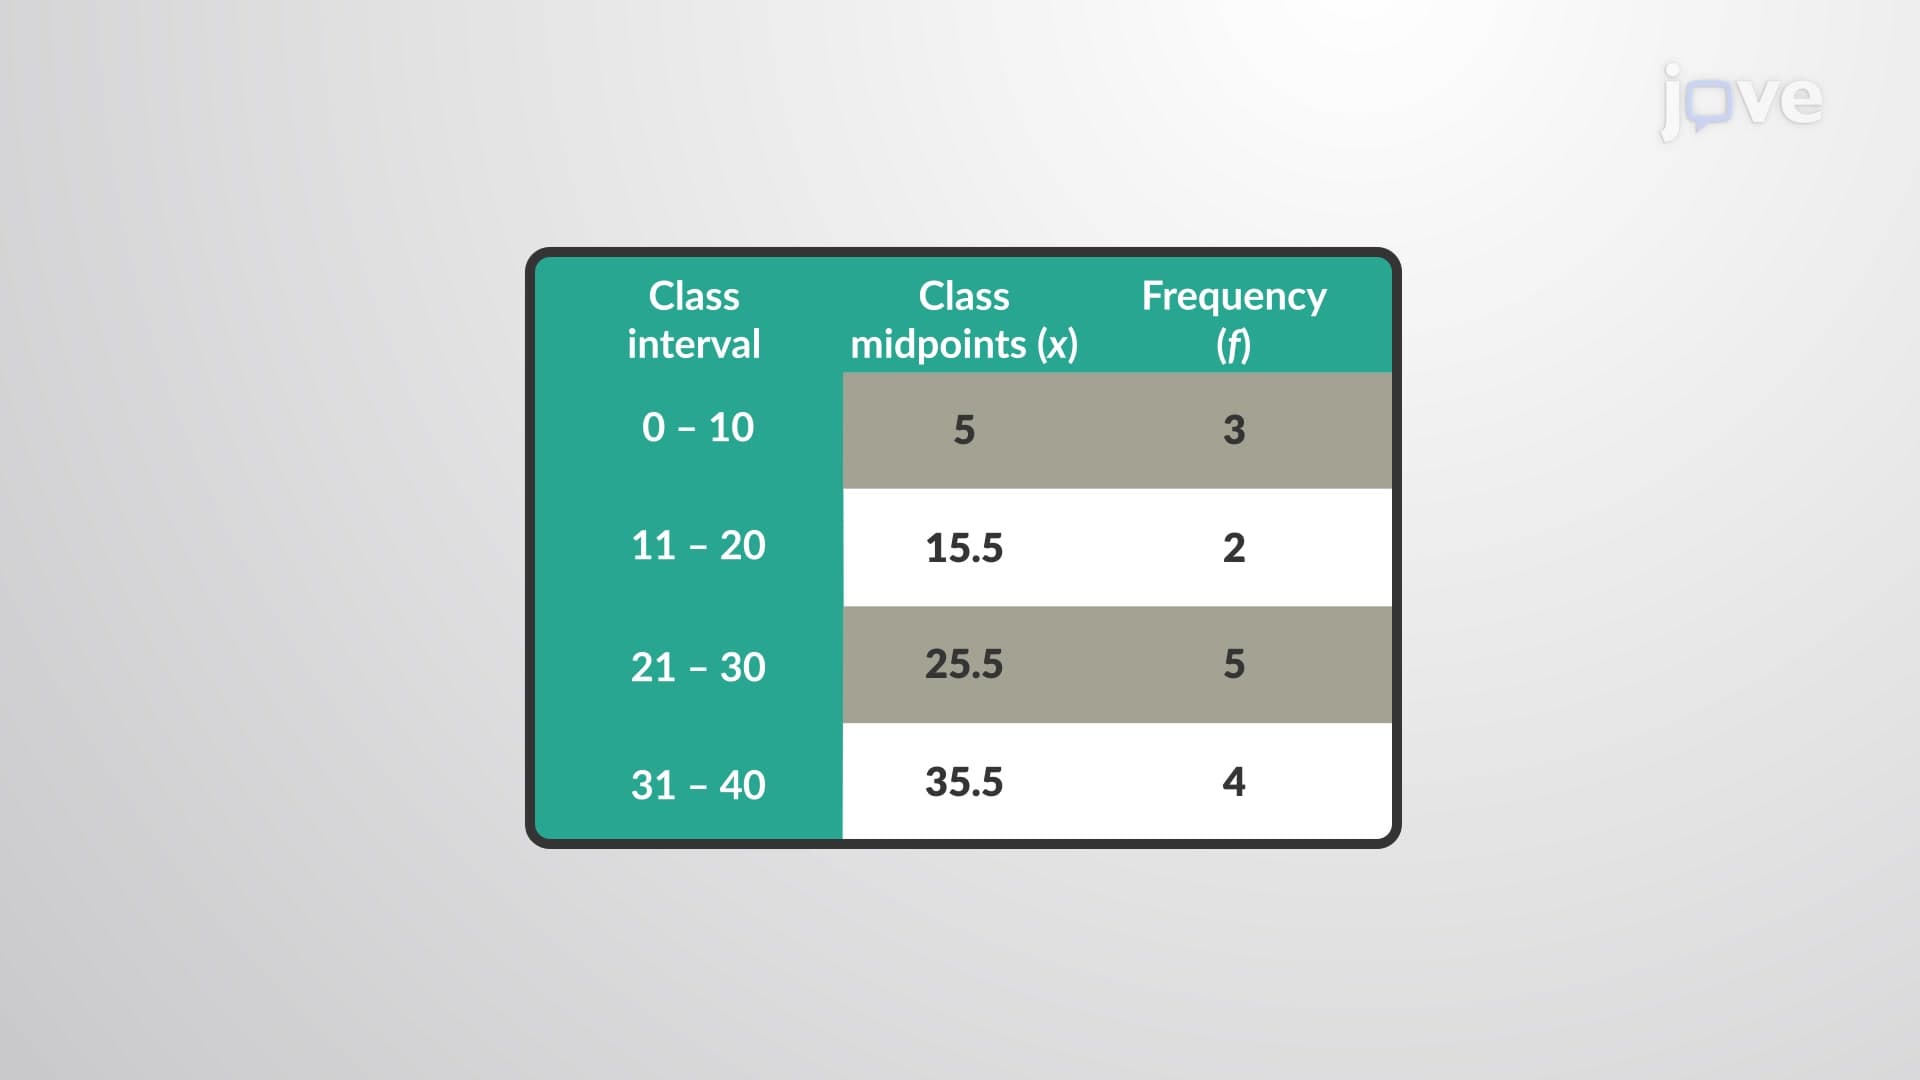
Mean From a Frequency Distribution
When such a data set is encountered,...
 01:52
Regression Toward the Mean
 01:06
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:10
Trimmed Mean
Although certain measures of central tendency are not sensitive to outliers, there are alternative versions of the mean that get around the...