Bridging the gap between R and Python in bulk transcriptomic data analysis with InMoose
Related Experiment Video
Updated: Aug 6, 2026
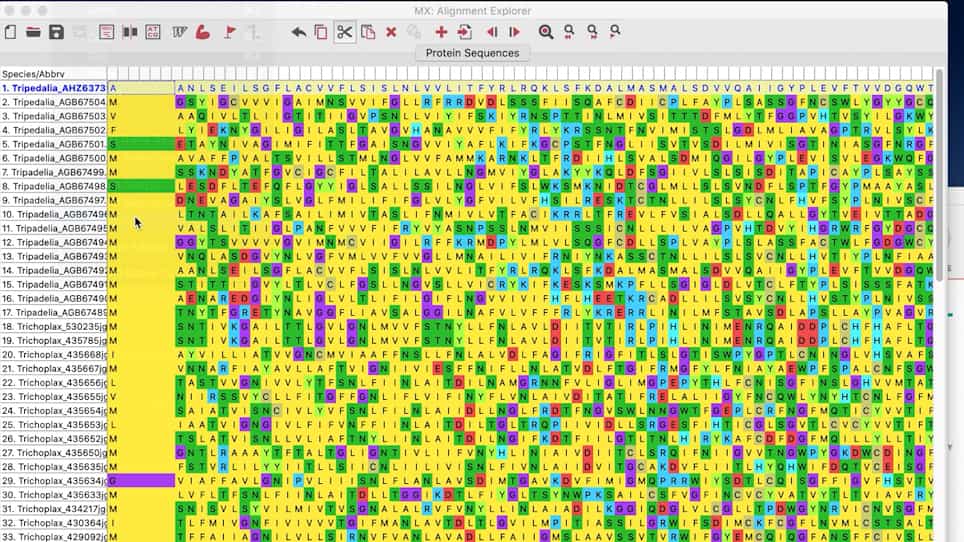
A Bioinformatics Pipeline for Investigating Molecular Evolution and Gene Expression using RNA-seq
Published on: May 28, 2021
Maximilien Colange1, Guillaume Appé2, Léa Meunier2
1Epigene Labs, Paris, France. maximilien@epigenelabs.com.

Abstract:
We introduce InMoose, an open-source Python environment aimed at omic data analysis. We illustrate its capabilities for bulk transcriptomic data analysis. Due to its wide adoption, Python has grown as a de facto standard in fields increasingly important for bioinformatic pipelines, such as data science, machine learning, or artificial intelligence (AI). As a general-purpose language, Python is also recognized for its versatility and scalability. InMoose aims at bringing state-of-the-art tools, historically written in R, to the Python ecosystem. InMoose focuses on providing drop-in replacements for R tools, to ensure consistency and reproducibility between R-based and Python-based pipelines. The first development phase has focused on bulk transcriptomic data, with current capabilities encompassing data simulation, batch effect correction, and differential analysis and meta-analysis.
Related Concept Videos
 02:24
Ribosome Profiling
Applications of ribosome profiling
Ribosome profiling has many applications, including in vivo monitoring of translation inside a particular organ or tissue type and quantifying new protein synthesis levels.
The technique helps...
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while microarray-based...
 02:07
Improving Translational Accuracy
 02:22
Regulated mRNA Transport
 02:18
Alternative RNA Splicing
There are five types of alternative RNA splicing that vary in the ways the pre-mRNA segments are removed or retained in the mature mRNA. The first...
 02:36
RNA Polymerase II Accessory Proteins