Related Experiment Video
Updated: Sep 25, 2026
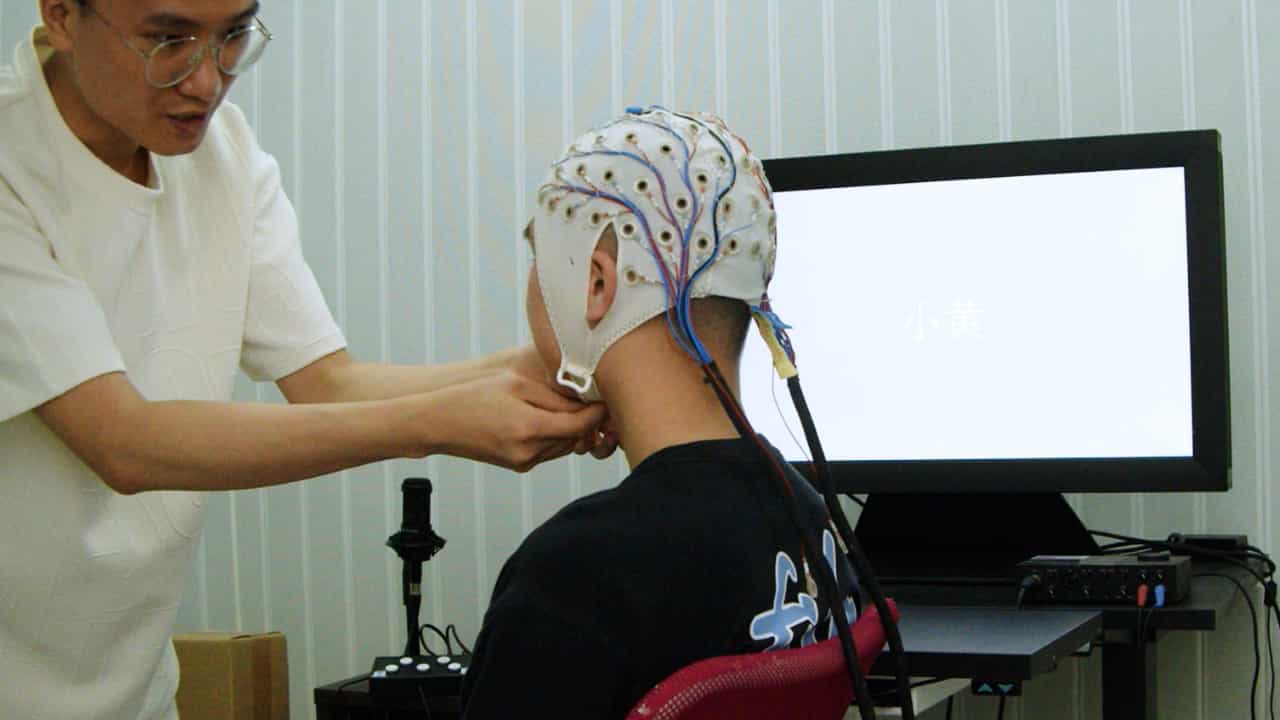

Memorization-Based Training and Testing Paradigm for Robust Vocal Identity Recognition in Expressive Speech Using Event-Related Potentials Analysis
Published on: August 9, 2024
ANALYSIS OF SELF-SUPERVISED SPEECH MODELS ON CHILDREN'S SPEECH AND INFANT VOCALIZATIONS
Jialu Li1,2, Mark Hasegawa-Johnson1,2, Nancy L McElwain2,3
1Department of Electrical and Computer Engineering, University of Illinois.

Abstract:
To understand why self-supervised learning (SSL) models have empirically achieved strong performances on several speech-processing downstream tasks, numerous studies have focused on analyzing the encoded information of the SSL layer representations in adult speech. Limited work has investigated how pre-training and fine-tuning affect SSL models encoding children's speech and vocalizations. In this study, we aim to bridge this gap by probing SSL models on two relevant downstream tasks: (1) phoneme recognition (PR) on the speech of adults, older children (8-10 years old), and younger children (1-4 years old), and (2) vocalization classification (VC) distinguishing cry, fuss, and babble for infants under 14 months old. For younger children's PR, the superiority of fine-tuned SSL models is largely due to their ability to learn features that represent older children's speech and then adapt those features to the speech of younger children. For infant VC, SSL models pre-trained on large-scale home recordings learn to leverage phonetic representations at middle layers, and thereby enhance the performance of this task.
Related Concept Videos
 01:22
Language Development
The critical period for language acquisition suggests that the ability to acquire language is at its peak early in life. As people age, this proficiency decreases. Language development begins very...
 01:12
Observational Learning