Optimizing imputation strategies for mass spectrometry-based proteomics considering intensity and missing value rates
Related Experiment Video
Updated: Sep 25, 2026
Navigating the Mass Spectrometry-Based Proteomic Data Using Free Computational Tools
Published on: August 19, 2025
Yuming Shi1, Huan Zhong1, Jason C Rogalski1
1Department of Biochemistry and Molecular Biology, Michael Smith Laboratories, Life Sciences Institute, University of British Columbia, Vancouver, BC, V6T 1Z4 Canada.

Abstract:
Missing values (MVs) in omic datasets affect the power, accuracy, and consistency of statistical and functional analyses. In mass spectrometry (MS)-based proteomics, MVs can arise due to several reasons: peptides could be below instrumental detection limits, peptides or proteins might be absent or depleted from the sample for biological or technical reasons, or data processing could fail to detect a real signal. Several statistical and machine-learning methods have been described for imputing MVs in proteomics, such as Bayesian PCA estimation, random forest, and collaborative filtering. However, these approaches typically do not account for the underlying causes of MVs and treat all missing data uniformly, potentially introducing biases that affect the biological validity of the conclusions drawn from the imputed datasets. We found a strong negative correlation between the proportion of MVs and the average intensity for the individual protein, with more abundant proteins having fewer, but rarely zero, MVs. We divided the peptides from all proteins into nine bins based on their intensities and proportion of MV. Assuming the causes of MVs could be different in different regions, we then investigated the optimal imputation method in each bin, using normalized root mean square error (NRMSE), and found that the optimal imputation method varies across bins. A mix-imputed dataset was assembled using the optimal imputation method from each bin, and it was confirmed to exhibit low deviation from the original unimputed dataset, demonstrating mixing the optimal imputation method from each bin is a reliable strategy.
Related Concept Videos
 01:19
Mass Spectrometry: Overview
 01:33
Peptide Identification Using Tandem Mass Spectrometry
This technique helps gather information regarding the protein from which the peptide was obtained and to study the peptides’ amino acid sequence. Identifying peptides from a complex mixture is an important component of the growing field of...
 01:21
Tandem Mass Spectrometry
 01:15
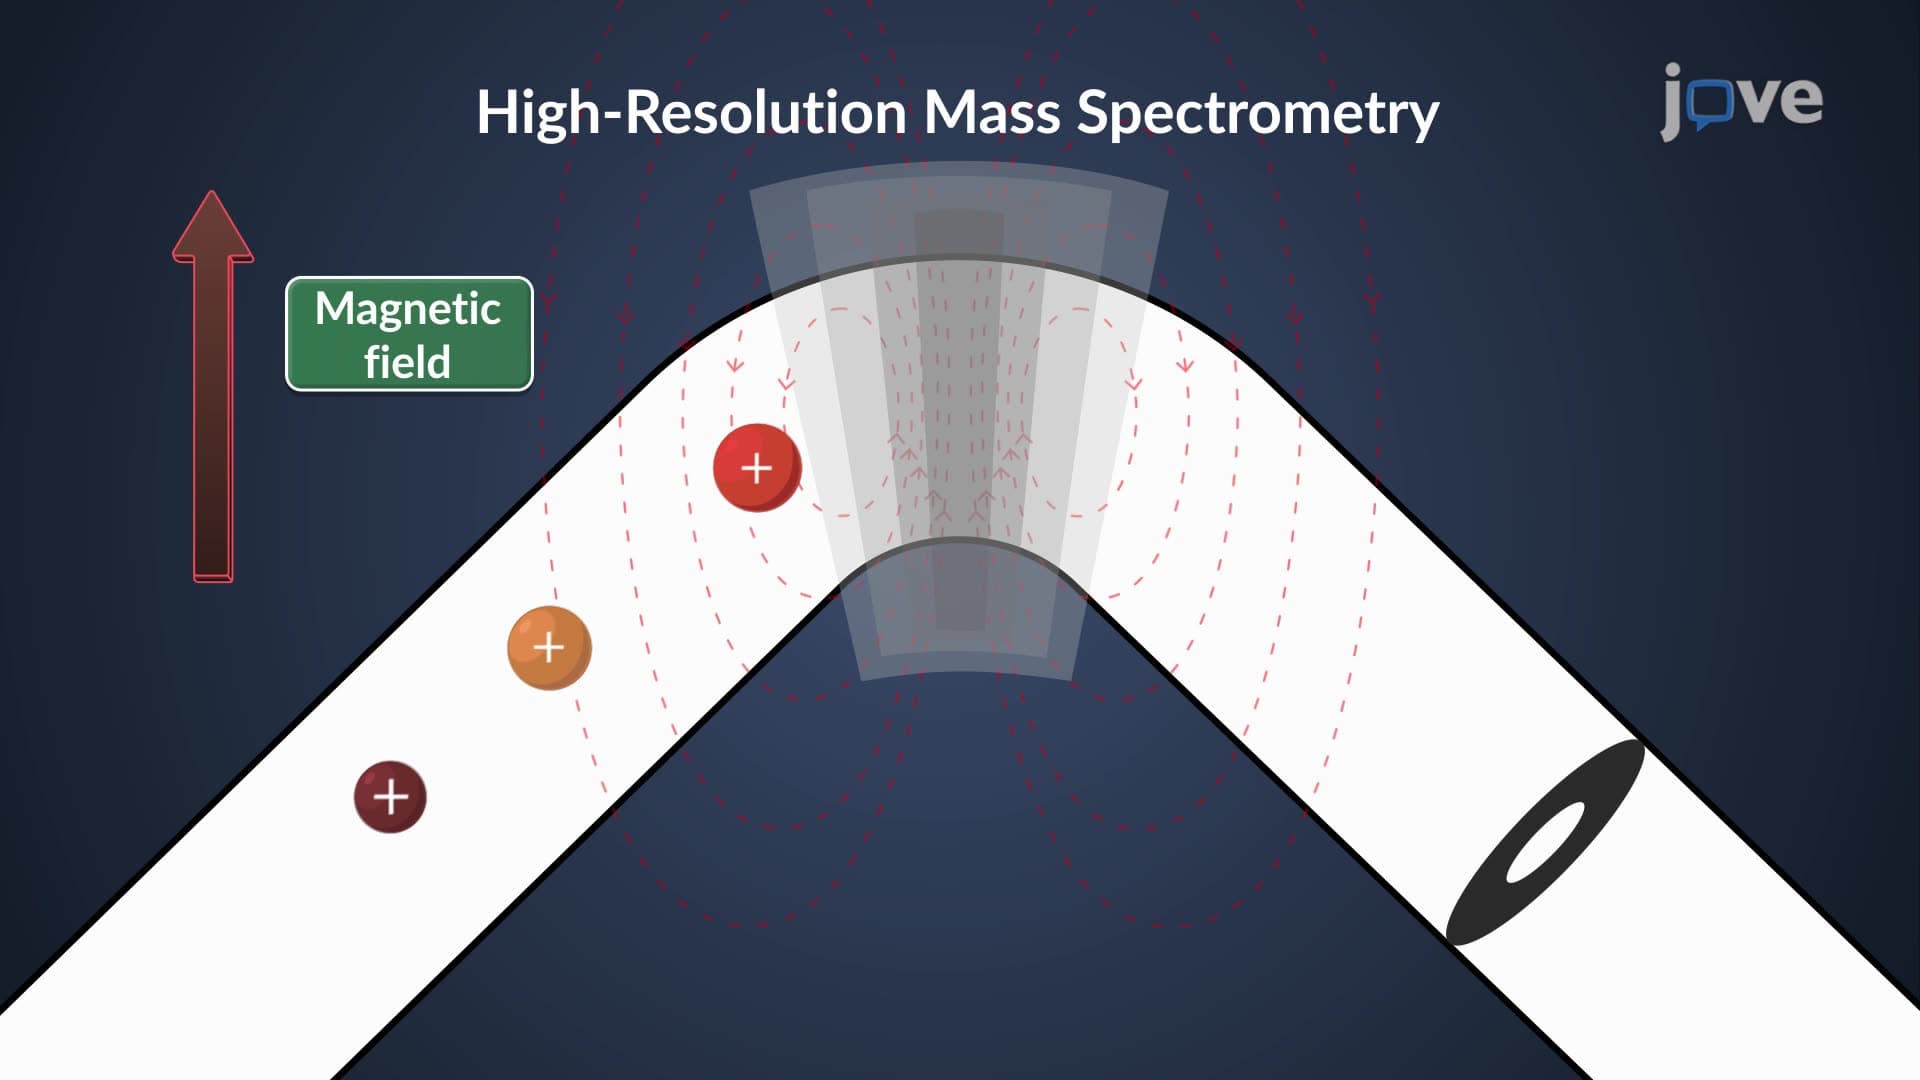
High-Resolution Mass Spectrometry (HRMS)
 01:19
MALDI-TOF Mass Spectrometry
 01:13
Mass Analyzers: Overview