A Dynamics Theory of RMSProp-Based Implicit Regularization in Deep Low-Rank Matrix Factorization


Abstract:
Implicit regularization induced by gradient optimization is an important way to understand generalization in neural networks. Recent theory explains implicit regularization over the deep matrix factorization (DMF) model and analyzes the trajectory of discrete gradient dynamics in the optimization process. These discrete gradient dynamics can mathematically characterize the practical learning rate of adaptive gradient (AdaGrad) optimization, such as root-mean-square propagation (RMSProp). Discrete gradient dynamics analysis has been successfully applied to shallow networks but encounters difficulty in complex computation for deep networks. In this work, we introduce another discrete gradient dynamics, landscape analysis, to theoretically and experimentally explain the implicit regularization of RMSProp-based deep networks. It mainly focuses on gradient regions like saddle points and local minima. We investigate the benefits of increasing learning rates in saddle point escaping (SPE) stages. We prove that, for a rank-R matrix reconstruction, DMF will converge to a second-order critical point after R stages of SPE. Besides, we analyze the time it takes to escape from the plateau of the SPE stage. These conclusions are further experimentally verified on low-rank matrix, image reconstruction, and Hankel matrix reconstruction problems. Our proof is also applicable to gradient descent (GD) and adaptive moment estimation (Adam) but cannot apply to AdaGrad, further showing experimentally that the implicit regularization capability of RMSProp is stronger than GD and AdaGrad and weaker than Adam.
More Related Videos
 11:11
Longitudinal Measurement of Extracellular Matrix Rigidity in 3D Tumor Models Using Particle-tracking Microrheology
Published on: June 10, 2014
 10:44
Inherent Dynamics Visualizer, an Interactive Application for Evaluating and Visualizing Outputs from a Gene Regulatory Network Inference Pipeline
Published on: December 7, 2021
Related Concept Videos
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:15
Relation between Poisson's ratio, Modulus of Elasticity and Modulus of Rigidity
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:19
Routh-Hurwitz Criterion II
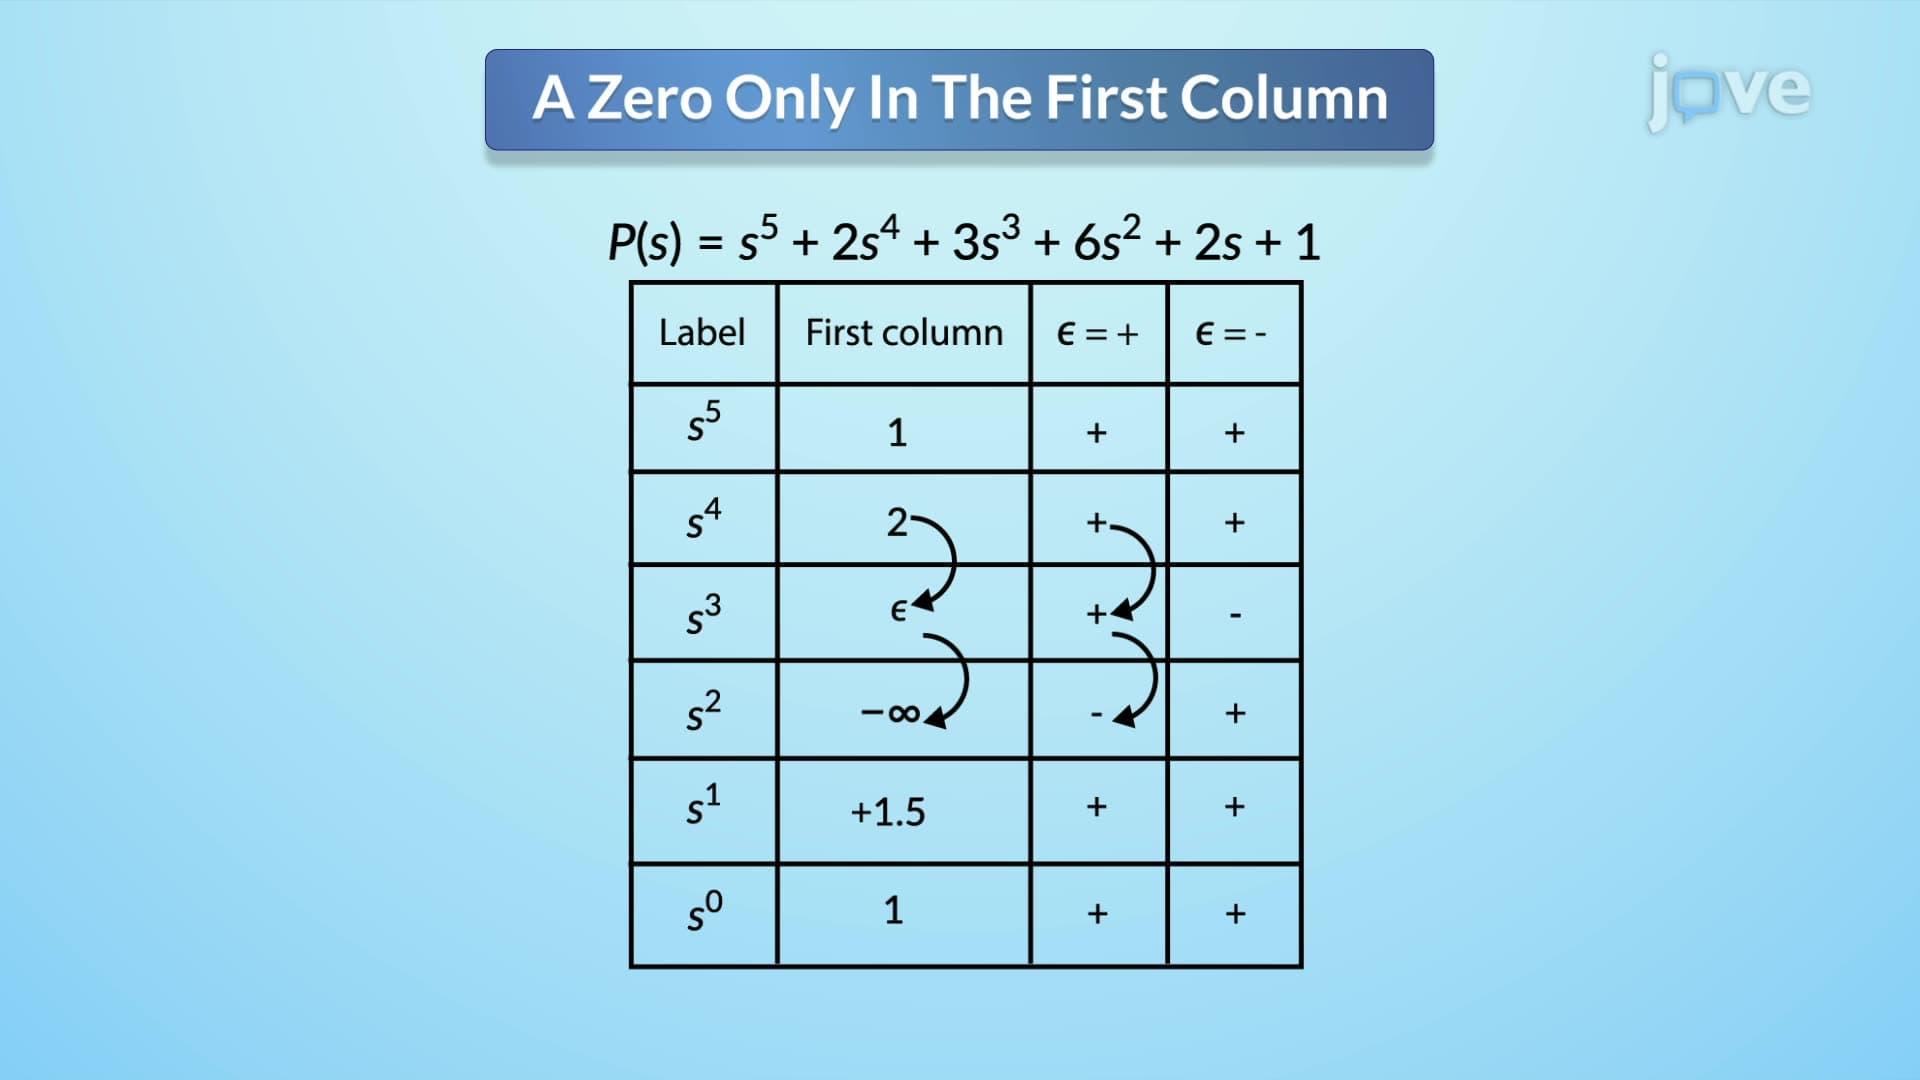
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:21
Linear Approximation in Time Domain
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length,...
 01:52
Regression Toward the Mean