Statistical mirroring-based ordinalysis: A sensitive, robust, efficient, and ordinality-preserving descriptive method for analyzing ordinal assessment data
Related Experiment Video
Updated: Sep 17, 2025
Measuring the Functional Abilities of Children Aged 3-6 Years Old with Observational Methods and Computer Tools
Published on: June 20, 2020
1Department of Biology, Faculty of Natural and Applied Sciences, Umaru Musa Yar'adua University, P.M.B., 2218 Katsina, Katsina State, Nigeria.

Abstract:
This study introduces statistical mirroring-based ordinalysis (SM-based ordinalysis), a novel, model-free, assumption-free, peer-independent, and descriptive statistical methodology for analyzing ordinal data at the individual level. The approach addresses key limitations of classical methods such as mean, median, and summed score techniques, particularly in terms of sensitivity, ordinality preservation, robustness, and interpretability. By integrating Kabirian-based isomorphic optinalysis with statistical mirroring, SM-based ordinalysis enhances the estimation process. Python code, packages, and a dedicated software application have been developed to promote accessibility and reproducibility. SM-based ordinalysis was validated through Monte Carlo simulations using data generated from normal, categorical, and multivariate model distributions. The proposed descriptive estimators demonstrated improved sensitivity to distributional variation, stronger ordinal preservation, probabilistic interpretability, scale robustness, and accuracy, especially in contexts with skewed data. SM-based ordinalysis is broadly applicable to fields such as clinical ordinal assessment, psychometrics, public health, market research, and survey analysis.•SM-based ordinalysis incorporates adaptive customization and optimization of parameters, statistical mirroring, and Kabirian-based isomorphic optinalysis to refine the analysis of ordinal scores within a set of composite assessments.•The descriptive estimators focus on analyzing statistical proximity or deviation of ordinal assessment scores from the highest positive ordinal scale point, unlike classical methods that rely mainly on descriptive positions of ordinal scores.
More Related Videos
 09:00
Author Spotlight: Validation of SICOLE-R for Assessing Cognitive and Reading Skills in Spanish-Speaking Children and Its Role in Personalized Education
Published on: August 16, 2024
 08:40
Isokinetic Robotic Device to Improve Test-Retest and Inter-Rater Reliability for Stretch Reflex Measurements in Stroke Patients with Spasticity
Published on: June 12, 2019
Related Concept Videos
 00:55
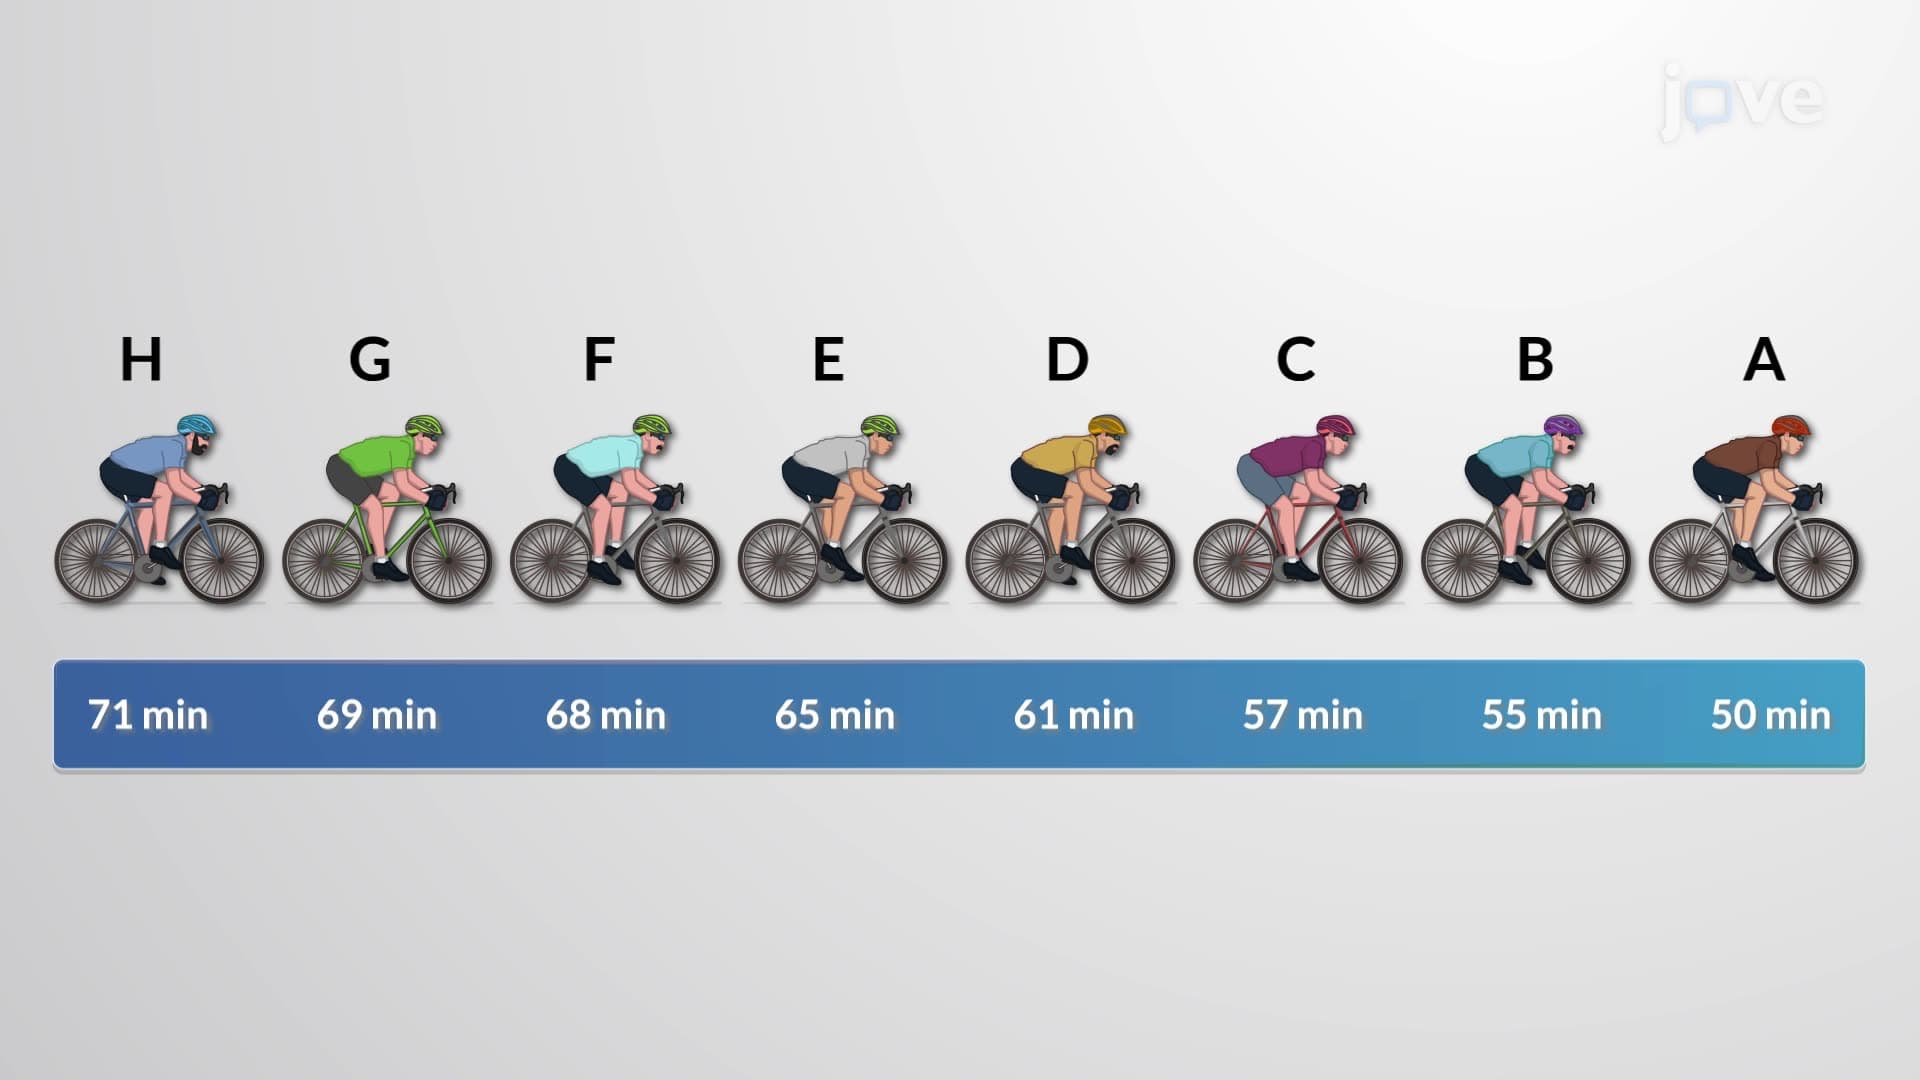
Ordinal Level of Measurement
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
 01:02
Ranks
 00:54
Ratio Level of Measurement
A set of data measured using the ratio scale takes care of the ratio problem and provides complete information. Ratio scale data are like interval scale data, except they have a zero point and ratios can be calculated....
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:10
Review and Preview
Percentiles are a type of fractile that partition data into...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...