Related Experiment Video
Updated: Sep 15, 2025


Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
A study of calibration as a measurement of trustworthiness of large language models in biomedical natural language
Rodrigo de Oliveira1, Matthew Garber2, James M Gwinnutt3
1IQVIA - Real World Solutions, London, W2 1AF, United Kingdom.

Objectives:
To assess the calibration of 9 large language models (LLMs) within biomedical natural language processing (BioNLP) tasks, furthering understanding of trustworthiness and reliability in real-world settings.
Materials And Methods:
For each LLM, we collected responses and corresponding confidence scores for all 13 datasets (grouped into 6 tasks) of the Biomedical Language Understanding & Reasoning Benchmark (BLURB). Confidence scores were assigned using 3 strategies: Verbal, Self-consistency, and Hybrid. For evaluation, we introduced Flex-ECE (Flexible Expected Calibration Error), a novel adaptation of ECE that accounts for partial correctness in model responses, allowing for a more realistic assessment of calibration in language-based settings. Two post-hoc calibration techniques-isotonic regression and histogram binning-were evaluated.
Results:
Across tasks, mean calibration ranged from 23.9% (Population-Intervention-Comparison-Outcome extraction) to 46.6% (Relation Extraction). Across LLMs, Medicine-Llama3-8B had the best mean overall calibration (29.8%), and Flan-T5-XXL had the highest ranking on 5/13 datasets. Across strategies, Self-consistency (mean: 27.3%) had better calibration than Verbal (mean: 42.0%) and Hybrid (mean: 44.2%). Post-hoc methods substantially improved calibration, with best mean calibrated Flex-ECEs ranging from 0.1% to 4.1%.
Discussion:
The poor out-of-the-box calibration of LLMs poses a risk to trustworthy deployment of such models in real-world BioNLP applications. Calibration can be improved post-hoc and is a recommended practice. Non-binary metrics for LLM evaluation such as Flex-ECE provide a more realistic assessment of trustworthiness of LLMs, and indeed any model that can be partially right/wrong.
Conclusion:
This study shows that out-of-the-box calibration of LLMs is very poor, but traditional post-hoc calibration techniques are useful to calibrate LLMs.
More Related Videos
 05:47
Evidence-based Knowledge Synthesis and Hypothesis Validation: Navigating Biomedical Knowledge Bases via Explainable AI and Agentic Systems
Published on: June 13, 2025
 06:18
Measurement of Specific Mycobacterial Mistranslation Rates with Gain-of-function Reporter Systems
Published on: April 26, 2019
Related Concept Videos
 01:12
Instrument Calibration
Analytical Balance Calibration
An analytical balance measures mass and requires regular calibration to...
 02:07
Improving Translational Accuracy
 01:10
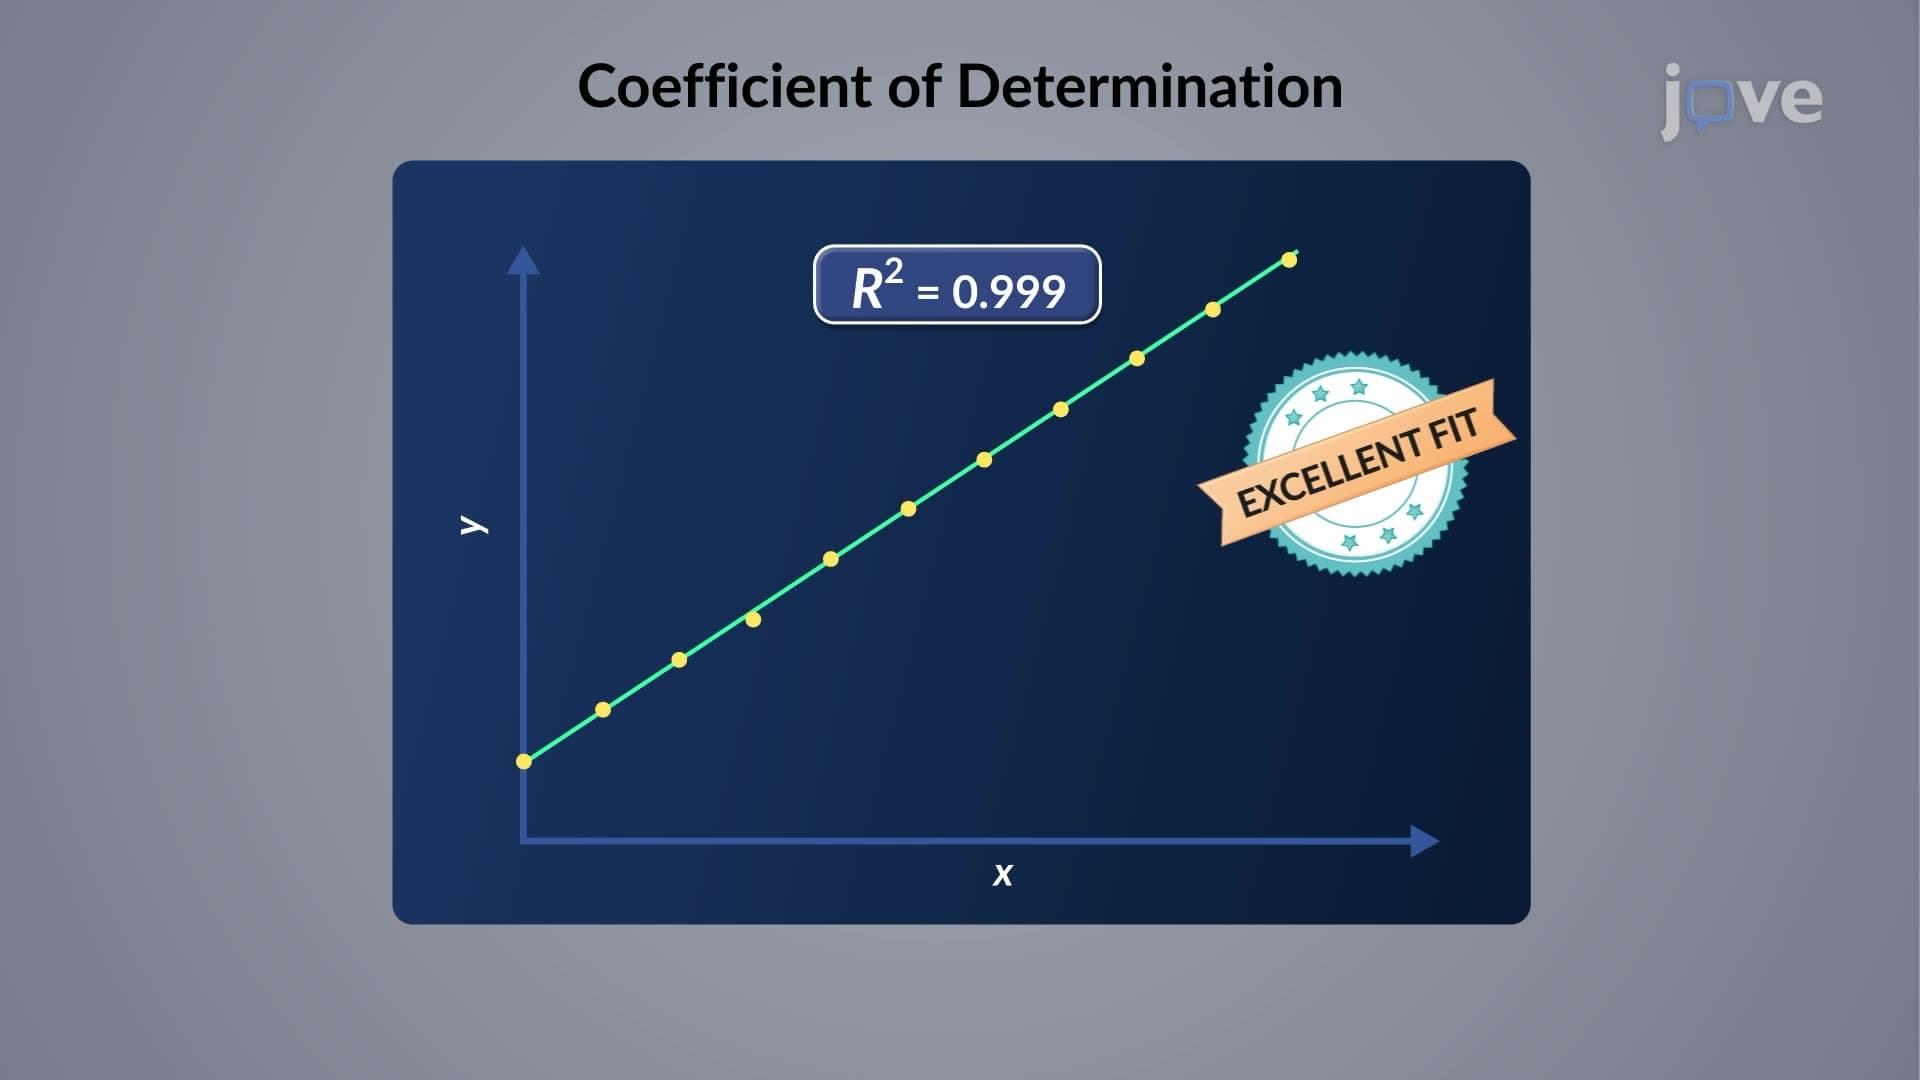
Calibration Curves: Correlation Coefficient
 01:20
Calibration Curves: Linear Least Squares
For data that follow a straight line, the standard method for fitting is the linear...
 01:52
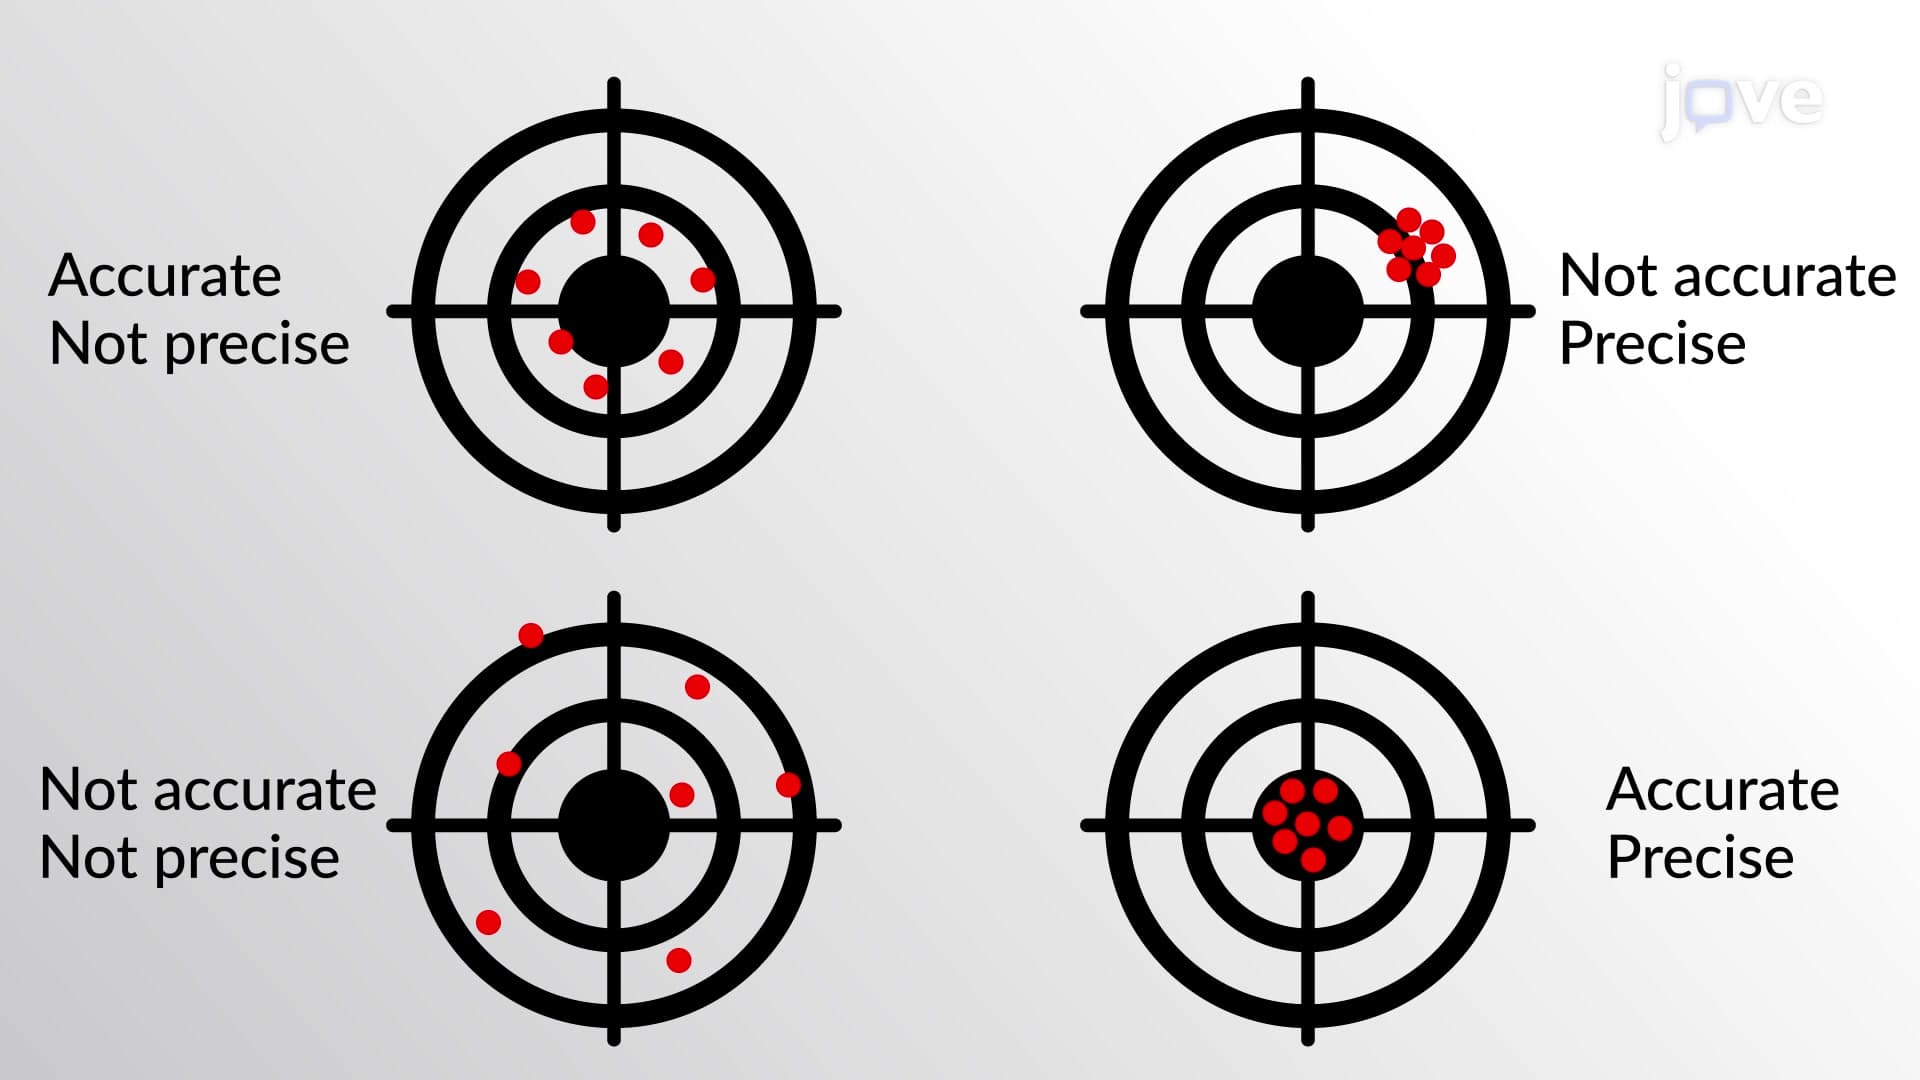
Accuracy and Precision
 03:37
Uncertainty in Measurement: Accuracy and Precision