Related Experiment Video
Updated: Sep 13, 2025

Original Experimental Approach for Assessing Transport Fuel Stability
Published on: October 21, 2016
SMILES Token Additivity Model with Interpretability and Generalizability for Fuel Property Predictions
Mengxin Yang1, Guanlin Song1, Longhui Cheng1
1School of Chemical Engineering, Sichuan University, Chengdu 610065, China.

Abstract:
Deep learning models for the quantitative structure-property relationship (QSPR) have traditionally encountered challenges related to limited interpretability and generalizability. In this study, we present the simplified molecular input line entry system (SMILES) token additivity (STA) model for accurately predicting fuel properties, which takes SMILES as input and employs stacked multihead self-attention encoders to extract molecular structural information. This model provides insights into the structure-property relationships by quantifying the contributions of individual tokens to target properties. Furthermore, since the STA model operates without handcrafted molecular fingerprints, it is capable of generalizing to a broad spectrum of structure-related properties. To validate the model's efficacy, seven critical fuel properties of standard enthalpy of formation (ΔfH°), entropy (S), isobaric heat capacity (Cp), cetane number (CN), boiling point (BP), melting point (MP), and flash point (FP) were tested. The 10-fold cross-validation demonstrated outstanding predictive accuracy, with mean absolute errors of 1.86 kcal/mol (ΔfH°), 0.62 kcal/mol/K (S), and 1.82 kcal/mol/K (Cp), alongside root-mean-square errors (RMSE) of 4.90 (CN), 11.27 °C (BP), 14.09 °C (MP), and 9.47 °C (FP). All properties achieved R2 values exceeding 0.95. The results demonstrate that it achieves predictive accuracy comparable to conventional machine learning models relying on sophisticated feature engineering while also identifying the effect of key tokens on ΔfH° and CN.
More Related Videos
 05:47
Evidence-based Knowledge Synthesis and Hypothesis Validation: Navigating Biomedical Knowledge Bases via Explainable AI and Agentic Systems
Published on: June 13, 2025
 07:24
Combustion Chemistry of Fuels: Quantitative Speciation Data Obtained from an Atmospheric High-temperature Flow Reactor with Coupled Molecular-beam Mass Spectrometer
Published on: February 19, 2018
Related Concept Videos
 01:14
Multicompartment Models: Overview
These models offer a more comprehensive representation of drug behavior in the body than one-compartment models. They accommodate the complexity of drug distribution,...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:13
Parameters Affecting Nonlinear Elimination: Zero-Order Input, First-Order Absorption and Two-Compartment Model
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
 01:22
Multi-input and Multi-variable systems
In the absence...
 01:17
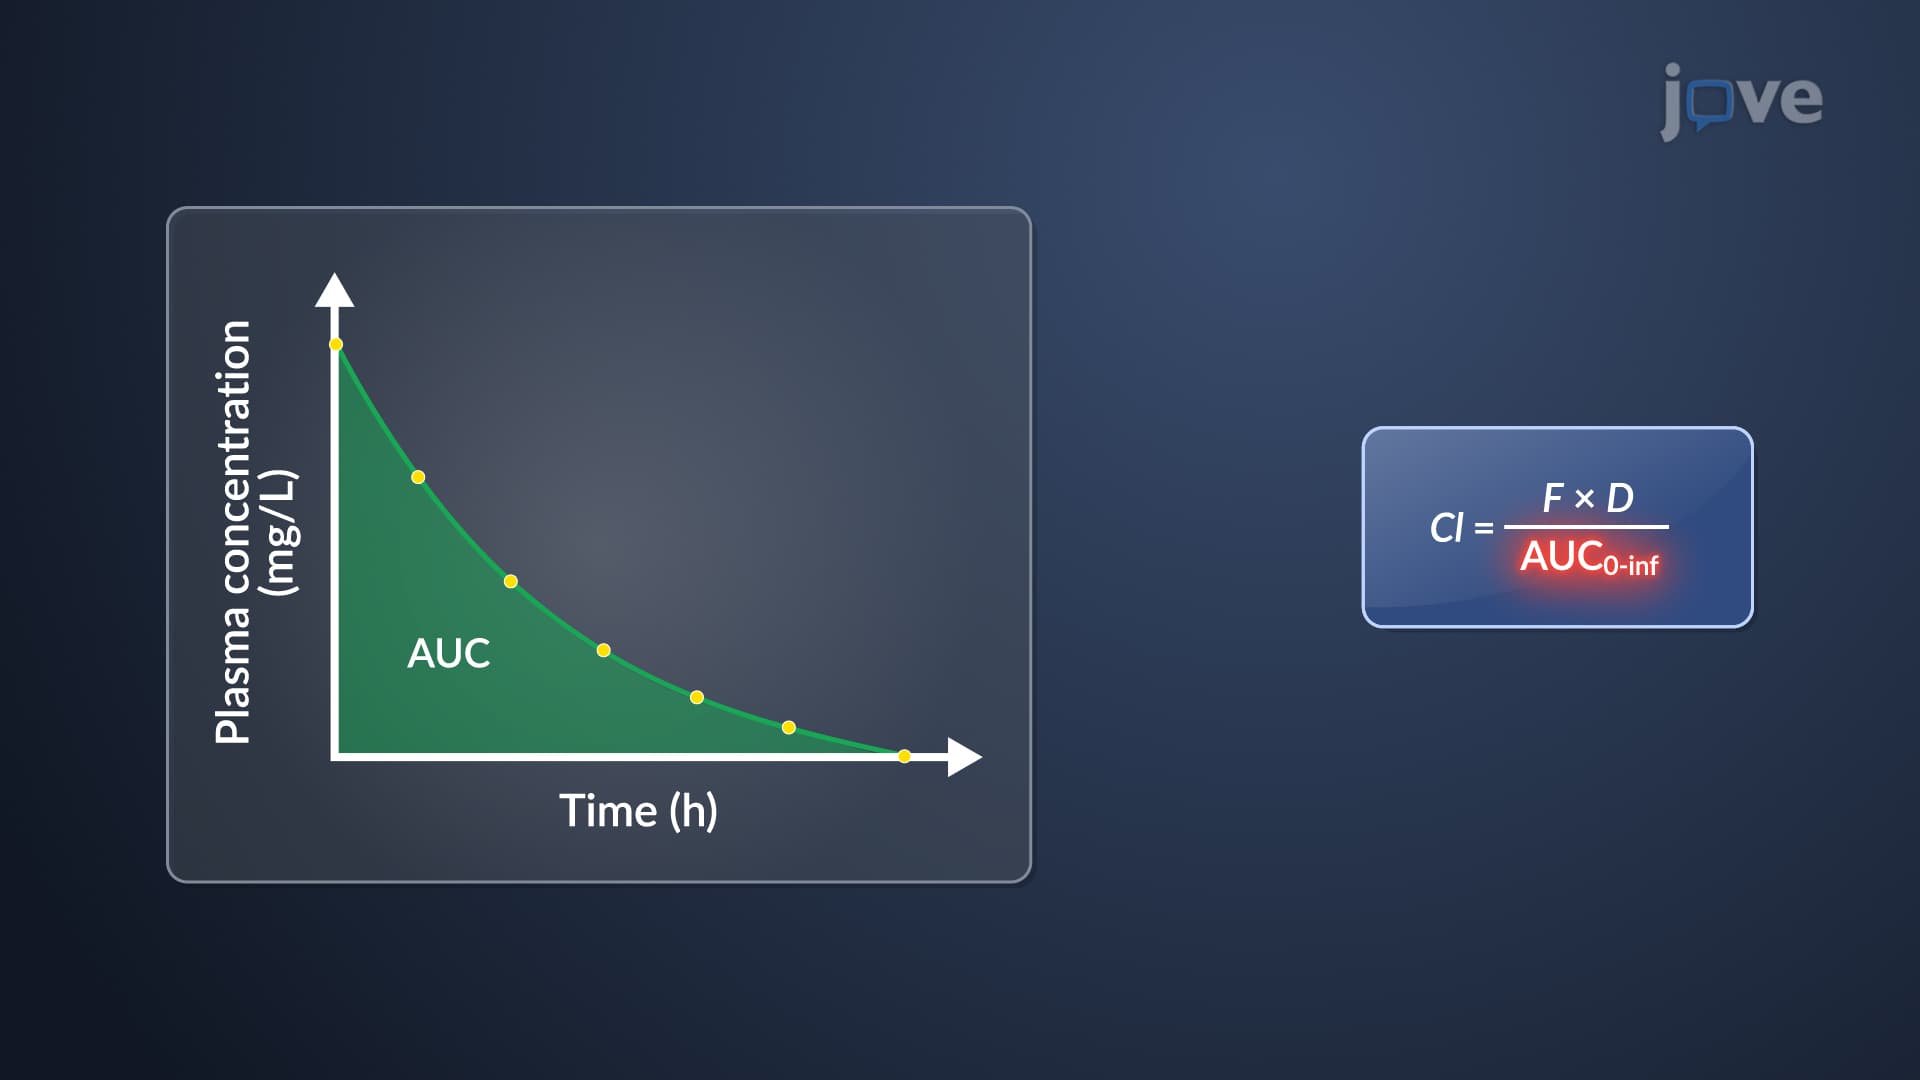
Clearance Models: Noncompartmental Models
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...