Related Experiment Video
Updated: Sep 13, 2025
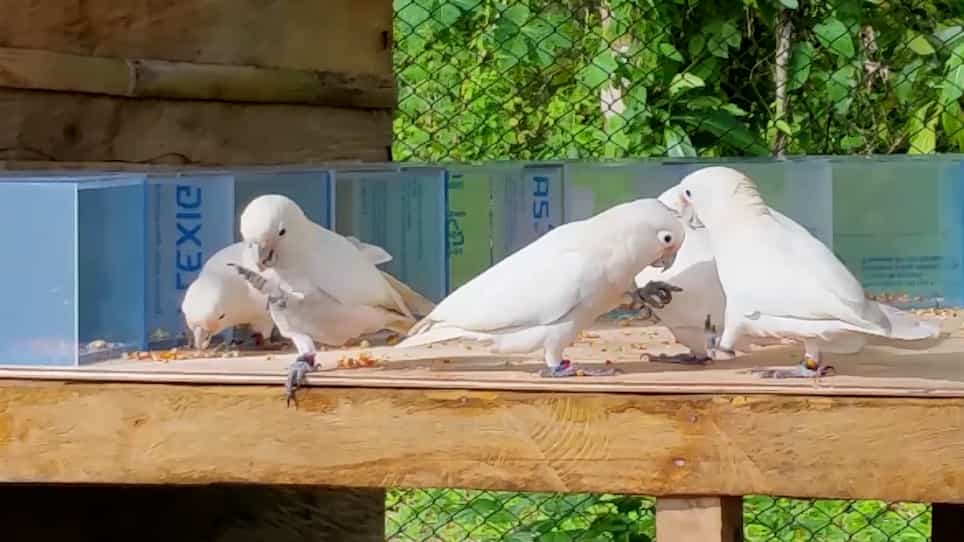

The Innovation Arena: A Method for Comparing Innovative Problem-Solving Across Groups
Published on: May 13, 2022
Valid and efficient inference for nonparametric variable importance in two-phase studies
Guorong Dai1, Raymond J Carroll2, Jinbo Chen3
1Department of Statistics and Data Science, School of Management, Fudan University, Shanghai 200433, China.

Abstract:
We consider a common nonparametric regression setting, where the data consist of a response variable Y, some easily obtainable covariates $\mathbf {X}$, and a set of costly covariates $\mathbf {Z}$. Before establishing predictive models for Y, a natural question arises: Is it worthwhile to include $\mathbf {Z}$ as predictors, given the additional cost of collecting data on $\mathbf {Z}$ for both training the models and predicting Y for future individuals? Therefore, we aim to conduct preliminary investigations to infer importance of $\mathbf {Z}$ in predicting Y in the presence of $\mathbf {X}$. To achieve this goal, we propose a nonparametric variable importance measure for $\mathbf {Z}$. It is defined as a parameter that aggregates maximum potential contributions of $\mathbf {Z}$ in single or multiple predictive models, with contributions quantified by general loss functions. Considering two-phase data that provide a large number of observations for $(Y,\mathbf {X})$ with the expensive $\mathbf {Z}$ measured only in a small subsample, we develop a novel approach to infer the proposed importance measure, accommodating missingness of $\mathbf {Z}$ in the sample by substituting functions of $(Y,\mathbf {X})$ for each individual's contribution to the predictive loss of models involving $\mathbf {Z}$. Our approach attains unified and efficient inference regardless of whether $\mathbf {Z}$ makes zero or positive contribution to predicting Y, a desirable yet surprising property owing to data incompleteness. As intermediate steps of our theoretical development, we establish novel results in two relevant research areas, semi-supervised inference and two-phase nonparametric estimation. Numerical results from both simulated and real data demonstrate superior performance of our approach.
More Related Videos
 08:36
Author Spotlight: Evaluating the Adjuvant Efficacy and Safety of Angong Niuhuang Pill in Viral Encephalitis Treatment
Published on: April 19, 2024
 09:35
A Protocol for Using Gene Set Enrichment Analysis to Identify the Appropriate Animal Model for Translational Research
Published on: August 16, 2017
Related Concept Videos
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:04
Significance Testing: Overview
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
 01:15
Study Design in Statistics
Does aspirin reduce the risk of heart attacks? Is one brand of fertilizer more effective at growing roses than another? Is fatigue as dangerous to a driver as the influence of alcohol? Questions like these are answered using randomized experiments with proper...
 01:20
Comparing the Survival Analysis of Two or More Groups