Related Experiment Video
Updated: Sep 12, 2025

Capillary Electrophoresis Mass Spectrometry Approaches for Characterization of the Protein and Metabolite Corona Acquired by Nanomaterials
Published on: October 27, 2020
Predicting the protein corona on nanoparticles using random forest models with nanoparticle, protein, and
Nicole Vijgen1, Karsten M Poulsen1, Gustavo Sosa Macias1
1Thomas Lord Department of Mechanical Engineering and Materials Science, Duke University Durham North Carolina 27708 USA christine.payne@duke.edu.

Abstract:
Nanoparticles (NPs) present in any biological environment form a "corona" of proteins on the NP surface. This protein corona, rather than the bare NP, determines the biological response to the protein-NP complex. Experiments, especially proteomics, can provide an inventory of proteins in the corona, but researchers currently lack a method to predict which proteins will interact with NPs. The ability to predict the protein corona would aid the design of NPs by decreasing the time and cost of experiments. We describe the development and use of random forest regression and classification models to predict protein abundance and enrichment, respectively, on the surface of NPs using a dataset of NP, protein, and experimental features. These models were trained using data generated in-house through the synthesis and functionalization of NPs with varied core material, surface ligand, diameter, and zeta potential. NPs were incubated with fetal bovine serum, a common protein source for cultured cells, to form a corona, which was characterized by proteomics. Both models identified protein abundance in the serum used to form the corona as the most significant predictor of corona proteins. NP zeta potential and hydrodynamic diameter emerged as the most important NP factors. The random forest regression model was used to test the ability to predict the protein corona of NPs that were excluded from the training data. We highlight the best and worst predictions. These findings offer a machine learning approach to guide experiments.

Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 02:24
Predicting Reaction Outcomes
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
 01:09
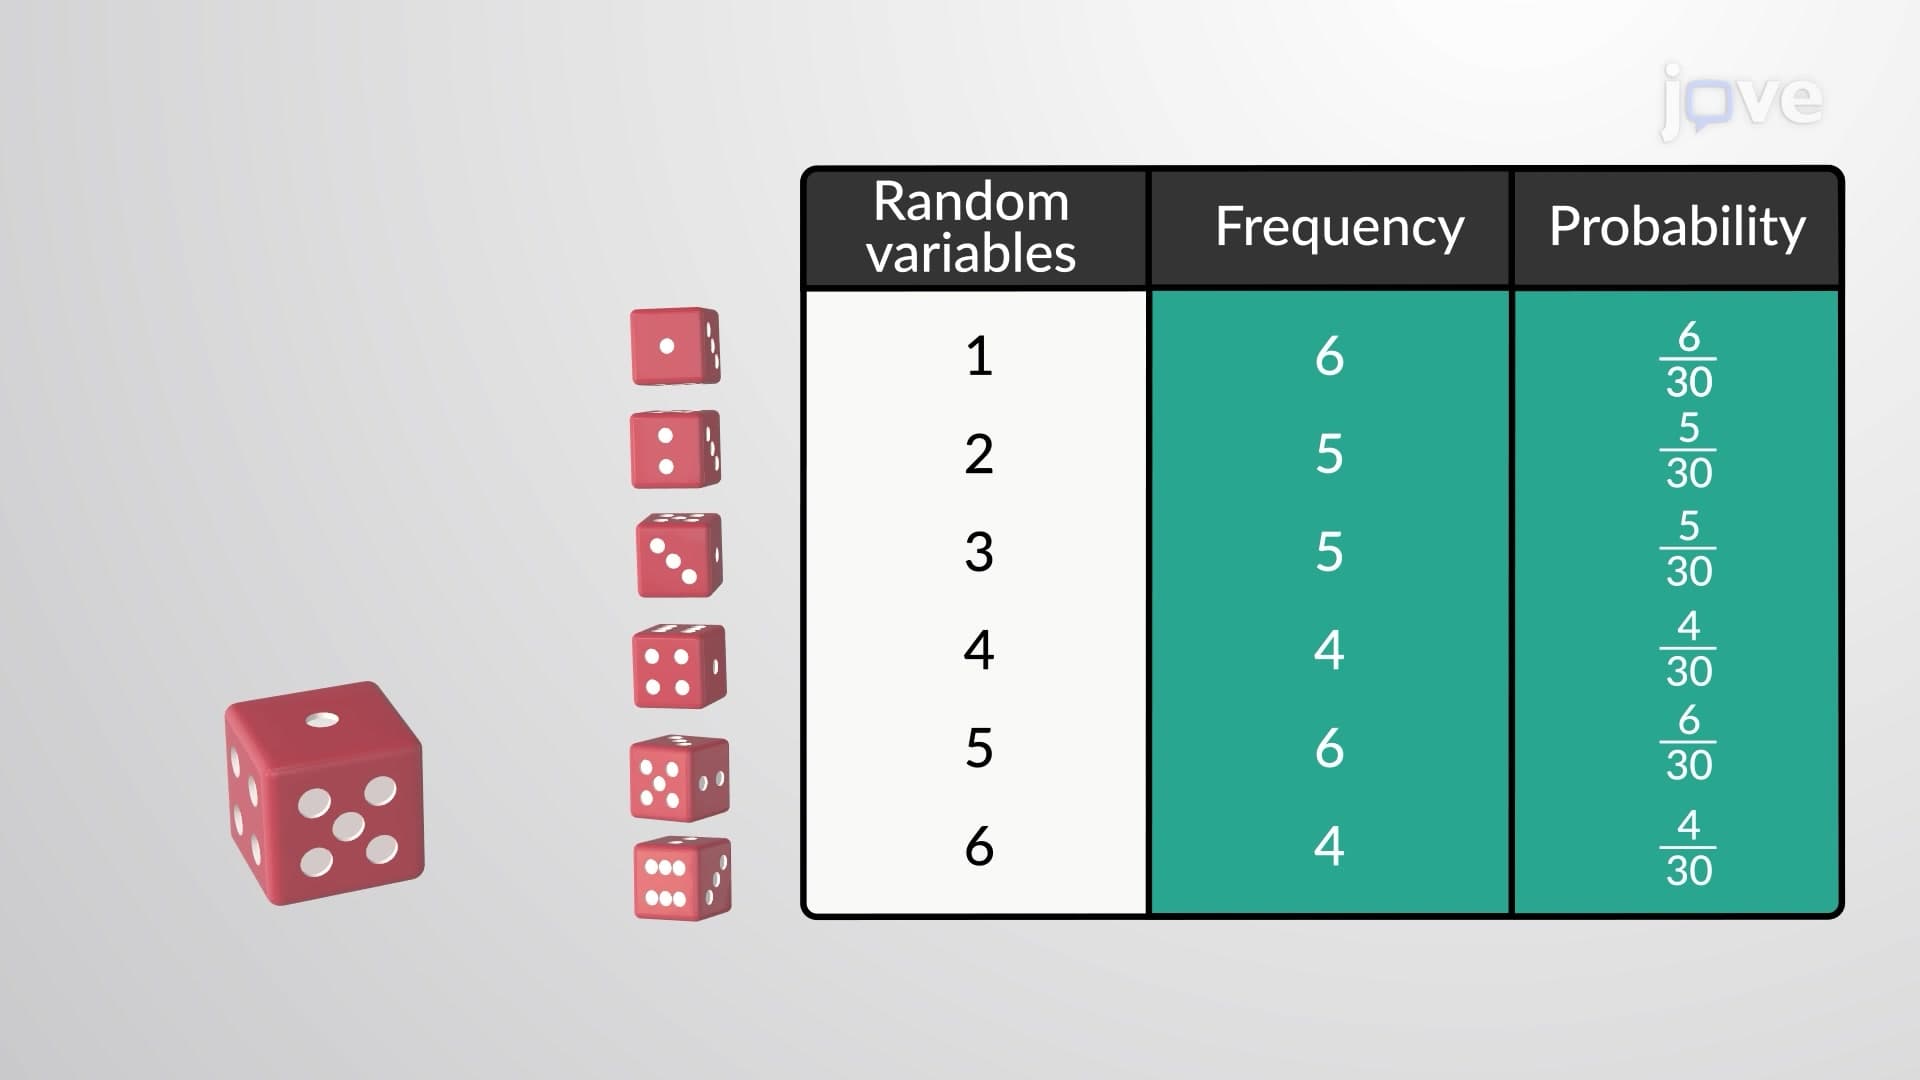
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...