Related Experiment Video
Updated: Sep 11, 2025
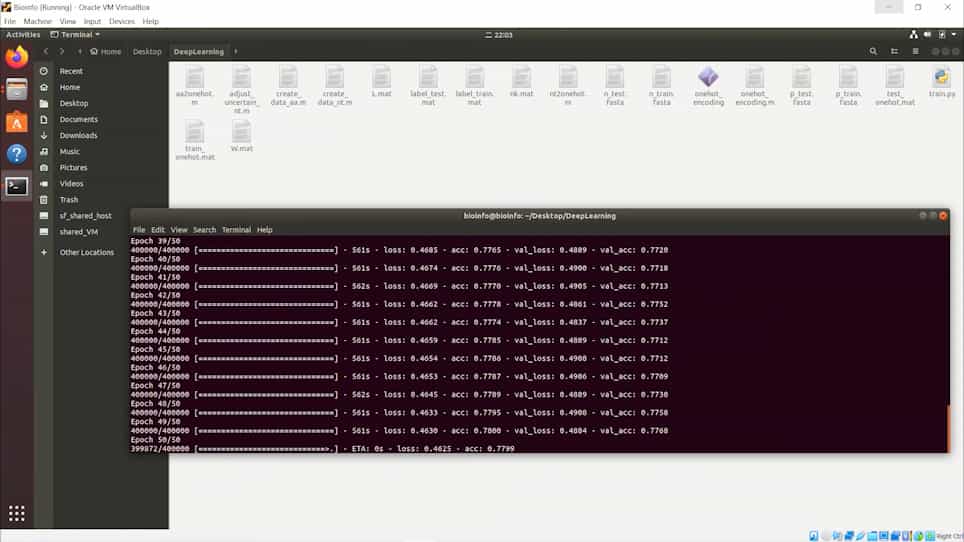

A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
Deep learning neural network development for the classification of bacteriocin sequences produced by lactic acid
Lady L González1, Isaac Arias-Serrano1, Fernando Villalba-Meneses1
1School of Biological Sciences and Engineering, University Yachay Tech, Urcuqui, Provincia de Imbabura, 100119, Ecuador.

Background:
The rise of antibiotic-resistant bacteria presents a pressing need for exploring new natural compounds with innovative mechanisms to replace existing antibiotics. Bacteriocins offer promising alternatives for developing therapeutic and preventive strategies in livestock, aquaculture, and human health. Specifically, those produced by LAB are recognized as GRAS and QPS. This study aims to develop a deep learning model specifically designed to classify bacteriocins by their LAB origin, using interpretable k-mer features and embedding vectors to enable applications in antimicrobial discover.
Methods:
We developed a deep learning neural network for binary classification of bacteriocin amino acid sequences (BacLAB vs. Non-BacLAB). Features were extracted using k-mers (k=3,5,7,15,20) and vector embeddings (EV). Ten feature combinations were tested (e.g., EV, EV+5-mers+7-mers). Sequences were filtered by length (50-2000 AA) to ensure uniformity, and class balance was maintained (24,964 BacLAB vs. 25,000 Non-BacLAB). The model was trained on Google Colab, demonstrating computational accessibility without specialized hardware.
Results:
The '5-mers+7-mers+EV' group achieved the best performance, with k-fold cross-validation (k=30) showing: 9.90% loss, 90.14% accuracy, 90.30% precision, 90.10% recall and F1 score. Folder 22 stood out with 8.50% loss, 91.47% accuracy, and 91.00% precision, recall, and F1 score. Five sets of 100 LAB-specific k-mers were identified, revealing conserved motifs. Despite high accuracy, sequence length variation (50-2000 AA) may bias k-mer representation, favoring longer sequences. Additionally, experimental validation is required to confirm the biological activity of predicted bacteriocins. These aspects highlight directions for future research.
Conclusions:
The model developed in this study achieved consistent results with those seen in the reviewed literature. It outperformed some studies by 3-10%. Its implementation in resource-limited settings is feasible via cloud platforms like Google Colab. The identified k-mers could guide the design of synthetic antimicrobials, pending further in vitro validation.
Related Concept Videos
 01:28
Methods of Classification and Identification
 01:29
Modern Molecular Taxonomy
 01:27
Bacterial Phylum Firmicutes
 01:20
Applications of Molecular Taxonomy
 01:30
Bacterial Phylum Actinobacteria
 01:13
Special Staining Techniques