Predictive modeling of significance thresholding in activation likelihood estimation meta-analysis
Lennart Frahm1,2, Kaustubh R Patil2,3, Theodore D Satterthwaite4,5
1Department of Psychiatry, Psychotherapy and Psychosomatics, School of Medicine, RWTH Aachen University, Aachen, Germany.

Abstract:
Activation Likelihood Estimation (ALE) employs voxel- or cluster-level family-wise error (vFWE or cFWE) correction or threshold-free cluster enhancement (TFCE) to counter false positives due to multiple comparisons. These corrections utilize Monte-Carlo simulations to approximate a null distribution of spatial convergence, which allows for the determination of a corrected significance threshold. The simulations may take many hours depending on the dataset and the hardware used to run the computations. In this study, we aimed to replace the time-consuming Monte-Carlo simulation procedure with an instantaneous machine-learning prediction based on features of the meta-analysis dataset. These features were created from the number of experiments in the dataset, the number of subjects per experiment, and the number of foci reported per experiment. We simulated 68,100 training datasets, containing between 10 and 150 experiments and computed the vFWE, cFWE, and TFCE significance thresholds. We then used this data to train one XGBoost regression model for each thresholding technique. Lastly, we validated the performance of the three models using 11 independent real-life datasets (21 contrasts) from previously published ALE meta-analyses. The vFWE model reached near-perfect prediction levels (R² = 0.996), while the TFCE and cFWE models achieved very good prediction accuracies of R² = 0.951 and R² = 0.938, respectively. This means that, on average, the difference between predicted and standard (monte-carlo based) cFWE thresholds was less than two voxels. Given that our model predicts significance thresholds in ALE meta-analyses with very high accuracy, we advocate our efficient prediction approach as a replacement for the currently used Monte-Carlo simulations in future ALE analyses. This will save hours of computation time and reduce energy consumption. Furthermore, the reduced compute time allows for easier implementation of multi-analysis set-ups like leave-one-out sensitivity analysis or subsampling.
More Related Videos
 07:28
Psychophysically-anchored, Robust Thresholding in Studying Pain-related Lateralization of Oscillatory Prestimulus Activity
Published on: January 21, 2017
 07:34
A Simple Stimulatory Device for Evoking Point-like Tactile Stimuli: A Searchlight for LFP to Spike Transitions
Published on: March 25, 2014
Related Concept Videos
 01:04
Significance Testing: Overview
 01:50
Statistical Significance
 01:16
Critical Region, Critical Values and Significance Level
In hypothesis testing, a sample statistic is converted to a test statistic using z, t, or chi-square distribution. A critical region is an area under the curve in probability distributions demarcated by the critical value. When the test statistic falls in this region, it suggests that the null hypothesis must be rejected. As this region contains all those values of the...
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...
 01:09
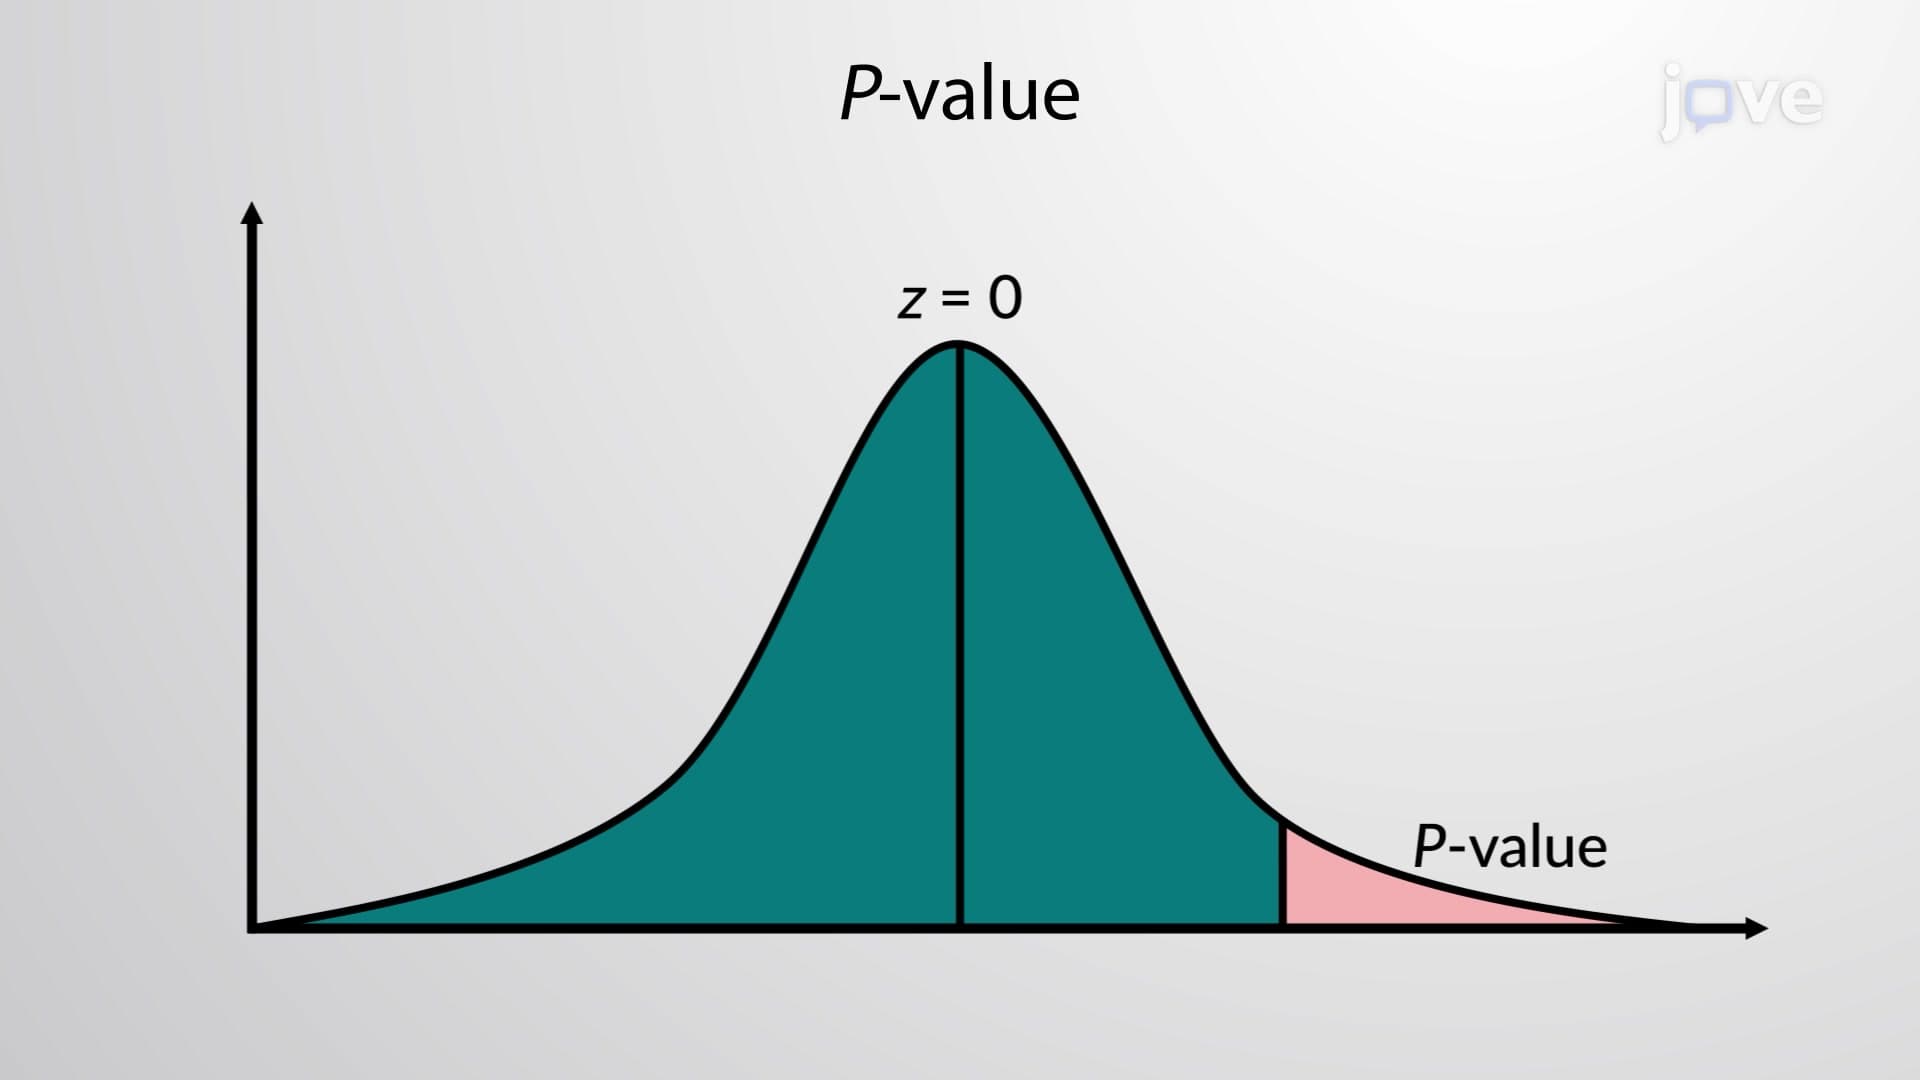
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...